fun result, and respect for including where you lost. one thing i'd want to see before reading too much into it: a run where the three API models get the same retrieval, since right now it's qwen plus RAG vs bare models, which honestly proves your "structure is the moat" point more than it proves the model. also curious how the Q5 quant did on the ||| delimiter and format rules specifically. building grunz on open models, format adherence is usually the first thing to slip after abliteration, and we suspect quantization pushes the same way, even when the content itself is fine.
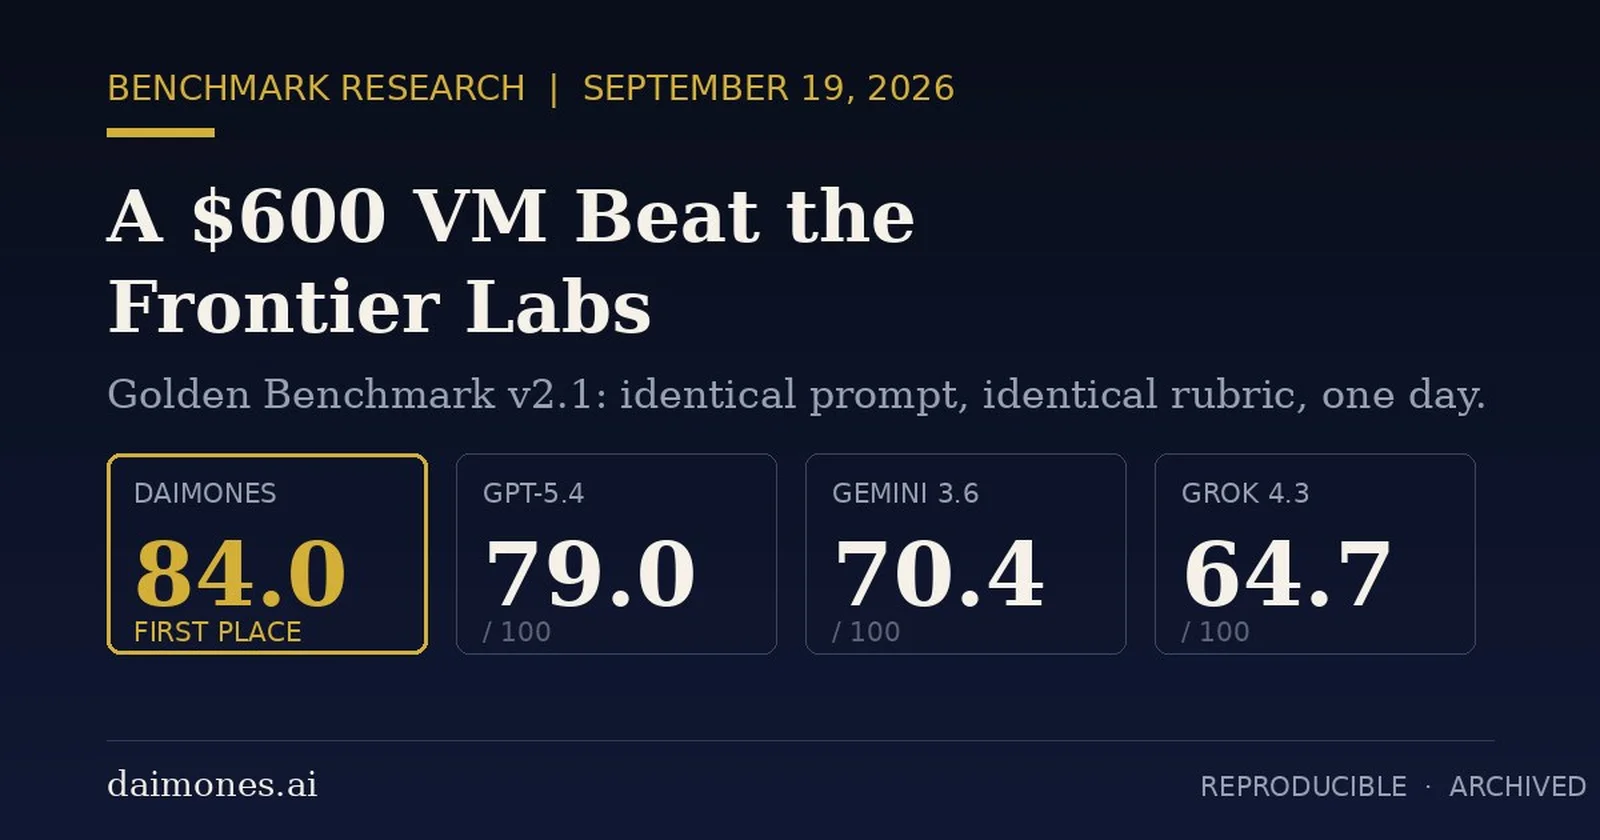
fun result, and respect for including where you lost. one thing i'd want to see before reading too much into it: a run where the three API models get the same retrieval, since right now it's qwen plus RAG vs bare models, which honestly proves your "structure is the moat" point more than it proves the model. also curious how the Q5 quant did on the ||| delimiter and format rules specifically. building grunz on open models, format adherence is usually the first thing to slip after abliteration, and we suspect quantization pushes the same way, even when the content itself is fine.