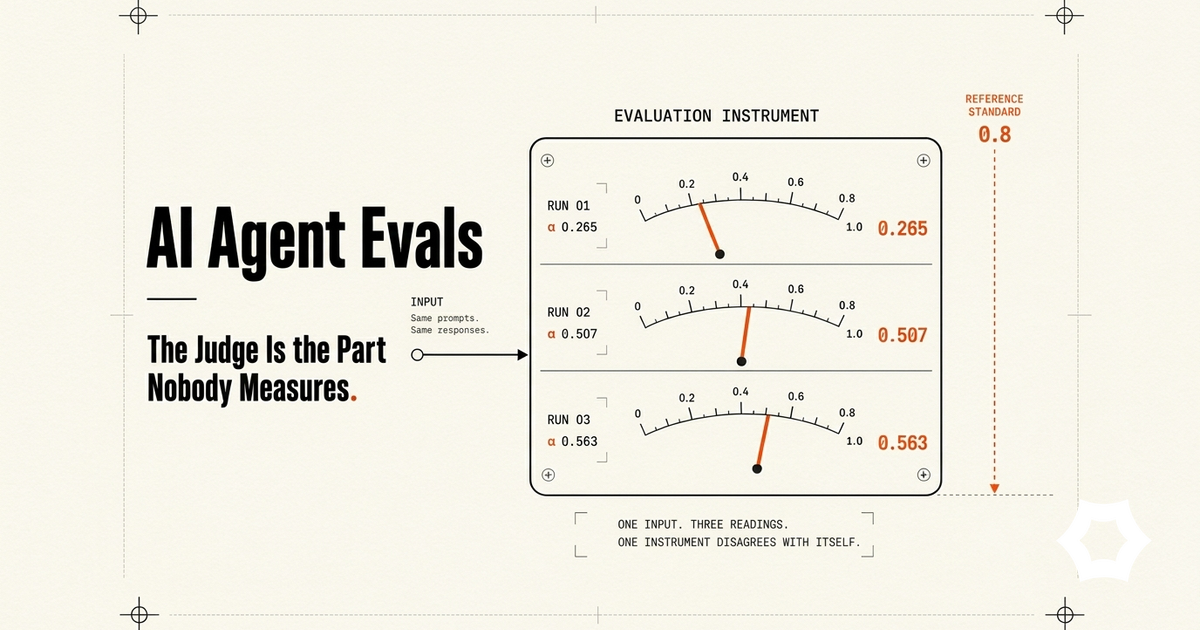
AI Agent Evals: The Judge Is The Part Nobody Measures
An LLM judge scoring the same agent output three times will often hand back three different answers. On MT-Bench, Rating Roulette measured intra-rater reliability across repeated runs at a Krippendorf
agent-memory-context-management.hashnode.dev20 min read