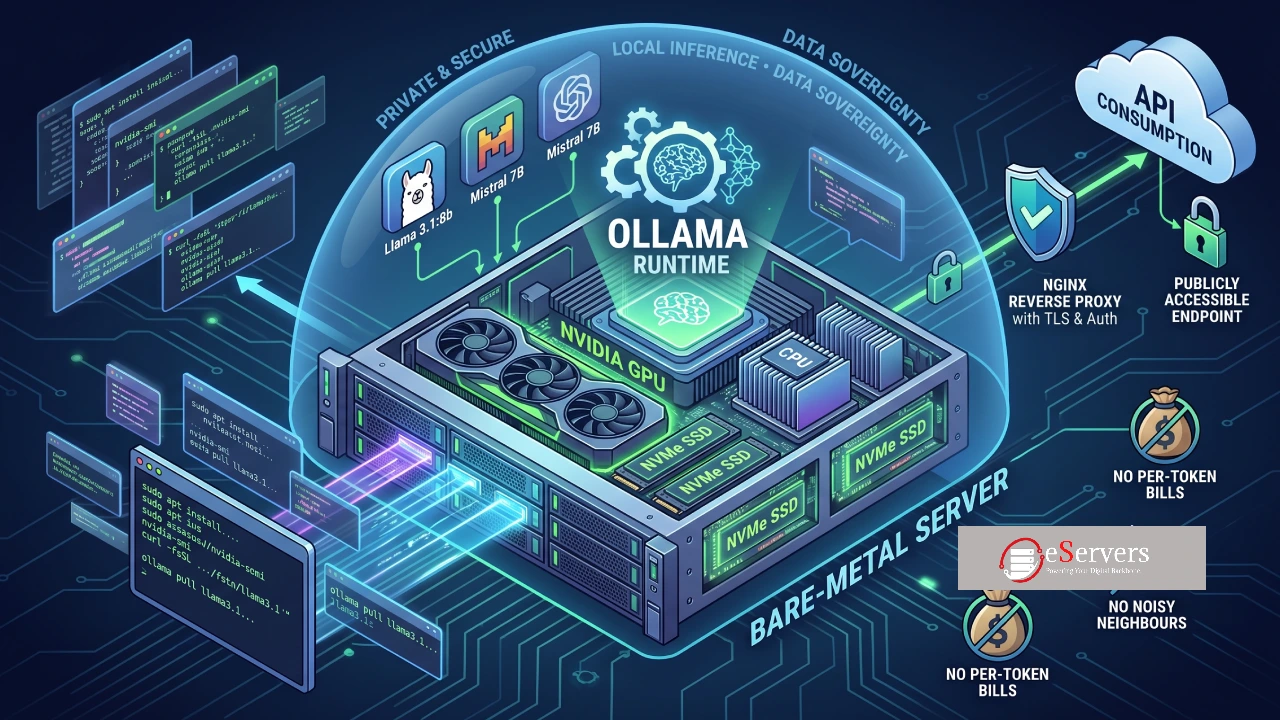
AI Engineering: Deploying Ollama for Local LLM Inference on Bare-Metal Infrastructure
Ollama is a lightweight local inference runtime that integrates model weights, a llama.cpp-based execution engine, and a REST API. Unlike heavy distributed training frameworks like PyTorch, Ollama is
eservers-uk.hashnode.dev2 min read