Sharing thought and experiences on AI and AI-assisted development
Markdown supported · ⌘↵ to post
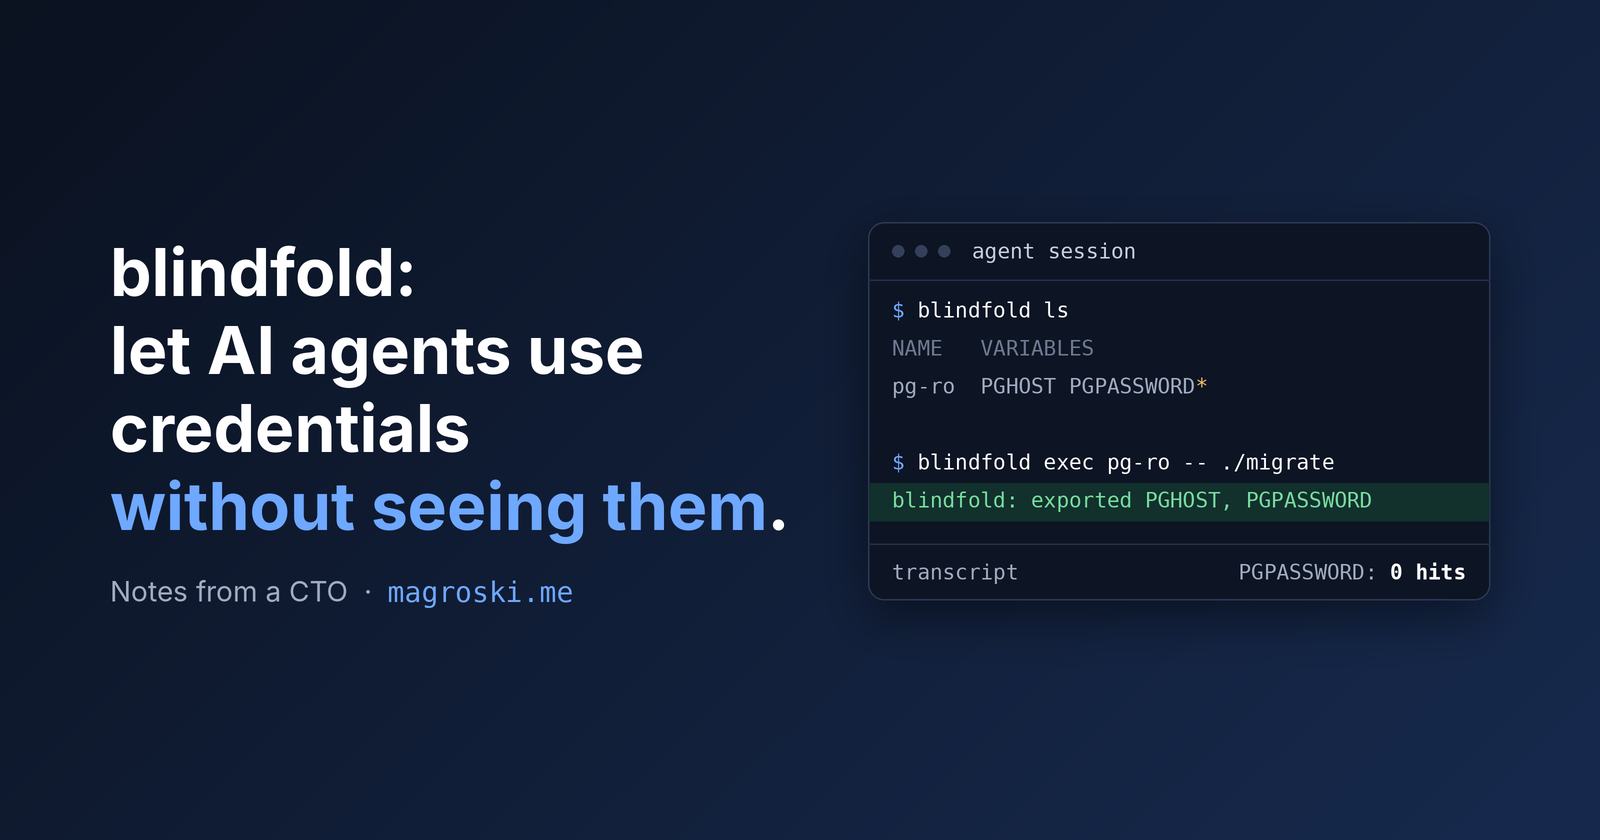
I like the idea of giving the command access to the secret, not the agent. I've seen how quickly .env becomes the easy way out when you're shipping fast. Making the safe path easier is the real win here.
One additional containment layer for agent-authored commands is outbound network policy. The wrapper keeps secrets out of transcripts, but a command that receives a credential can still send it to an unexpected host. A per-task allowlist of endpoints, with default-deny outbound access for the command sandbox, would limit where a leaked value can go. I work on Orke at BOMTOBE, a desktop workspace for coding-agent workflows, and this is a useful boundary to make explicit.
This is the cleanest take on the problem I've seen. Most advice stops at "don't paste secrets into the agent", which ignores how agents actually work — they need to make real API calls to do anything useful. Injecting short-lived credentials as env vars per invocation feels like the right granularity, and I'm glad you called out the redaction-in-prompt issue: once a credential value is visible in context, the transcript leak is already baked in. Curious how it handles tools that echo config back in their output — that feels like the next leak vector worth covering.
Puneet Khandelwal
Separating credentials from execution agents makes production setups way safer. It keeps tokens completely out of your application logic.