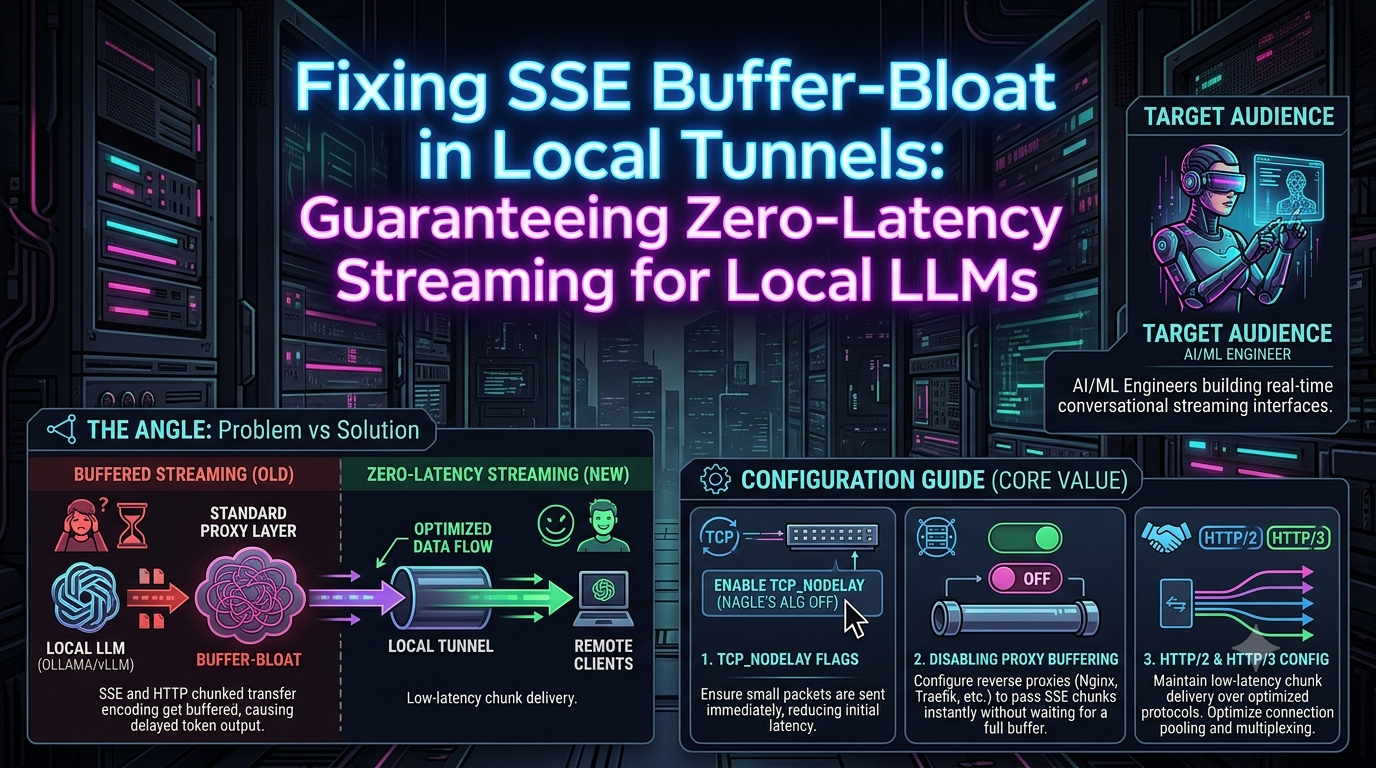
Fixing SSE Buffer-Bloat in Local Tunnels: Guaranteeing Zero-Latency Streaming for Local LLMs
You’ve just deployed a state-of-the-art local LLM using vLLM, Ollama, or llama.cpp. When you test it on localhost, the token generation is a thing of beauty—a smooth, continuous stream of text that fe
instatunnel.hashnode.dev8 min read