FeedDiscussion
From SFT to DPO to RLHF: a Deep Guide to LLM Alignment & Preference Optimization
Why this exists Pretraining teaches a model to continue text; alignment teaches it to behave the way users want (helpful, honest, harmless, on-style, and on-policy). We do that with post-training: supervised data, preferences, rules, and sometimes re...
tokenbytoken.hashnode.dev9 min read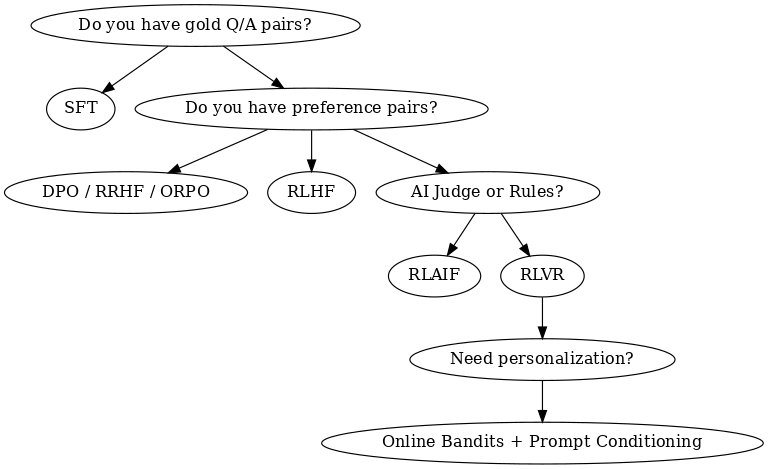
#reinforcement-learning#machine-learning#deep-learning#ai#agentic-ai#software-development#guardrails#generative-ai#llm#responsibleai
Responses
No responses yet.