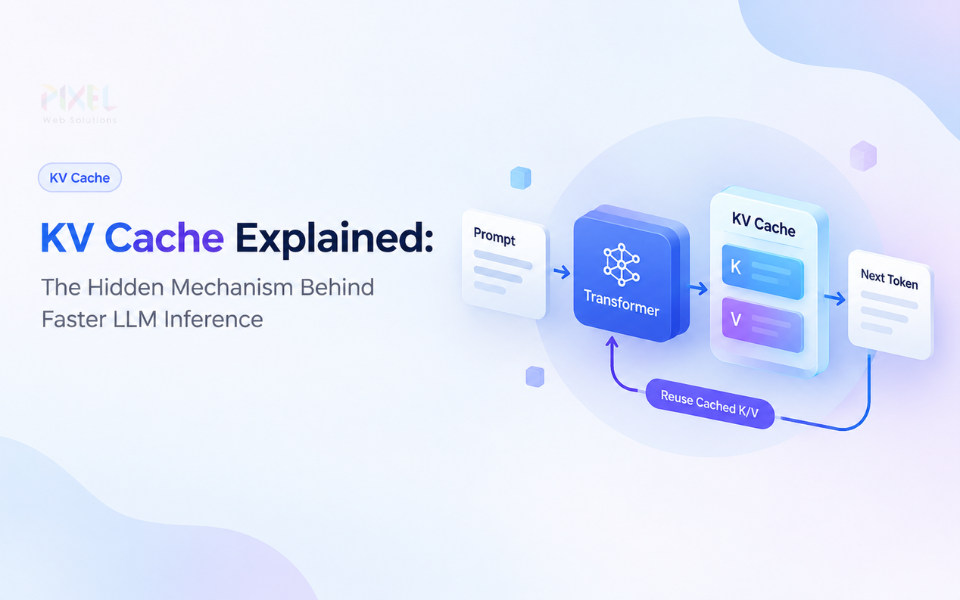
How KV Cache Reduces Redundant Computation During LLM Token Generation
Explore how KV Cache reduces redundant computation in LLM inference, speeds up token generation, and manages memory in production systems efficiently.
Written by
CTO and technology professional with a focus on innovation, software engineering, and emerging technologies. I’m passionate about exploring new ideas, sharing industry insights, and understanding how technology can solve real-world challenges and create meaningful impact.
Responses
Markdown supported · ⌘↵ to post
No responses yet.