Search posts, tags, users, and pages
Het Dave
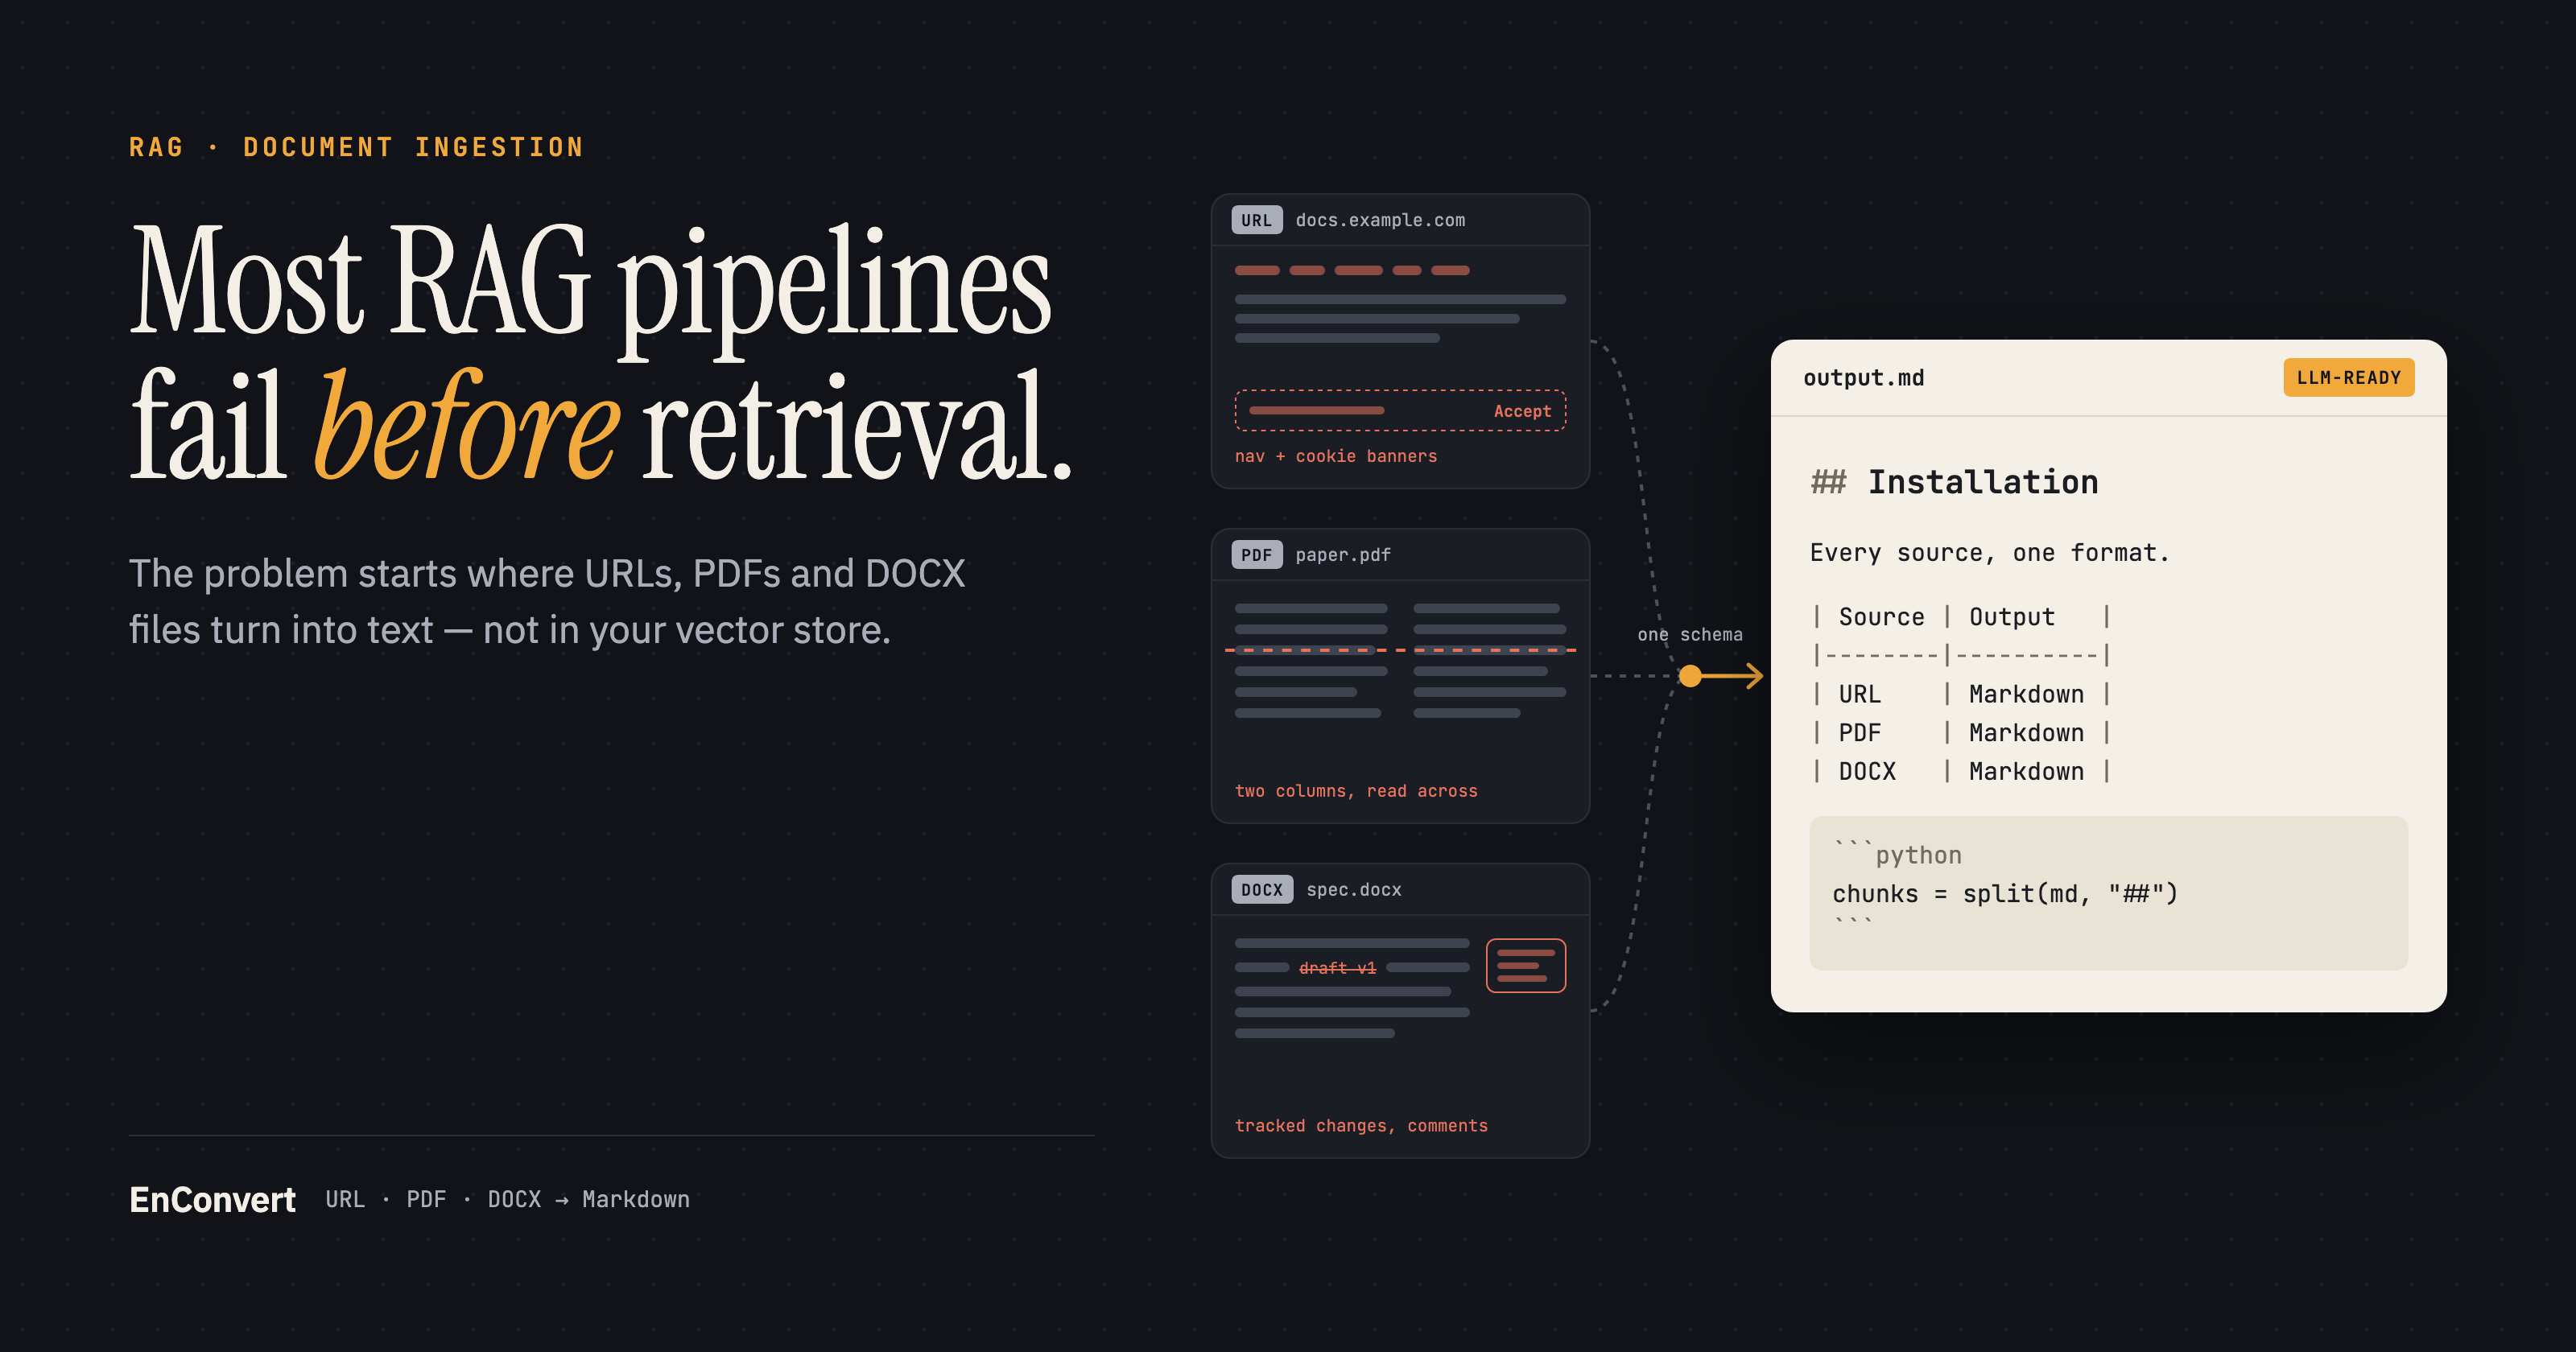
Most RAG pipelines do not fail at the vector store. They do not fail at retrieval. They fail before any of that: at the point where content moves from a URL, a PDF, or a DOCX file into something a mod
Brian · AI News
AI news notes on model rumors and what actually shipped.
Caching embeddings by content hash saved me more than any model swap. Same chunk in, same vector out, and reindexing stops eating the budget.
That is indeed true, and is almost always the best method to reduce costs. On a side note, we use this exact same method in one of our other endpoint 'Watch' to detect whether the content of a website has changed or not.
Brian · AI News
AI news notes on model rumors and what actually shipped.
Caching embeddings by content hash saved me more than any model swap. Same chunk in, same vector out, and reindexing stops eating the budget.