INT8 Quantization the Second Time Around
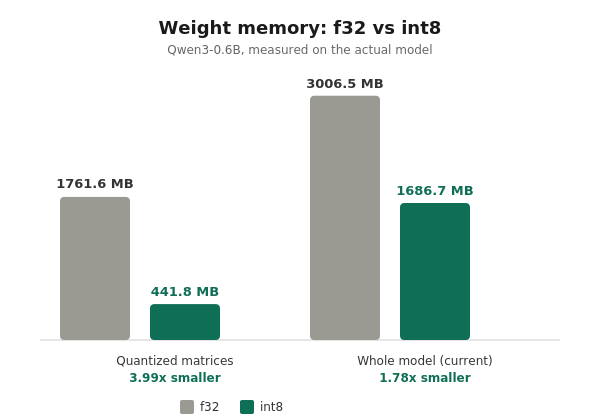
I quantized my inference engine's weights to int8 — and almost led with the wrong number before the process itself caught a real bug.
Written by
C++/CUDA Engineer · LLM Inference & Systems
C++/CUDA engineer building LLM inference and GPU code from scratch: verbum.cpp, Lattice, RAAG. 2 CUDA PRs merged into llama.cpp. I write about inference, GPU performance, and measuring things honestly.
Responses
Markdown supported · ⌘↵ to post
No responses yet.