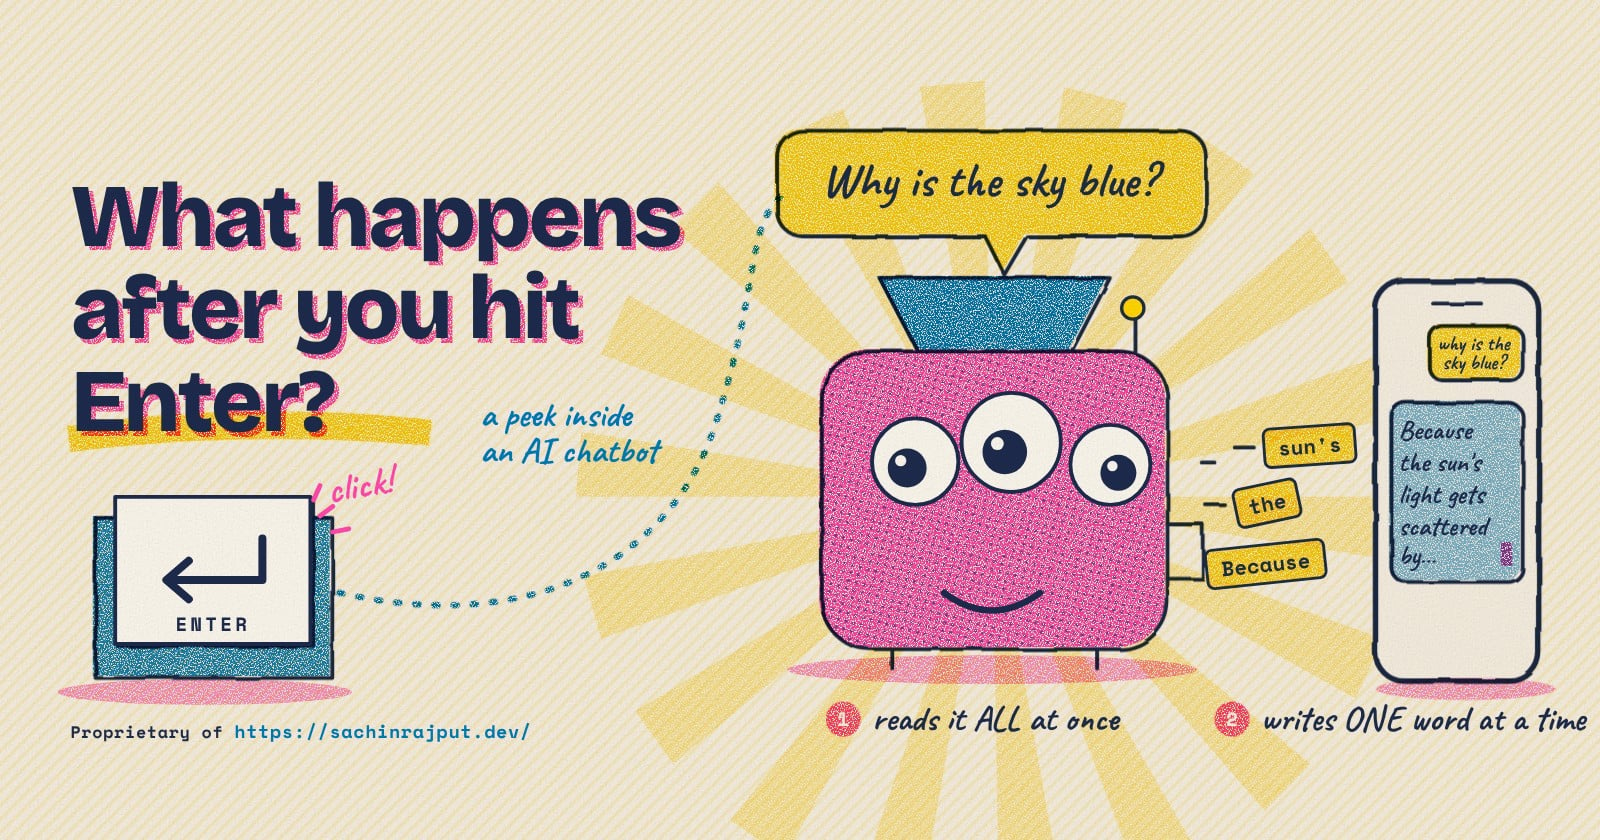
One Request, End to End: Tokenize, Prefill, Decode, Stream
What really happens in the second after you ask a chatbot a question? A trip through the Word Factory, explained simply.
Written by
AI Inference & LLM Serving Engineer · latency, throughput & cost per token
I build and measure LLM inference systems: latency, throughput and cost per token for production LLMs. 15 years of low-latency systems, 13 LLM systems in production. I write about what really happens inside the machine, with code you can run. Main blog: https://blog.sachinrajput.dev
Responses
Markdown supported · ⌘↵ to post
No responses yet.