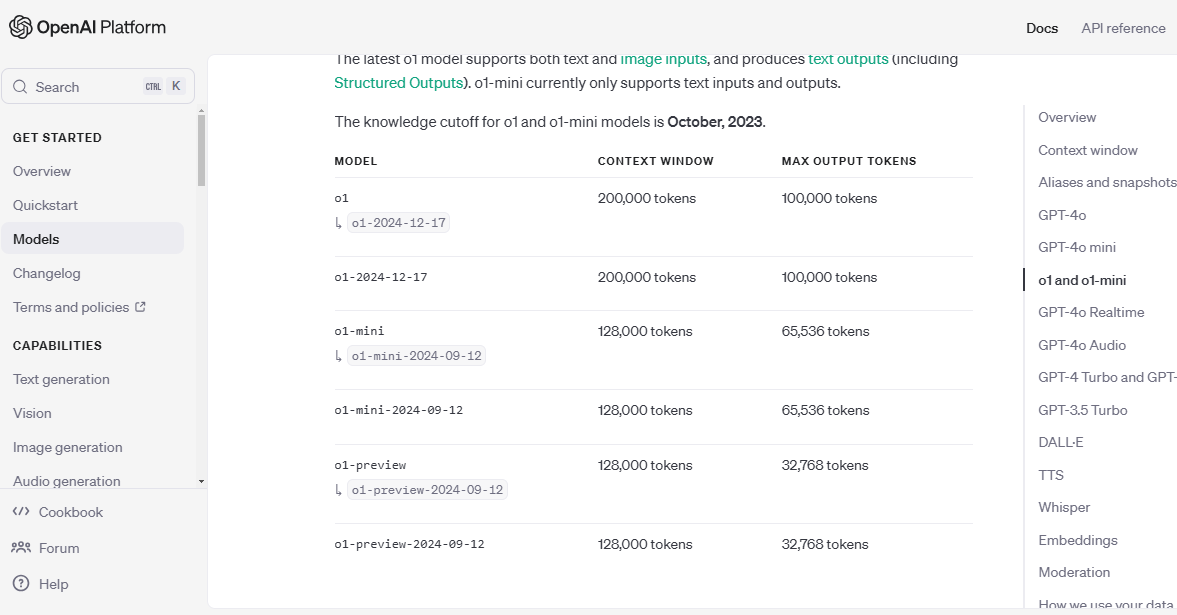
OpenAI Just Dropped a New ChatGPT Reasoning Model With 100k Output Tokens
The o1 series of models are trained with reinforcement learning to perform complex reasoning. o1 models think before they answer, producing a long internal chain of thought before responding to the user. Learn about the capabilities of o1 models in o...
Written by
Responses
Markdown supported · ⌘↵ to post
No responses yet.