FeedDiscussion
Securing Apps: Password Hashing, RBAC, OAuth, and OpenID Connect
It is 11 at night. Dinner is done, lights are off, and I am in bed with my MacBook Air propped up and my Crinacle Zero 2 IEMs plugged straight into the 3.5mm jack. Netflix is open, The East Palace is
ayushjjainn.hashnode.dev44 min read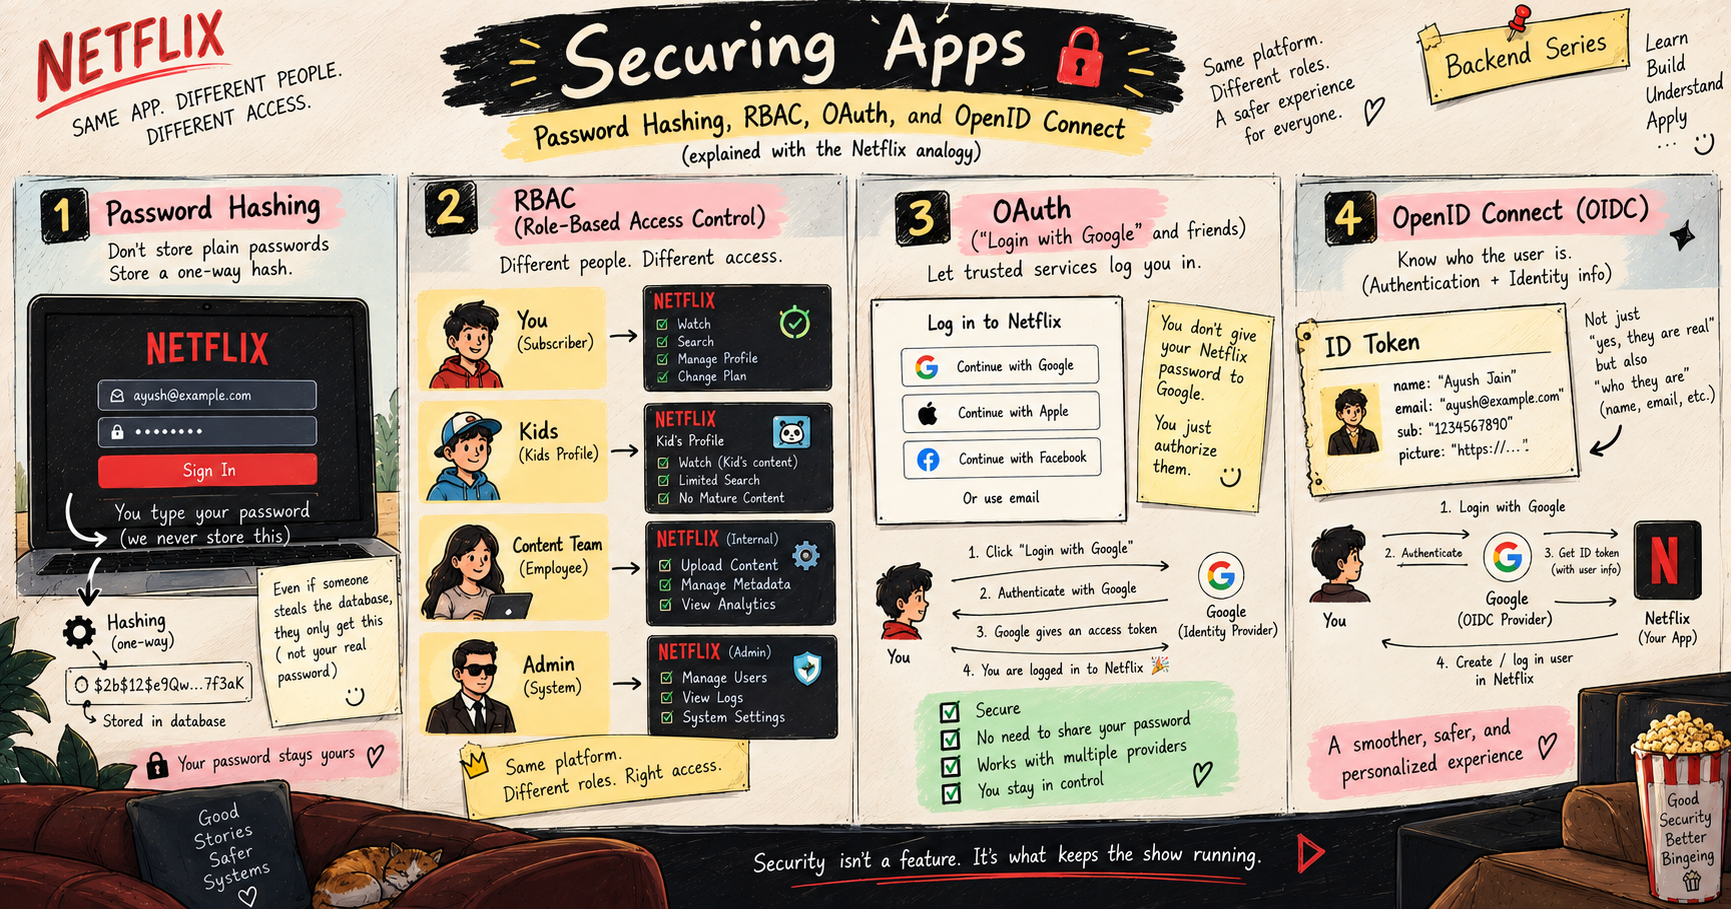
#oidc#oauth#oauth2#backend-development#coding#programming-blogs#software-development#rbac#openid-connect#web-development#webdev
Good rundown, especially the RBAC role-explosion section. One thing worth adding to the "return one identical message" habit: matching the error text is necessary but not sufficient if the two code paths take different amounts of time. Looking up a user and then running bcrypt costs real milliseconds, so a login endpoint that only calls bcrypt when the email exists leaks that difference through response timing even with identical error strings. The usual fix is to always run a bcrypt compare against a fixed dummy hash when the email isn't found, so both paths cost roughly the same and timing can't be used to enumerate valid emails.