FeedDiscussion
Kartik N V J K
AI Developer | Making AI reliable, trustworthy & accessible to everyone | Active community contributor
Good rundown of the retrieval-vs-generation split, that's the part most RAG writeups blur together. One thing worth adding to "where teams get this wrong": the ground truth itself is only as stable as the chunking scheme it was labeled against. expected_chunk_ids pinned to one chunking strategy don't reliably still point at the same content after you change chunk boundaries, so a before/after recall@k comparison across a chunking change can be comparing against a stale definition of "the right chunk" rather than the new one, unless the ground truth gets re-derived by content match rather than trusted by ID. And on the LLM-judge faithfulness check, it's worth calibrating the judge itself before trusting it across the whole eval set — run it against a small hand-labeled set of known SUPPORTED/UNSUPPORTED cases first. A judge that's quietly biased toward SUPPORTED (a common failure mode) will launder unfaithful answers through a metric that looks like it's catching them.
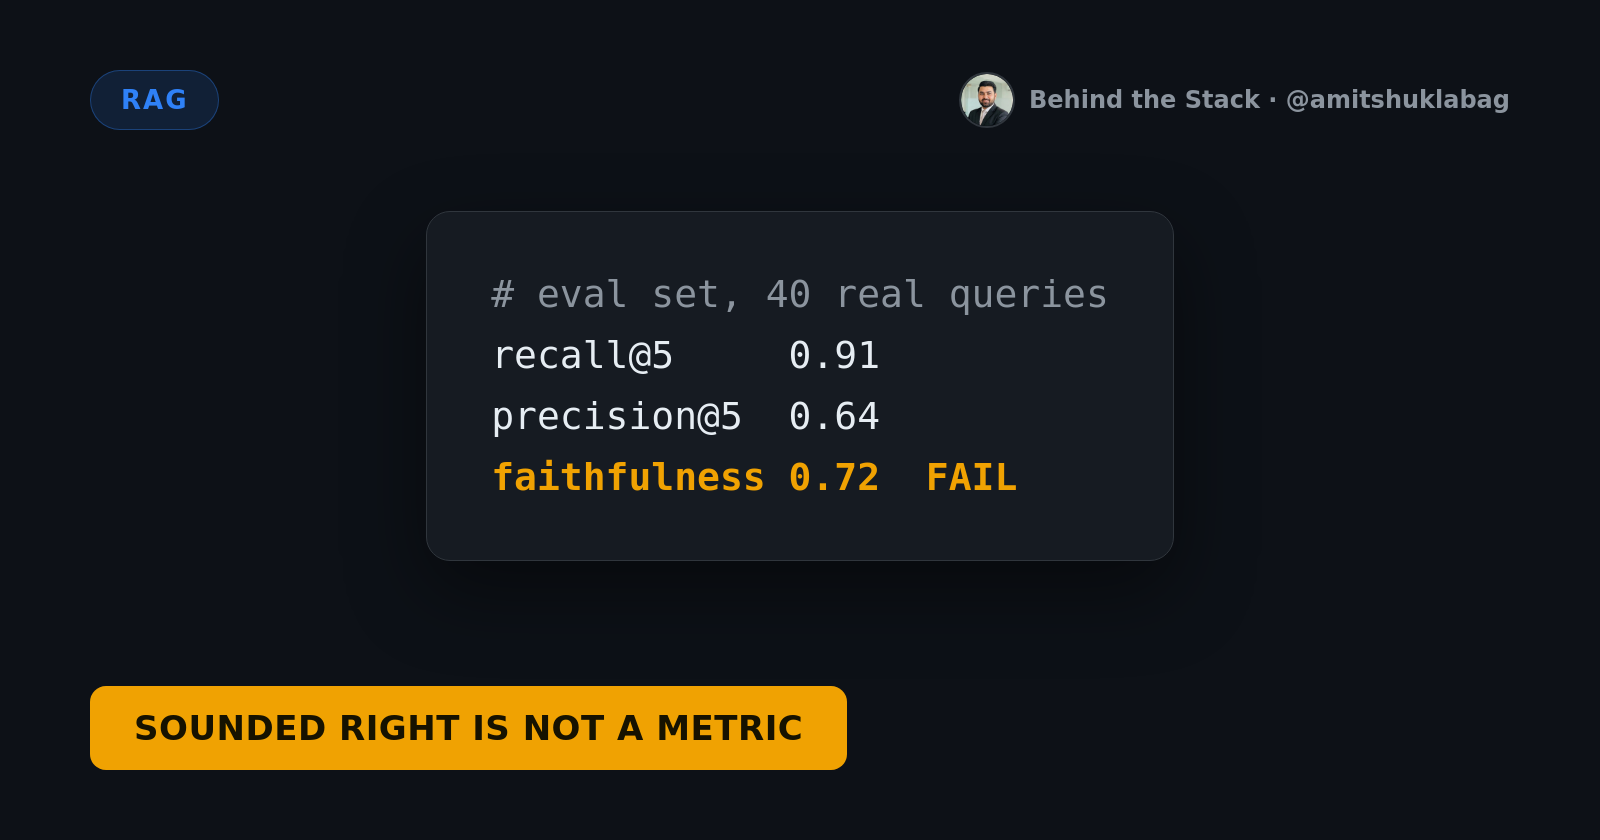
Your point that a generation problem downstream of a retrieval miss looks identical to a bad prompt is exactly what wasted a week for me once. I now split the eval so a low recall@k fails loud before I ever touch the prompt, otherwise I kept tuning the generator for a chunk it never received. I wrote about that split here: kartiknvjk.hashnode.dev/how-i-stopped-my-rag-ci-g… . How do you keep your expected_chunk_ids fresh when the chunking strategy changes?