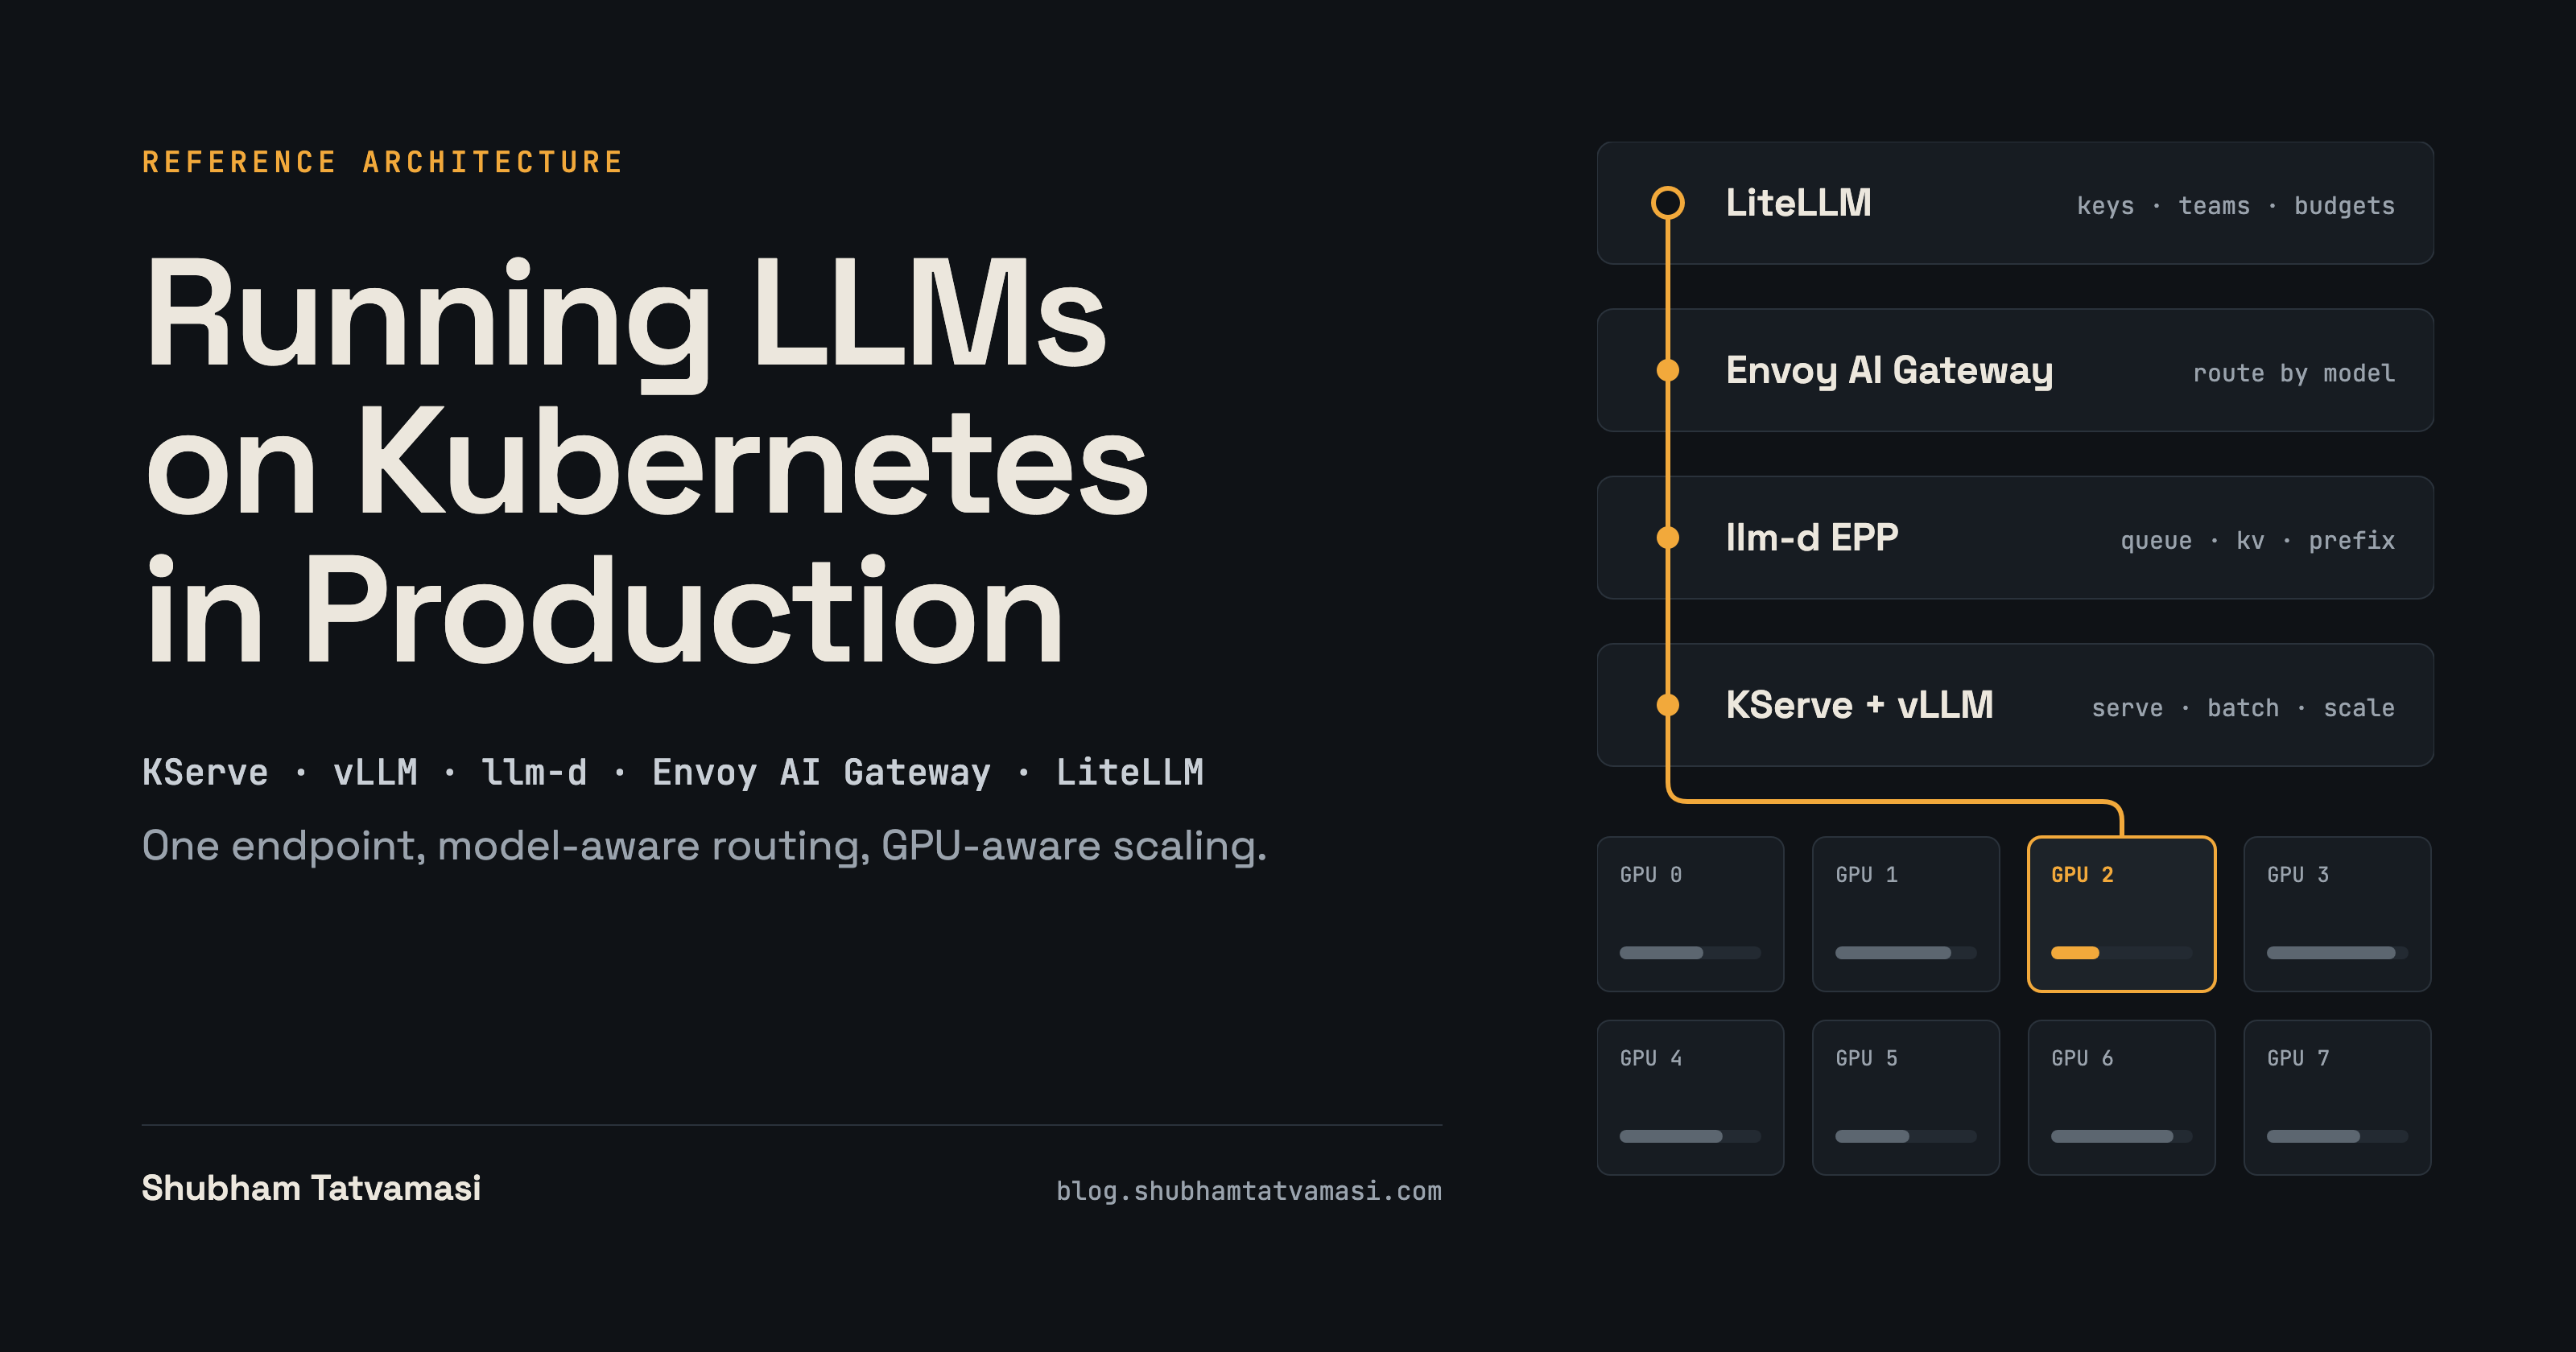
Running LLMs on Kubernetes in Production: KServe, vLLM, llm-d, Envoy AI Gateway, and LiteLLM
Self-hosting an LLM on Kubernetes is easy to demonstrate. Operating a fleet of models under real traffic is a different problem. A production inference platform must answer several questions at once:
Responses
Markdown supported · ⌘↵ to post
No responses yet.