Senior engineer. How AI and software work — and where they quietly break.
I'm a senior software engineer. I write Simply Explained, a plain-English breakdown of how AI and software actually work, and the quiet ways they break: AI fixes that hide bugs, agents that pick the wrong tool, health checks that take down healthy servers. One symptom, one analogy, one fix per piece. New here? Start with the pinned Start Here guide, or get one breakdown a week by email.
Markdown supported · ⌘↵ to post
AI Developer
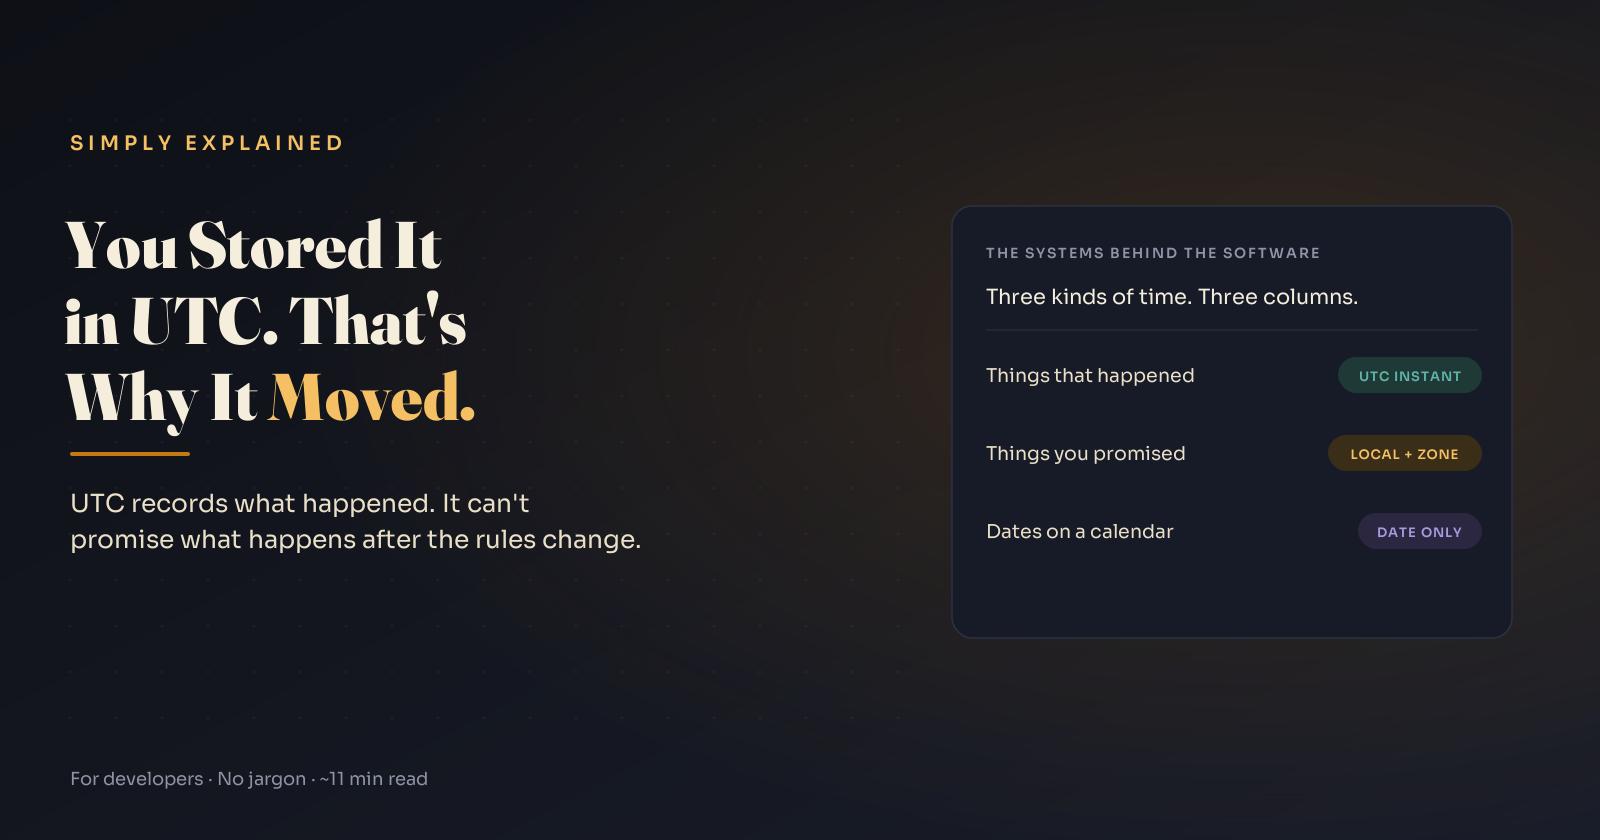
The 'store the question, cache the answer' framing is the clearest way I've seen to put this. One thing I'd add is a detail about recurrence: for repeating events, the series rule (local time, zone, RRULE) is the source of truth and each occurrence's UTC is derived, so a tzdata refresh job should regenerate only future occurrences and never touch ones already in the past. Also, nonexistent or ambiguous local times (the spring-forward gap, the fall-back repeat) probably deserve an explicit policy stored per event rather than a global default. How would you decide when the refresh job runs, on each tzdata release or lazily on read?