Two From-Scratch Systems, and the Day They Talked
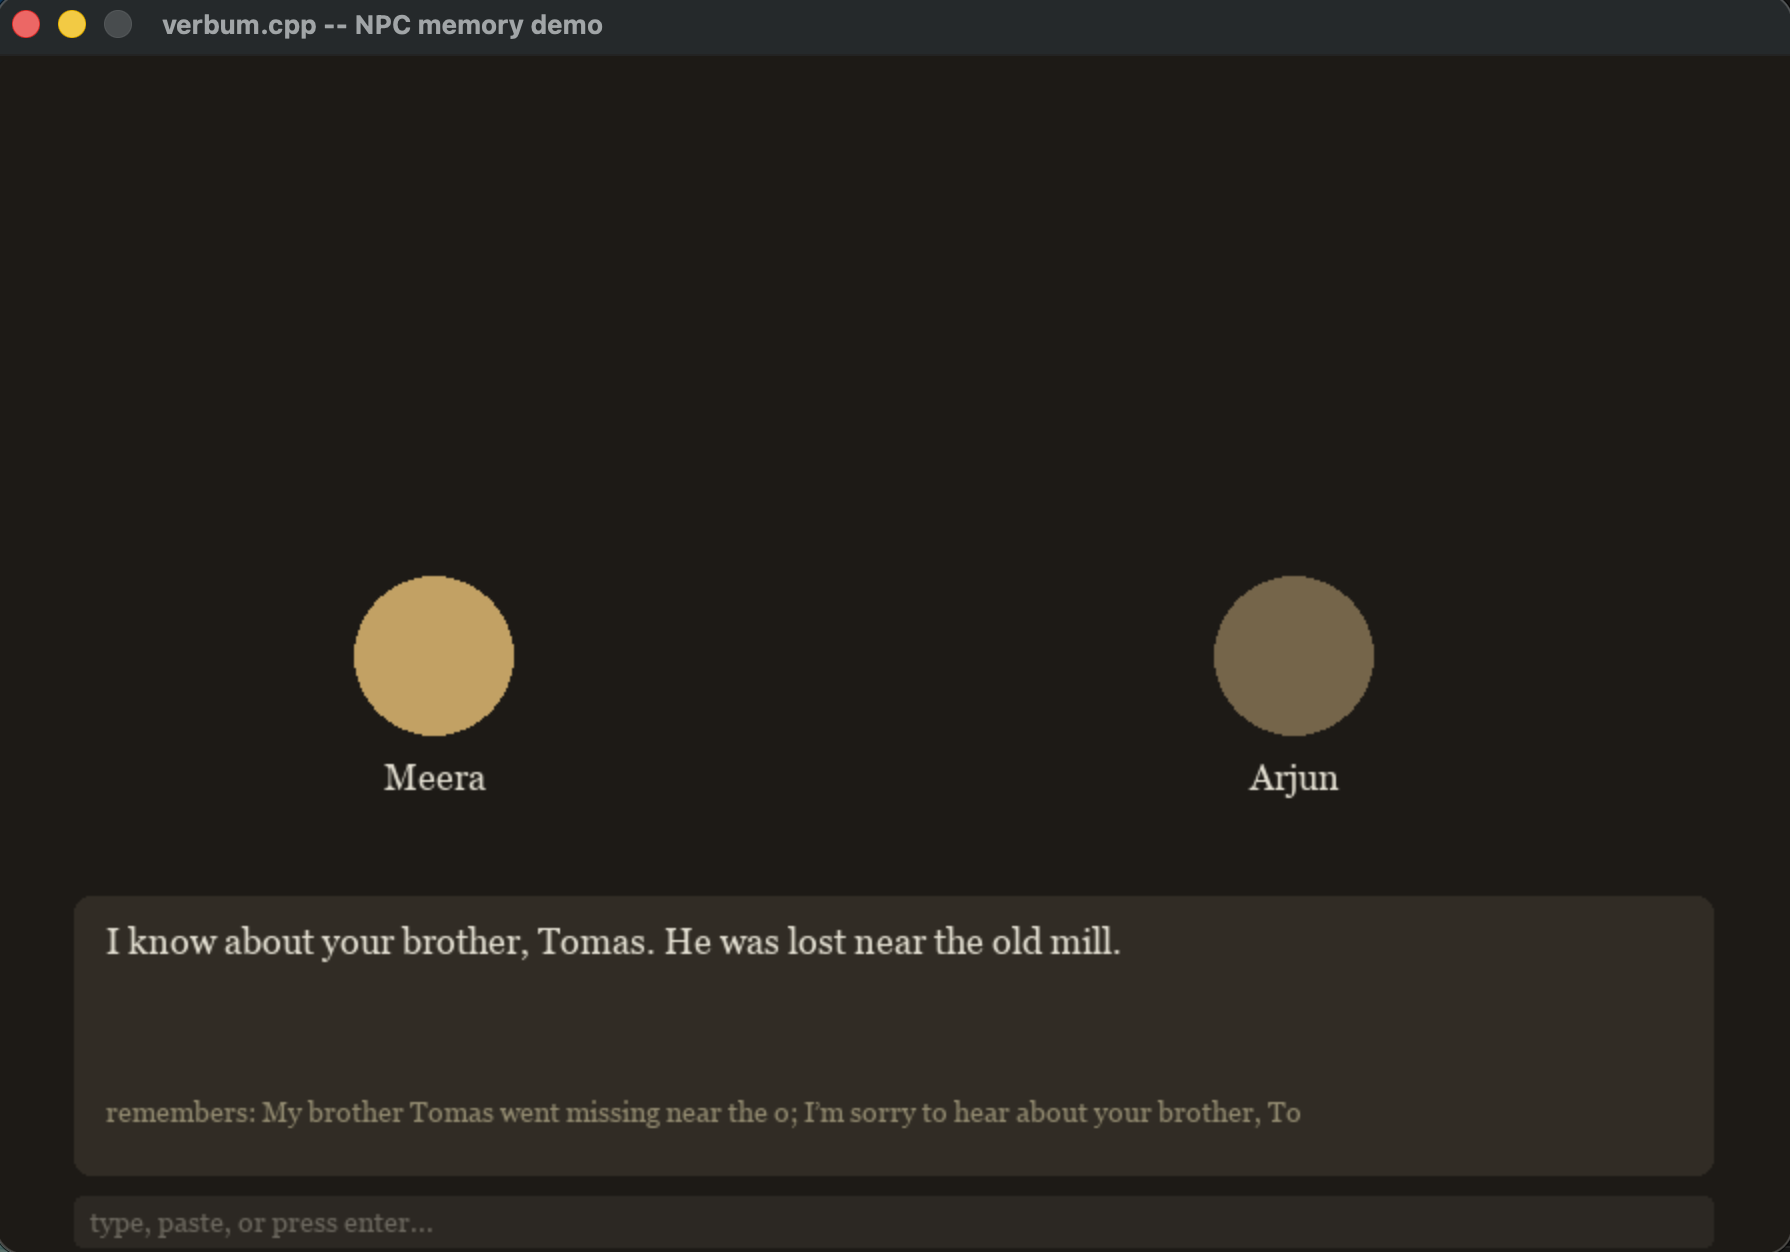
I built a vector database and an LLM inference engine, each without leaning on someone else's runtime. This is the demo where they finally talked to each other — and the two real bugs that showed up doing it.
Written by
C++/CUDA Engineer · LLM Inference & Systems
C++/CUDA engineer building LLM inference and GPU code from scratch: verbum.cpp, Lattice, RAAG. 2 CUDA PRs merged into llama.cpp. I write about inference, GPU performance, and measuring things honestly.
Responses
Markdown supported · ⌘↵ to post
No responses yet.