Feed
Discussion
What Actually Happens Inside a Transformer Forward Pass
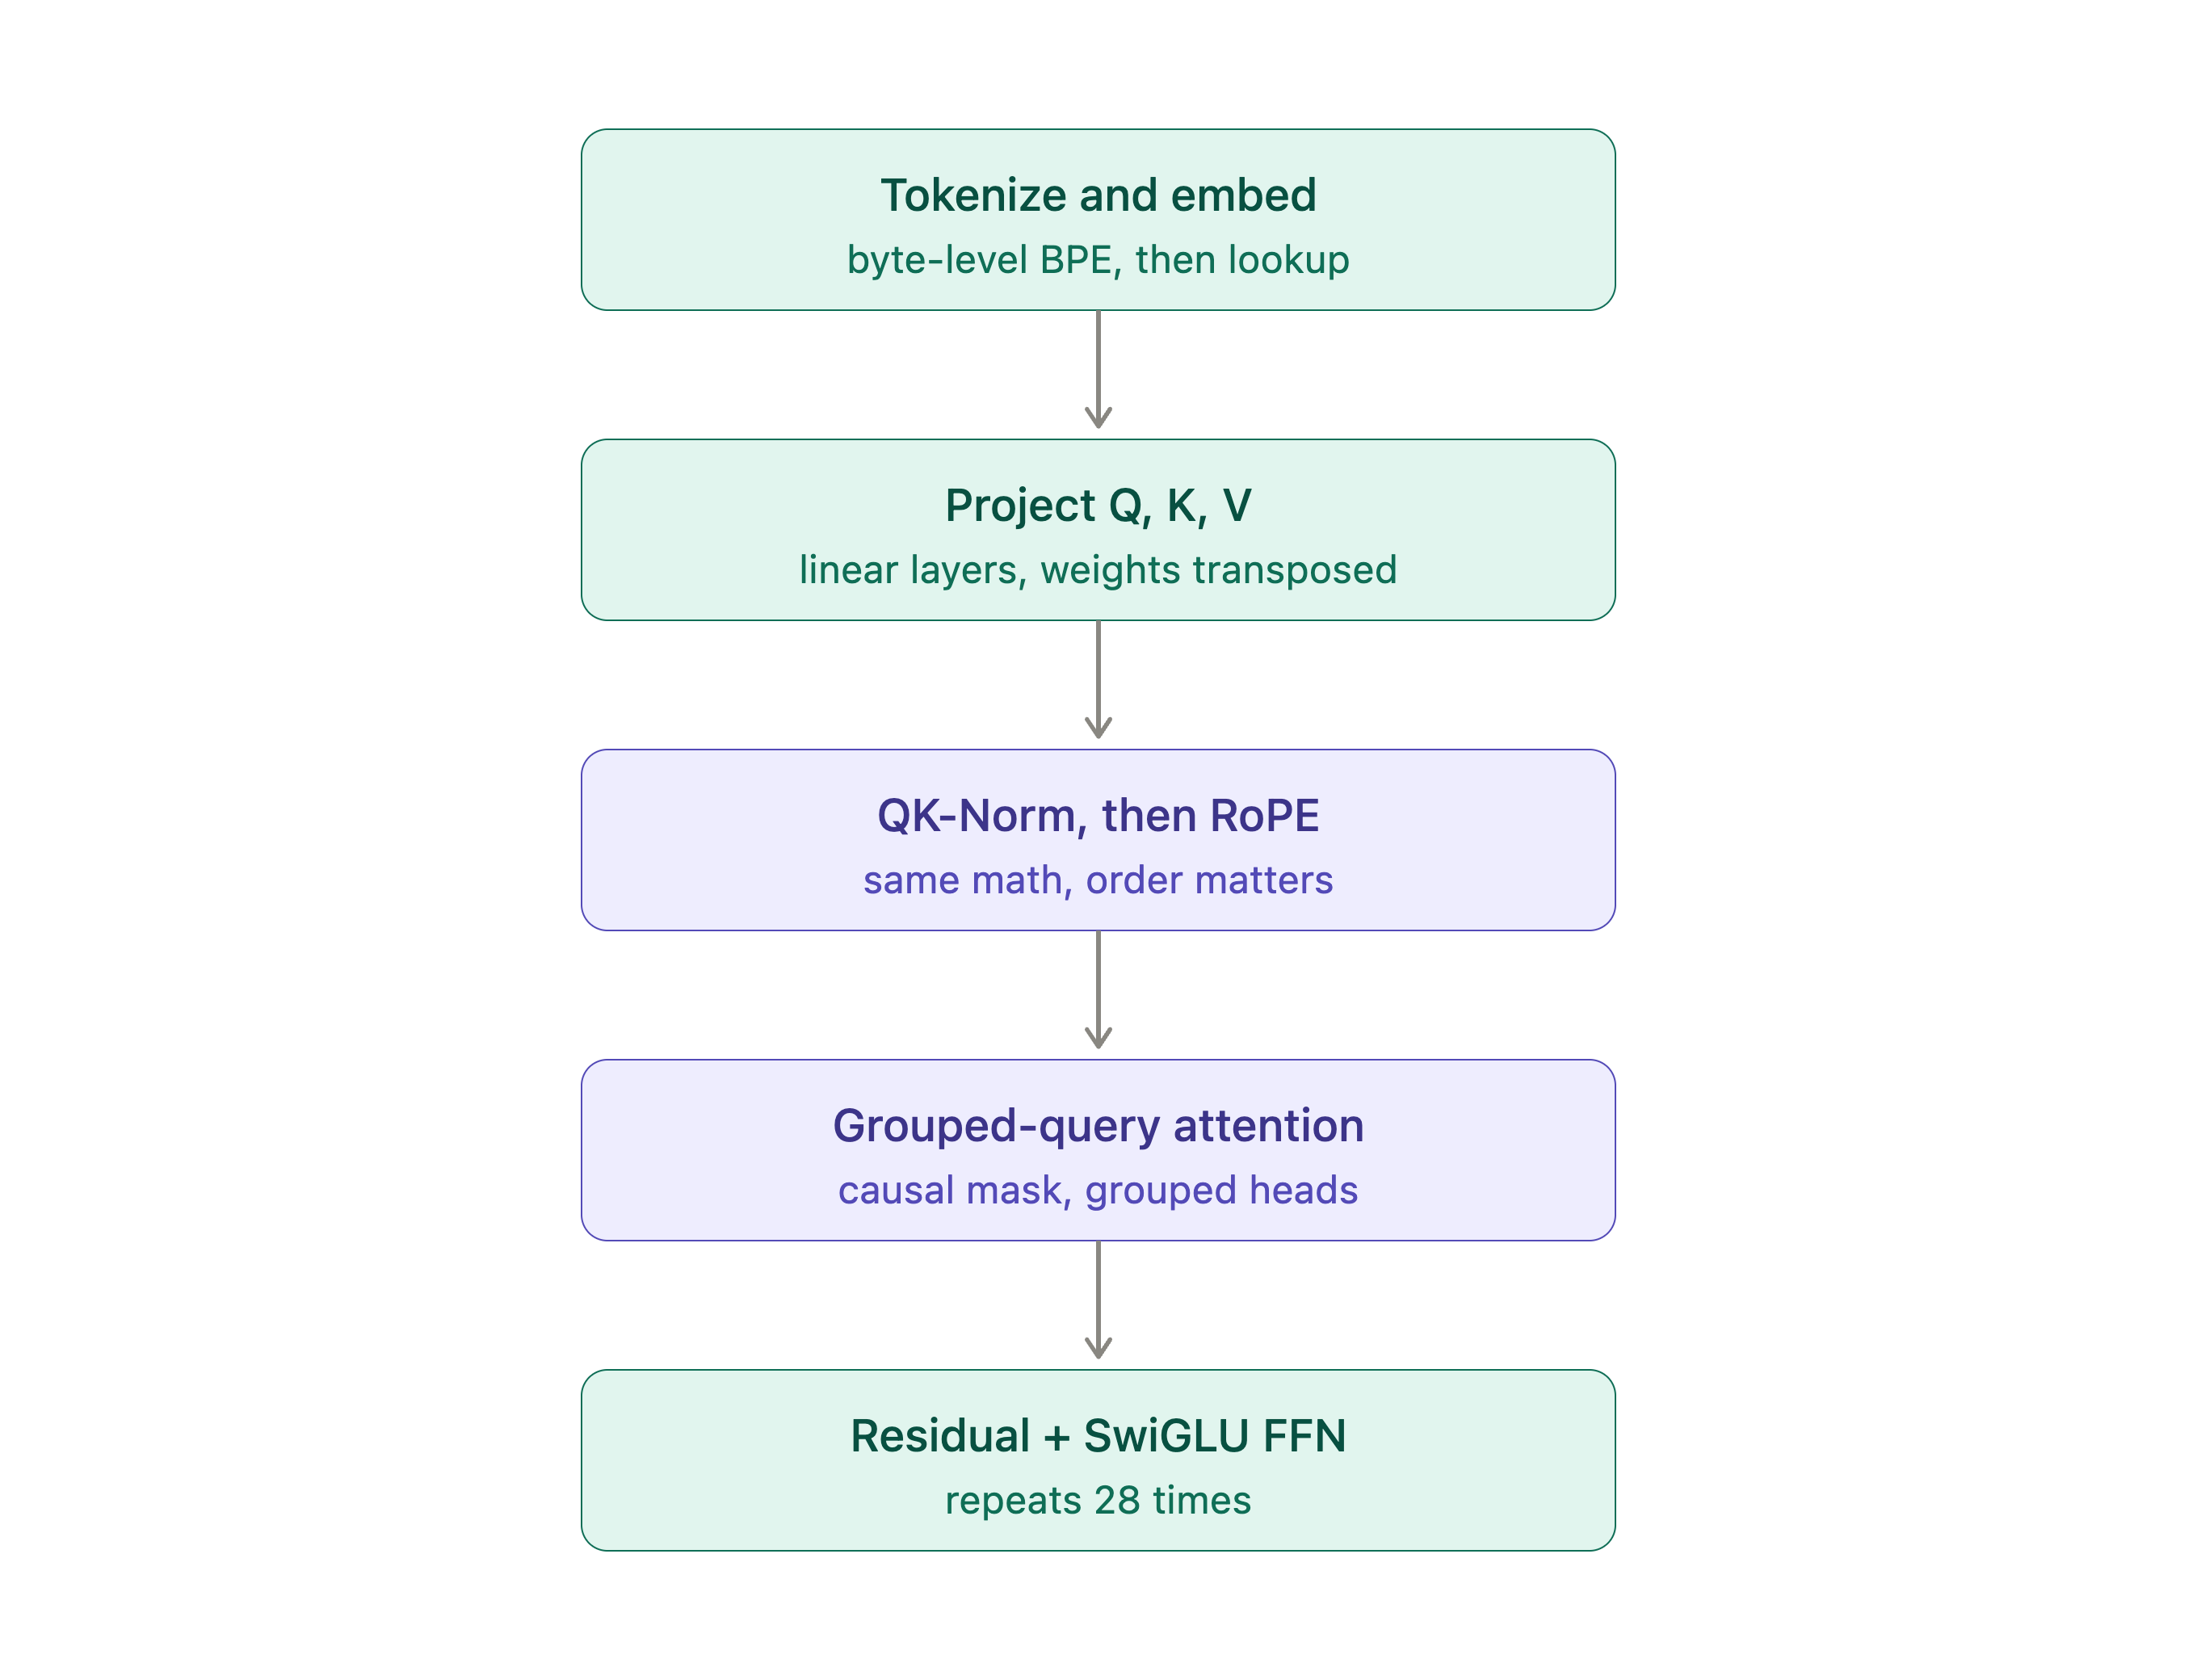
A few months back I got a CUDA kernel merged into llama.cpp — a 1-D pooling kernel, average and max mode, verified against the CPU reference across 216 test cases. That taught me something specific: I
Responses
Markdown supported · ⌘↵ to post
No responses yet.