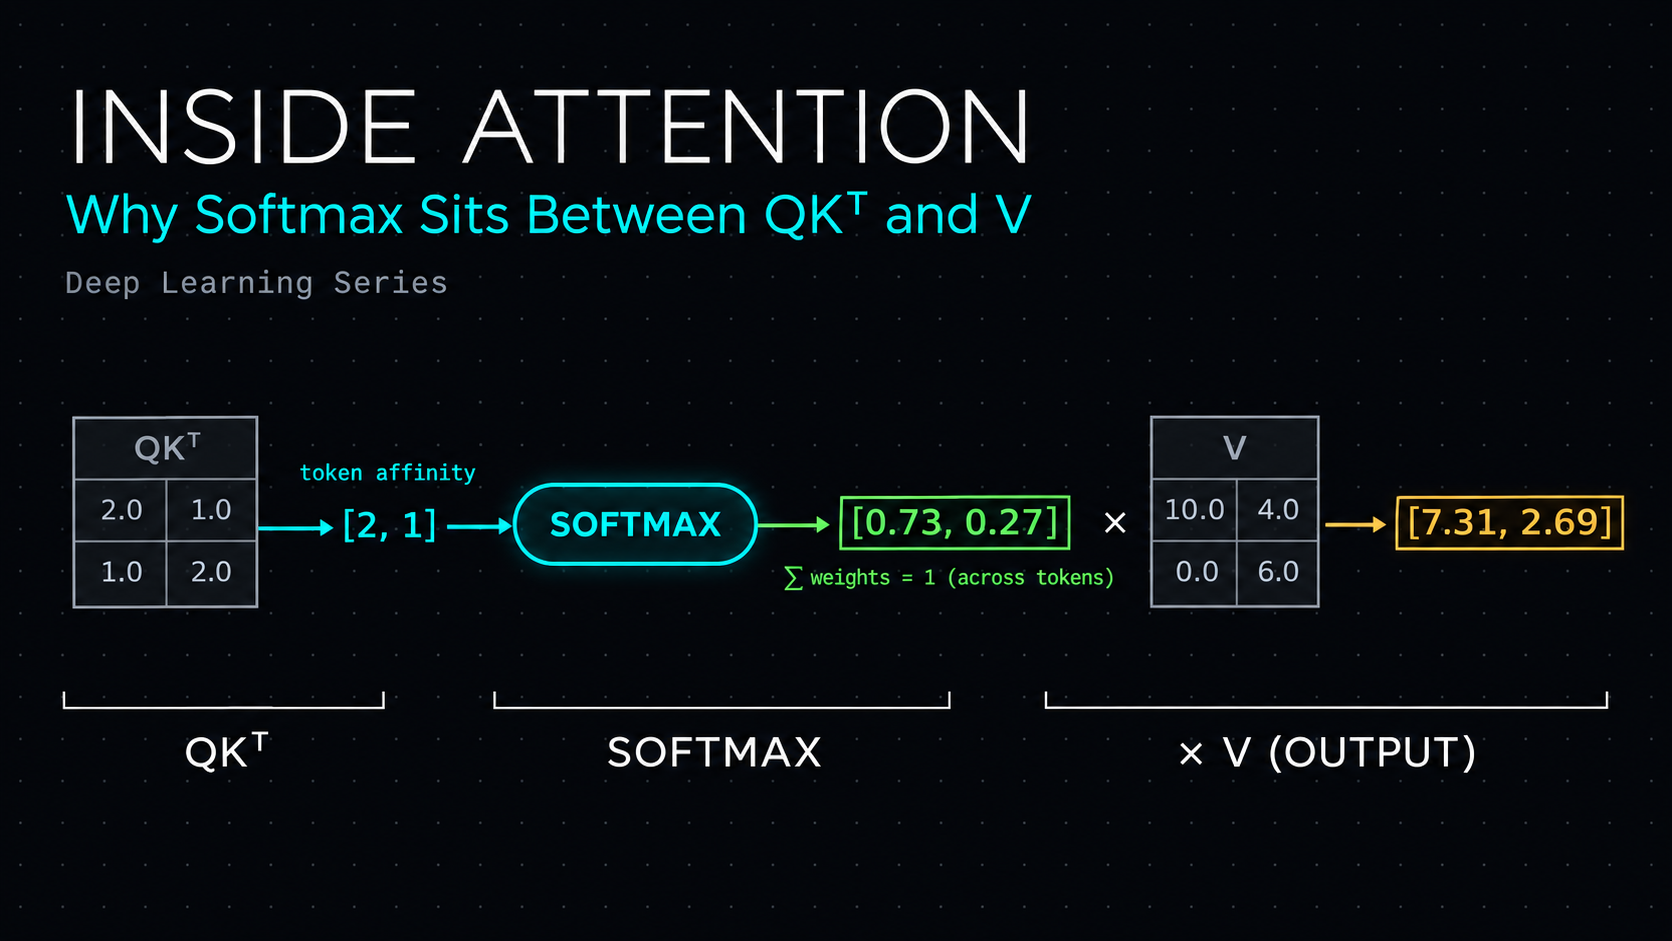
Inside Attention: Why Softmax Sits Between QKᵀ and V
When I first learned self-attention, the formula looked straightforward: $$\operatorname{Attention}(Q,K,V)=\operatorname{softmax}\left(\frac{QK^\top}{\sqrt{d_k}}+M\right)V$$ But one question bothered
Written by
Learning Data Science
Learning Data Science and Sharing the journey through Hashnode.
Responses
Markdown supported · ⌘↵ to post
No responses yet.