Feed
Discussion
Blockwise FP8 on Ada GPUs: why your L4 falls back to Marlin, measured
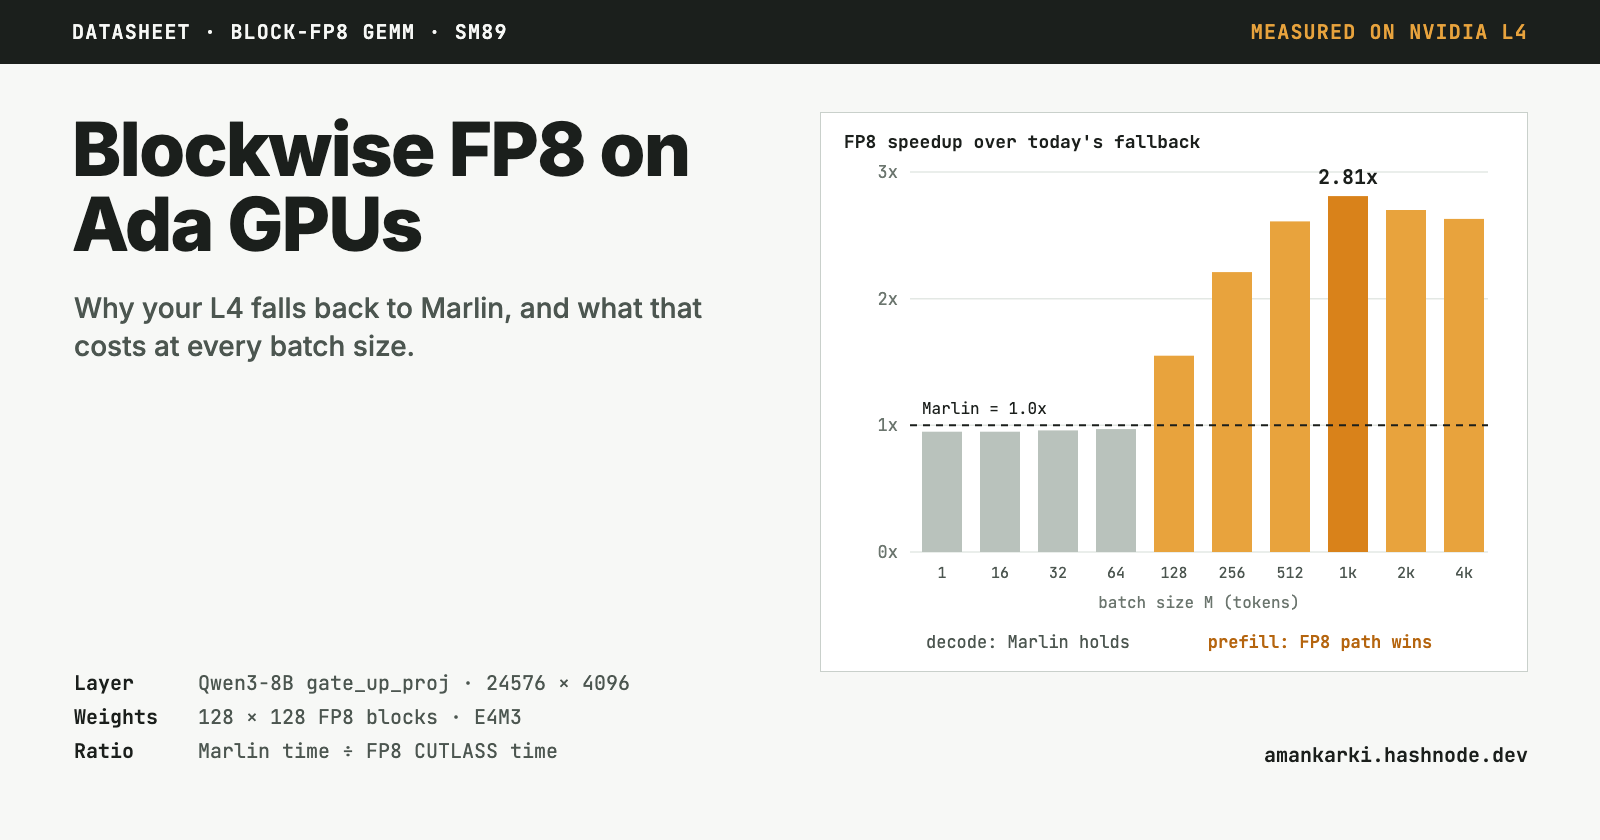
If you serve a block-quantized FP8 model with vLLM on an L4, an L40S or an RTX 4090, it runs. It just doesn't run the way you'd expect. Those GPUs have FP8 tensor cores, but for this kind of checkpoin
Responses
Markdown supported · ⌘↵ to post
No responses yet.