Feed
Discussion
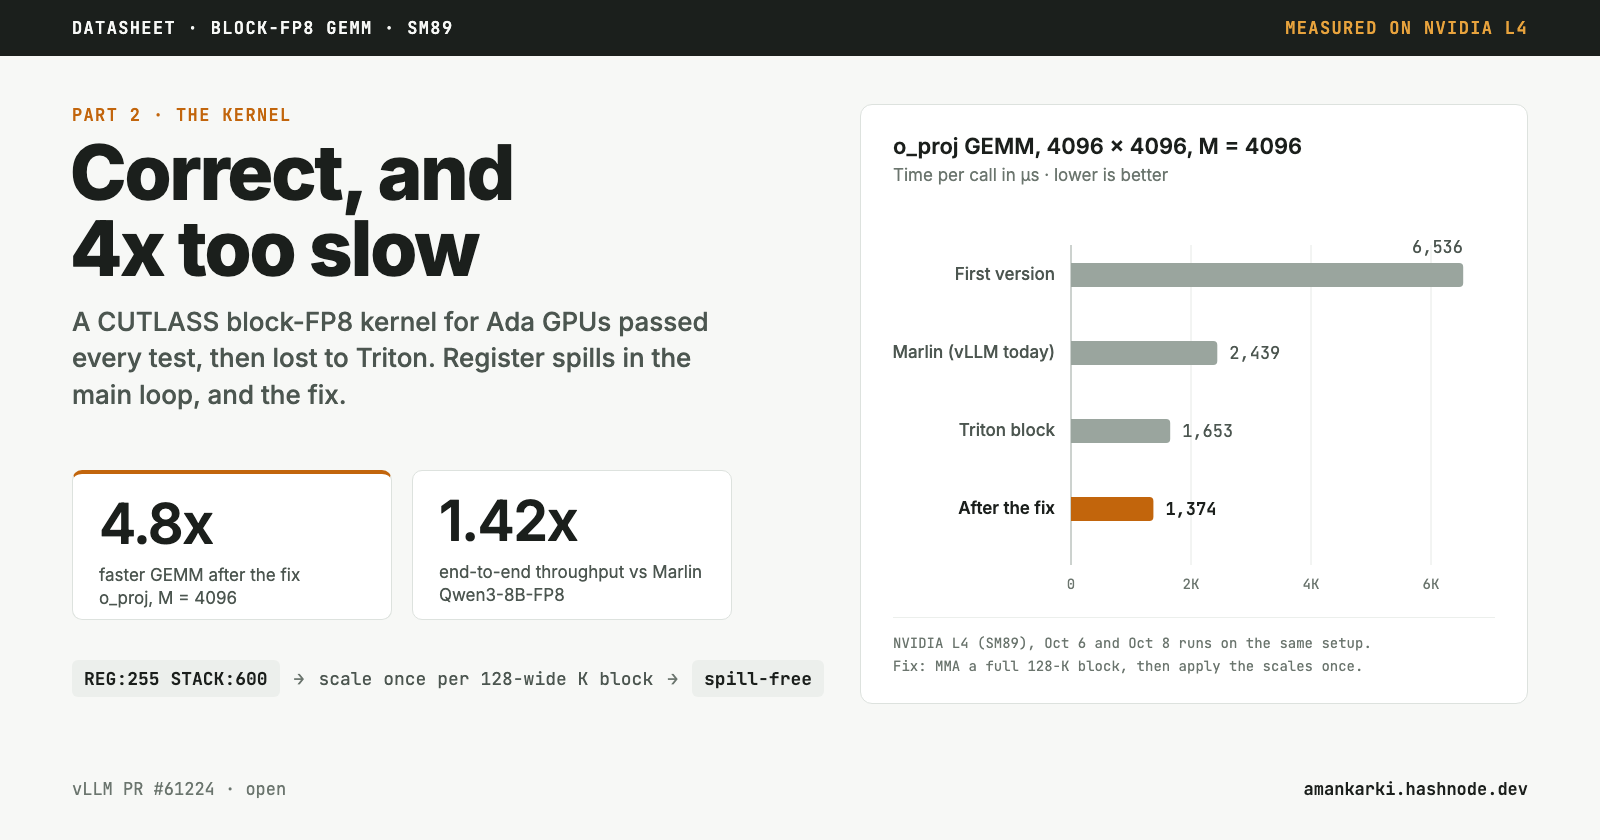
Blockwise FP8 on Ada GPUs, part 2: my kernel was correct and 4x too slow
In my last post I showed that block-quantized FP8 models on Ada GPUs (L4, L40S, RTX 4090) don't use the FP8 tensor cores in vLLM. vLLM falls back to Marlin, which does its math in 16-bit. I ended that
Responses
Markdown supported · ⌘↵ to post
No responses yet.