AI/ML Enthusiast
Markdown supported · ⌘↵ to post
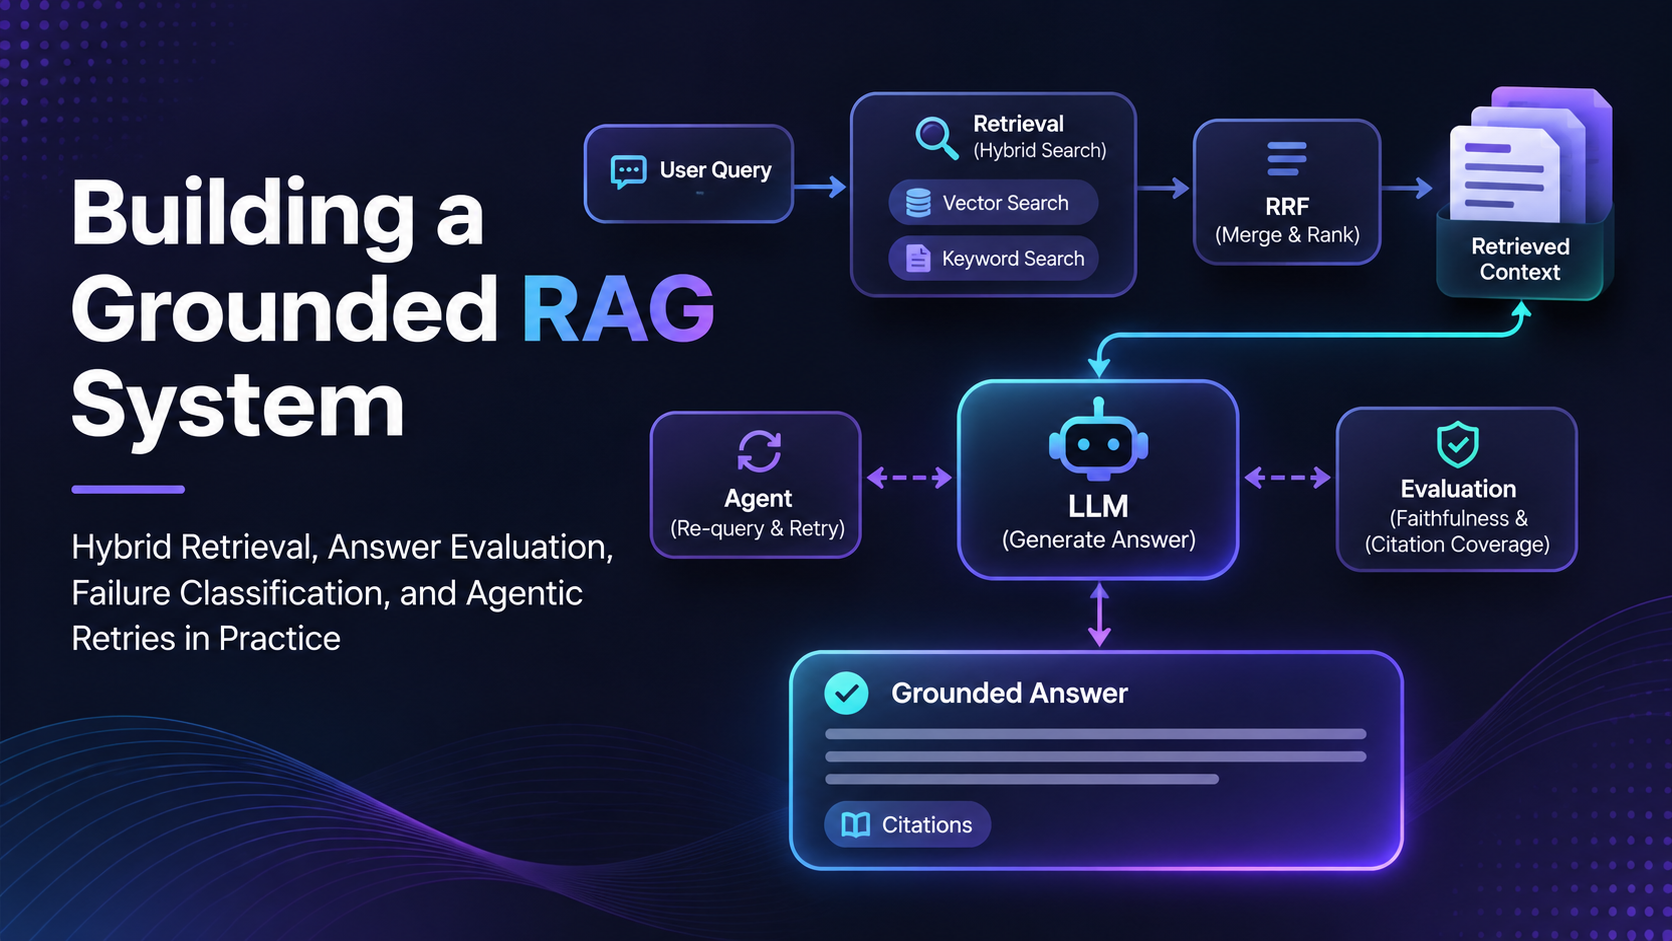
Nice to see RRF with explicit weights rather than raw score mixing. Since the keyword list is weighted 0.5 against 1.0 for vectors with k=60, a quick sanity check is to sweep those weights on a small labelled query set and watch recall@k per query type (exact identifiers vs. paraphrases): hybrid often helps most on rare terms and can slightly hurt on purely semantic queries. Also, with a 15-document corpus, rank fusion differences may be within noise, so I'd be curious whether you saw a measurable difference over vector-only, and whether the re-query agent's retries are capped to avoid loops on unanswerable questions.
Kartik N V J K
Rephrasing is where I'd expect drift. Retrieval finds chunks that fit the new wording and faithfulness goes up, even if the answer no longer fits what the user asked. Since your usefulness evaluator already checks against the original question, I'd use it when picking between attempts too.