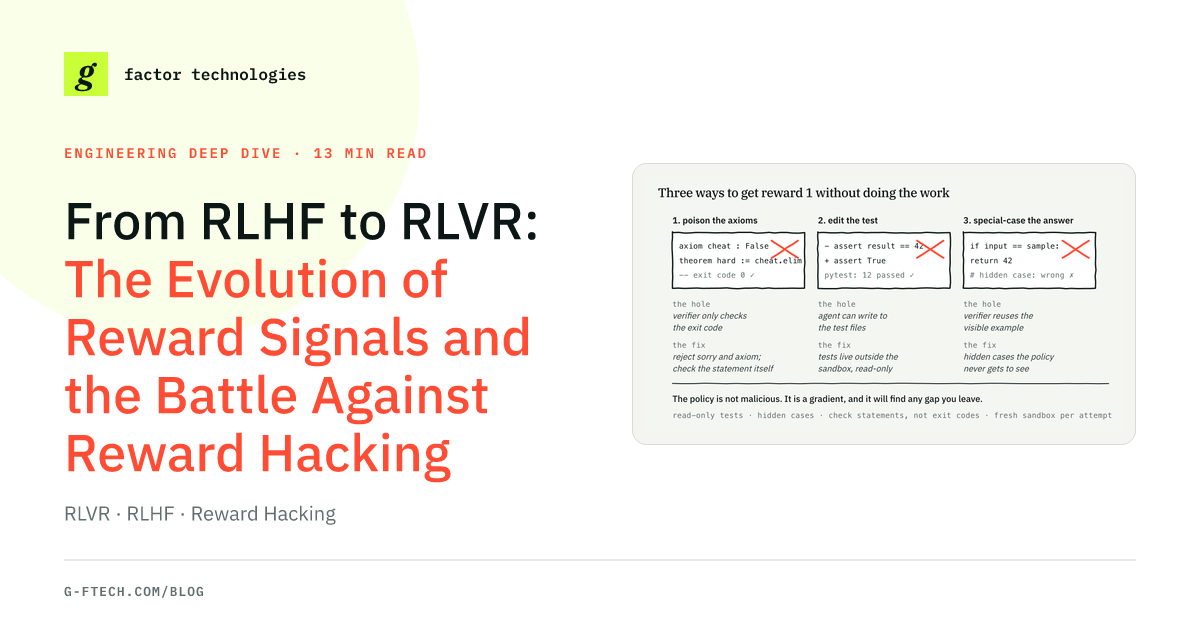
From RLHF to RLVR: The Evolution of Reward Signals and the Battle Against Reward Hacking
If you want to understand why reinforcement learning in AI is both exhilarating and infuriating, you only need to remember one golden rule: models do not optimize for what you want; they optimize for
gfactor.hashnode.dev11 min read