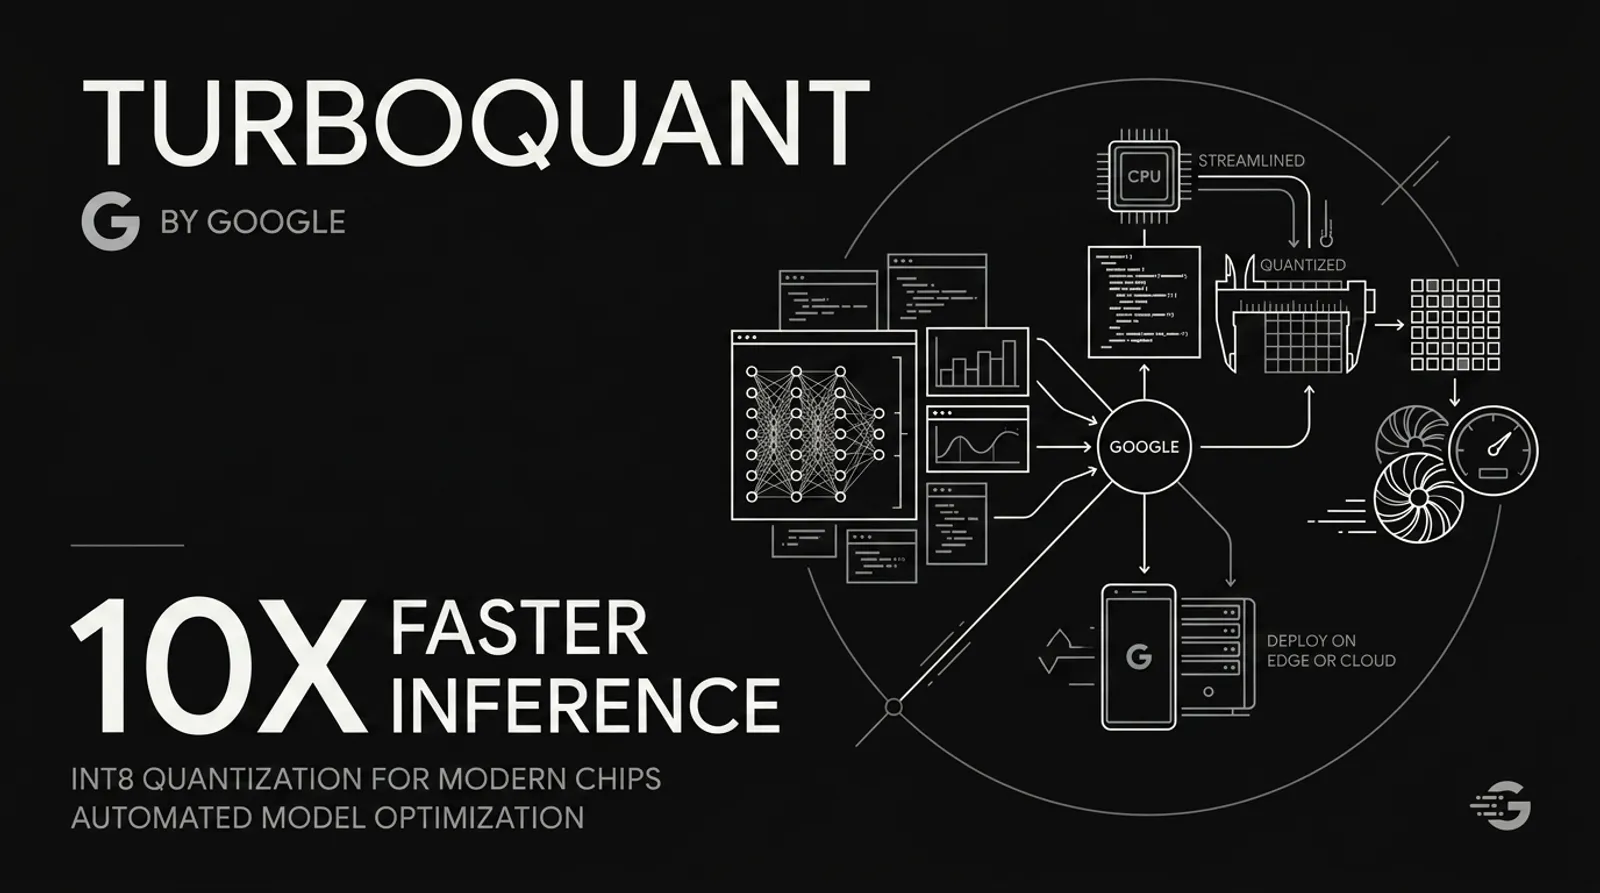
What Google's TurboQuant Does and Why It Actually Matters
Google's TurboQuant: What It Is and Why It Actually Matters The numbers are absurd. For one user running a single Llama-3.1-8B model at 128,000 tokens of context, the KV cache alone chews up 16 gigabytes of VRAM. On a GPU that might have 24GB total. ...
Responses
Markdown supported · ⌘↵ to post
No responses yet.