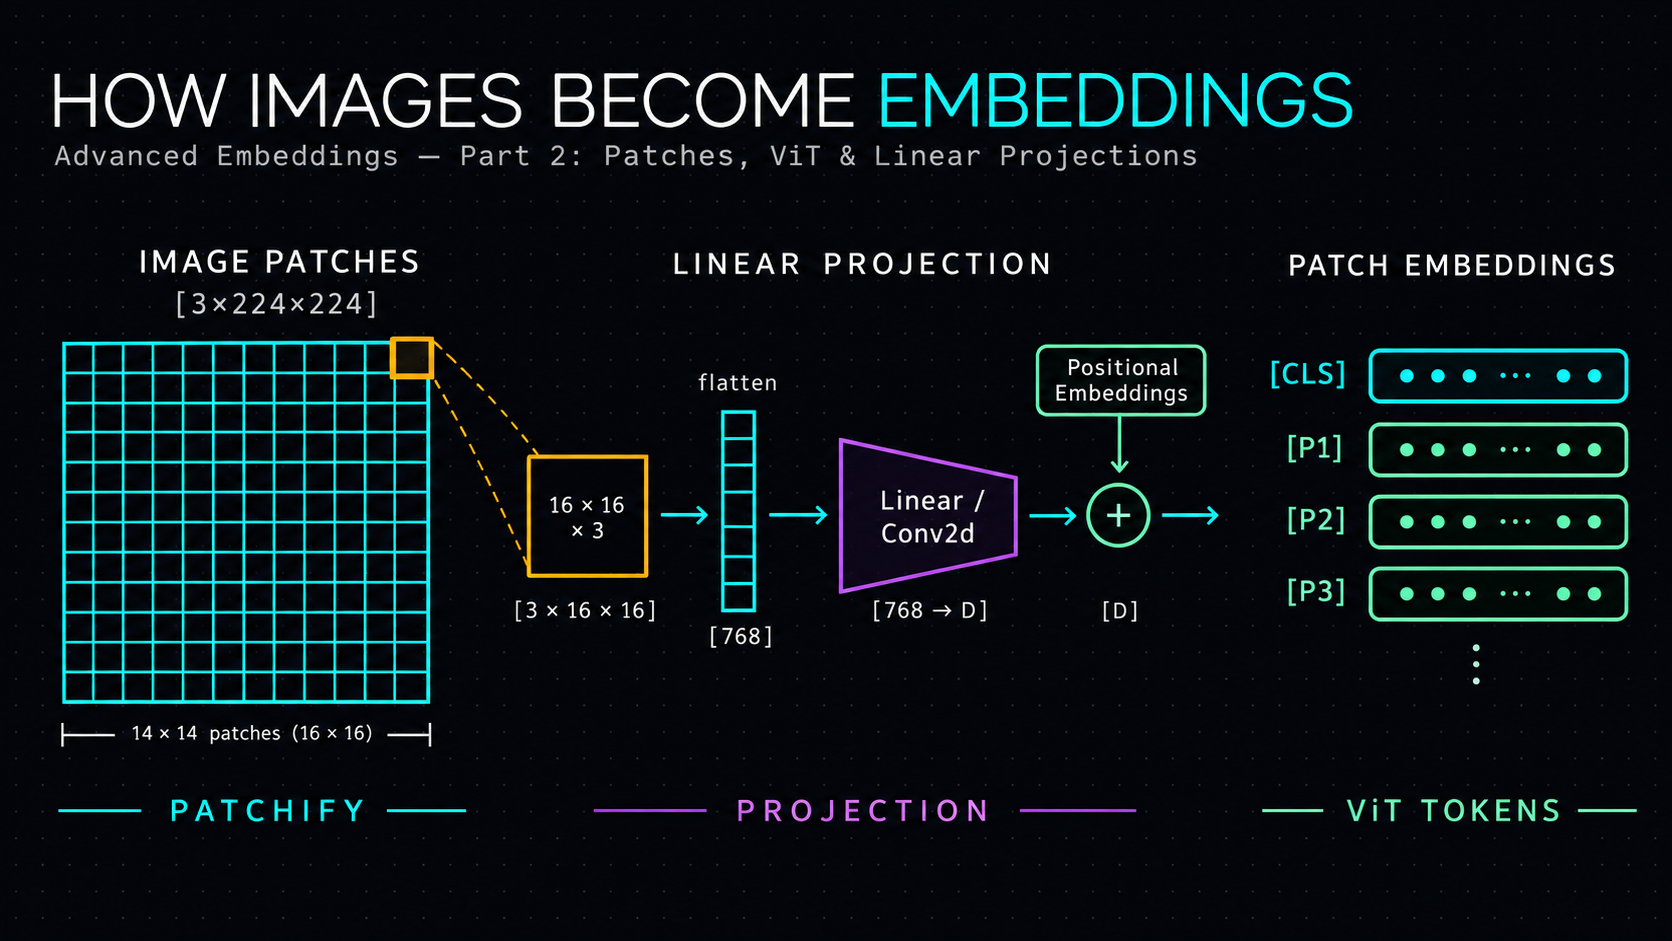
Advanced Embeddings from Scratch — Part 2: How Do Images Become Embeddings?
In Module 1, we learned that multimodal models can represent text and images in a shared embedding space. We also learned how contrastive learning encourages matching text-image pairs to have compatib
Written by
Learning Data Science
Learning Data Science and Sharing the journey through Hashnode.
Responses
Markdown supported · ⌘↵ to post
No responses yet.