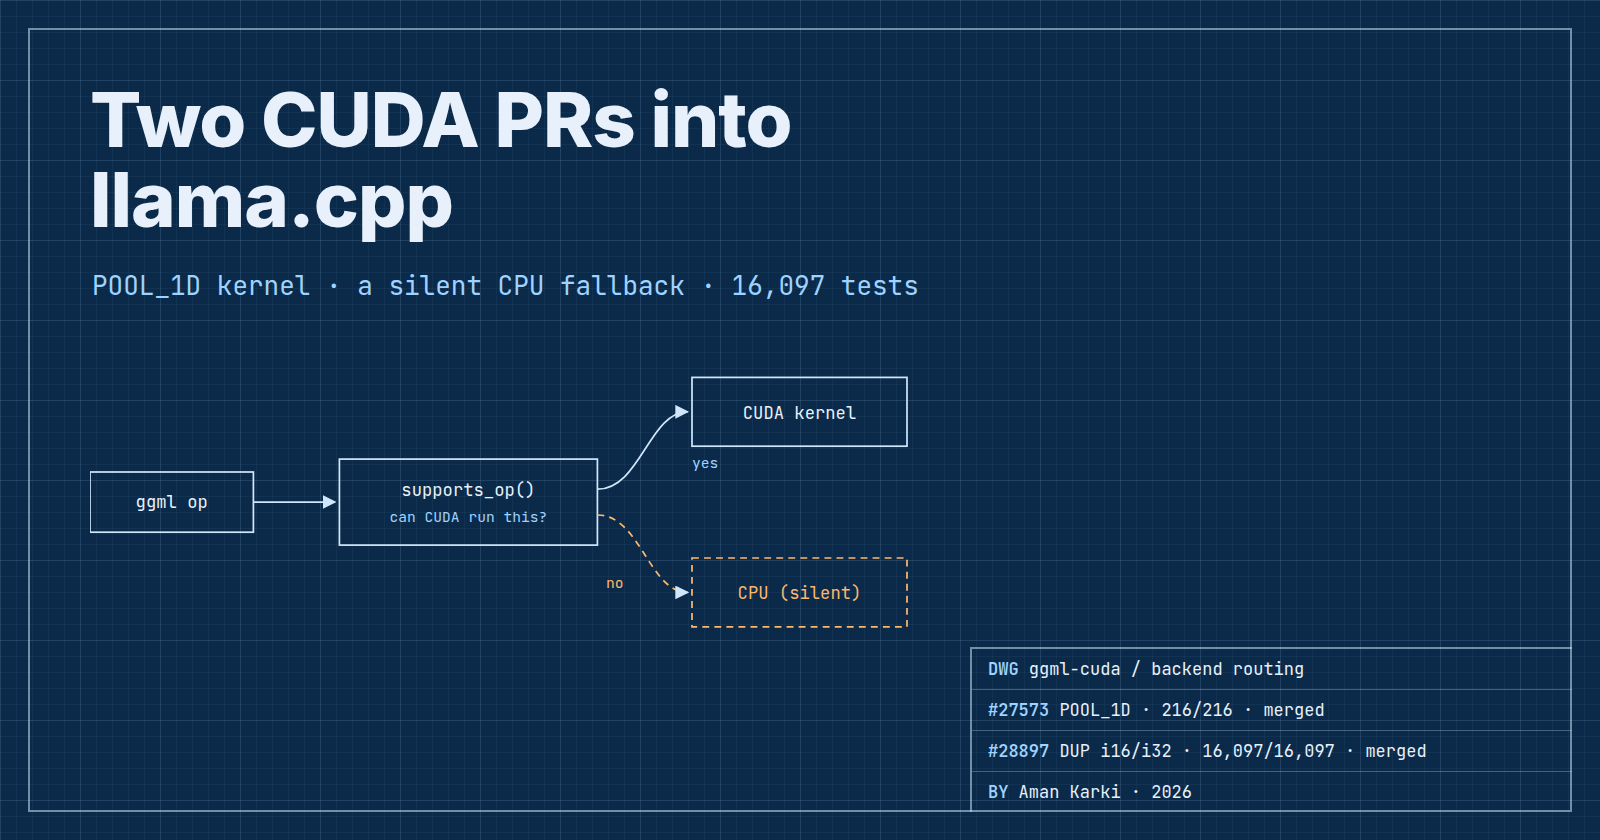
Two CUDA PRs into llama.cpp, and what they taught me about a 100K-star codebase
A 95-line pooling kernel, a 9-line fix for a silent CPU fallback, and how ggml decides where your ops run
Written by
C++/CUDA Engineer · LLM Inference & Systems
C++/CUDA engineer building LLM inference and GPU code from scratch: verbum.cpp, Lattice, RAAG. 2 CUDA PRs merged into llama.cpp. I write about inference, GPU performance, and measuring things honestly.
Responses
Markdown supported · ⌘↵ to post
No responses yet.