From Benchmark Scores to Reliable Personal AI
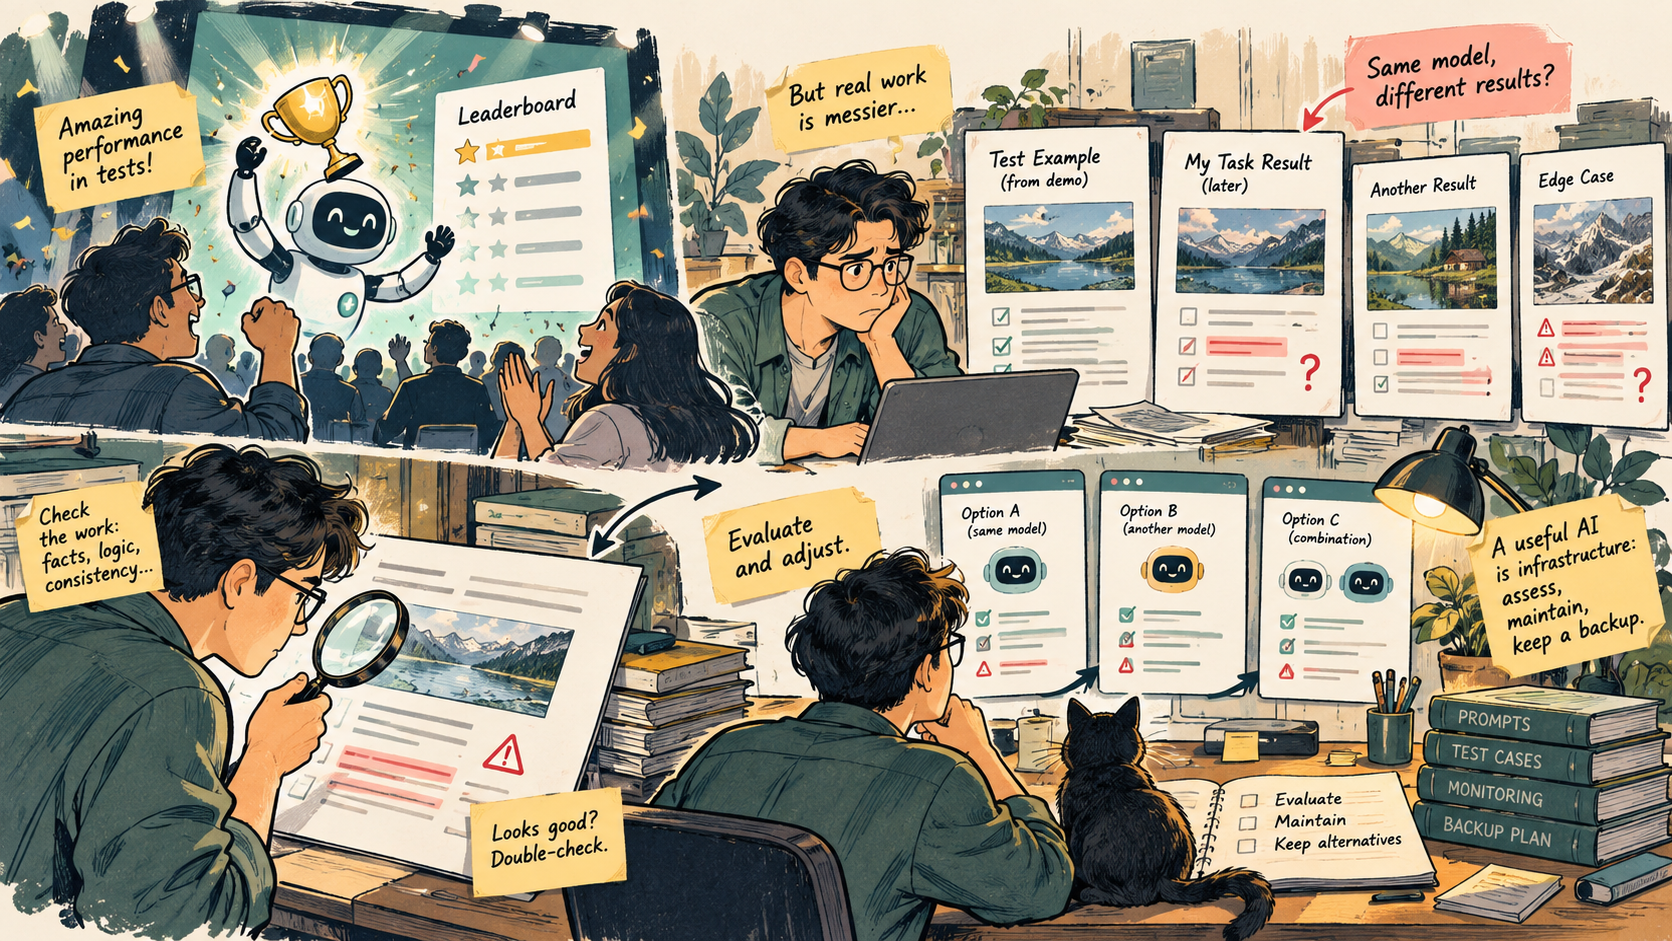
Lately, one question has become harder for me to ignore when using large language models: why does a model that feels impressive at launch not always feel equally reliable after I have used it for a w
Responses
Markdown supported · ⌘↵ to post
No responses yet.