AI Developer Experience | OpenAI SDKs, AI API Integrations & LLM Observability
I build and document AI API integrations, test failure paths, and explore LLM observability and evaluation. I write about what breaks when AI meets real applications, how I investigate it, and what makes integrations easier for developers to use and trust.
Markdown supported · ⌘↵ to post
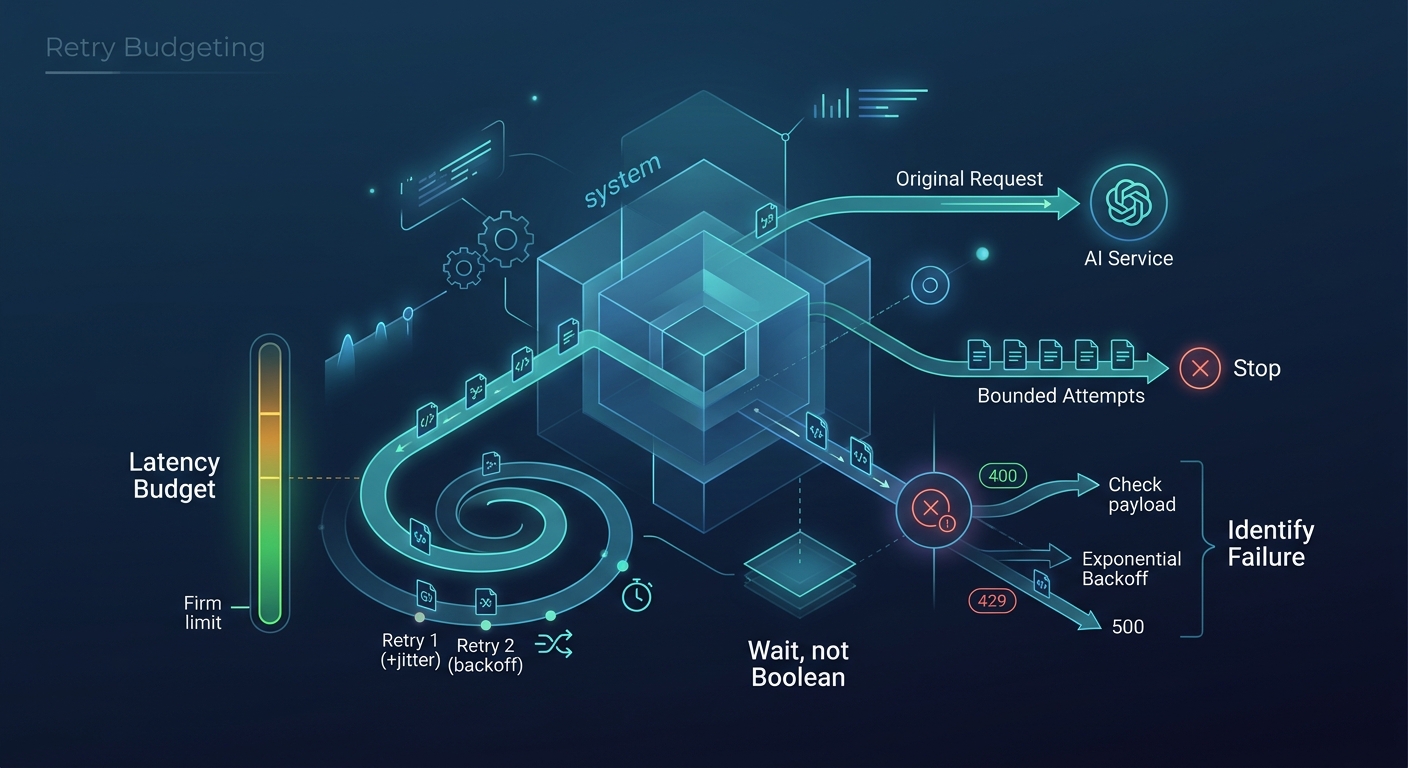
The point about the per-attempt timeout not being the total deadline is easy to miss. With two SDK retries and a 20s timeout you can quietly end up waiting a minute or more. One thing that helped me was passing an AbortSignal.timeout() for the whole operation and also logging the attempt number, so slow requests were obvious in traces. Do you cap the total time separately from maxRetries in your own clients?
The distinction between one attempt and the total wait is useful. Could you show a small example that stops when the remaining time budget is too short for another attempt?
Kartik N V J K
Your nine-attempt math should be plain in the logs. "Number of attempts, where available" gets fuzzy when the SDK retries inside what the job runner sees as one try, so I log the count at each layer separately. Then a slow request tells me which layer spent the time.