Feed
Discussion
We Tested TypeSafe AI's Jev on Screen Classification: 20x Faster, 153x Cheaper, and Noticeably Less Accurate
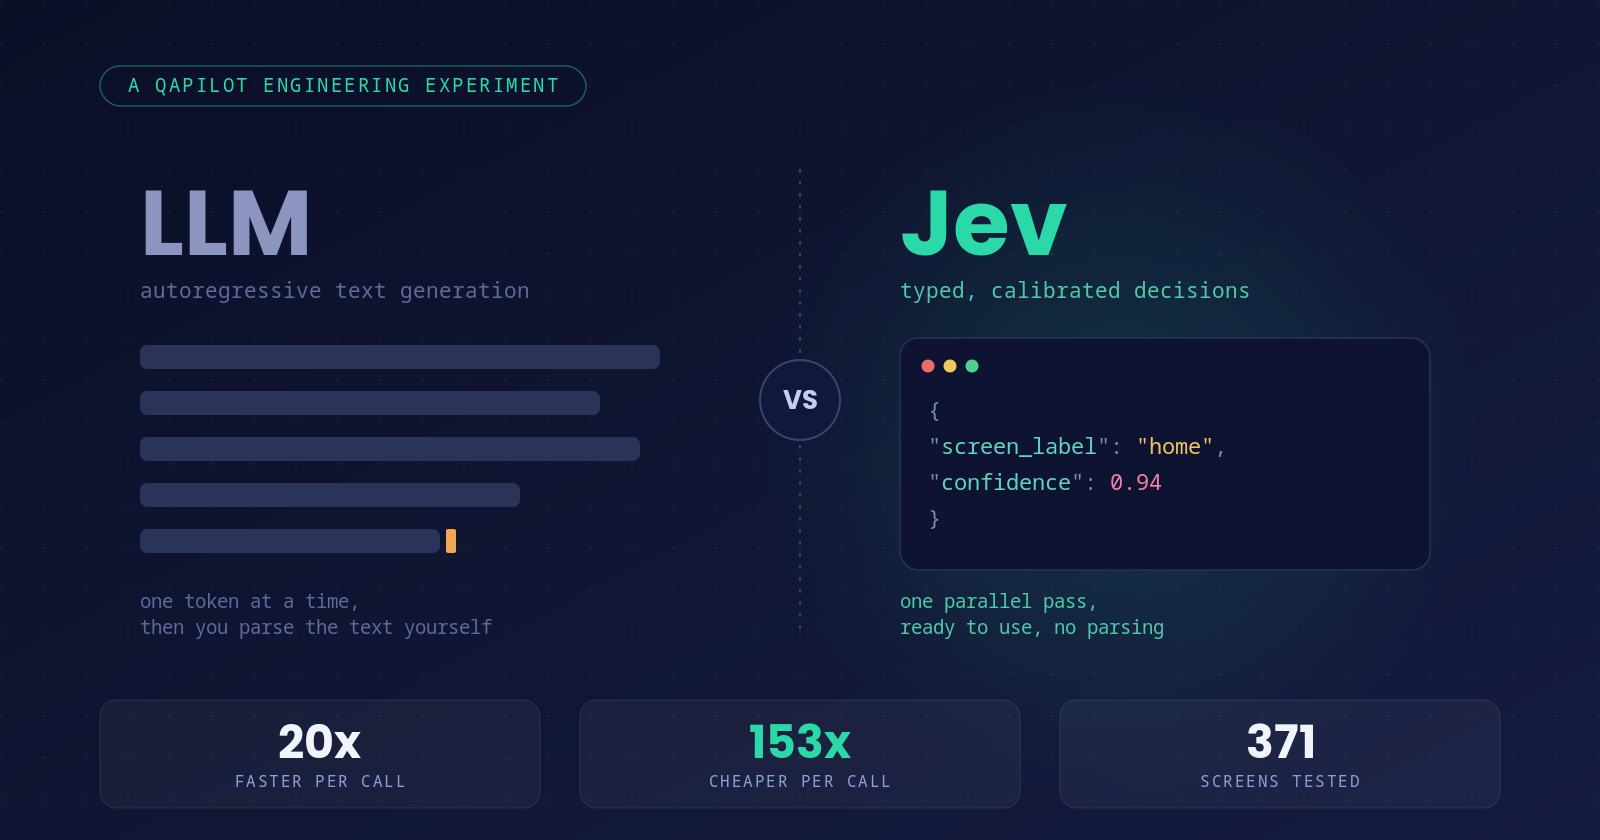
TypeSafe AI's Jev promises a faster, cheaper alternative to LLMs for structured decisions, so we put it to work on a real production task at QApilot: classifying screens for our autonomous mobile app
Responses
Markdown supported · ⌘↵ to post
Brian · AI News
I like AI
Tokenizers that merge rare words into one blob hide typos from every downstream check. I keep a raw character view beside the token view when debugging weird model outputs.