PPratyush Ranjan·5d agoPaged Attention in AI InferenceLearn how paged attention cuts KV cache waste. Build a mini version in PyTorch and benchmark memory use against a contiguous cache.9 min read·ai-inference-pratyush.hashnode.dev1A
AAheadMint·Oct 31Following One Sentence Through a Transformer: A Tensor-Shape WalkthroughWhat actually happens to "Transformers understand context" inside the model, step by step3 min read·aheadmint.hashnode.dev
ZZyVOP·Oct 25I Built the Smallest LLM I Could to Understand How They WorkA hands-on walkthrough of a ~108k-parameter character-level GPT in under 200 lines of PyTorch, with the full code included.12 min read·blog.zyvop.com
NNishanthan Karunakaran·Oct 22How Query, Key, and Value (QKV) Work in TransformersEvery Transformer-based language model, from BERT to GPT, relies on a mechanism called attention to determine how different tokens in a sequence relate to one another. At the heart of this mechanism a7 min read·nishanthan.hashnode.dev
SSai Sandeep Kantareddy·Oct 20Routing AI Requests Without Training Data and Knowing When to Train a ClassifierThe retail examples below are illustrative; they do not report measured production results or disclose an employer's implementation. A team adds three specialist agents to an assistant. Routing looks9 min read·tokenbytoken.hashnode.dev13KAY
NNishanthan Karunakaran·Oct 15Understanding Transformer: The Architecture Behind Modern AIWhat Is a Transformer? A Transformer is a neural network architecture introduced by Google researchers in 2017 in the paper Attention Is All You Need. It uses attention mechanisms to help the model le6 min read·nishanthan.hashnode.dev1
MMahesh Moholkar·Oct 13Building a Modern LLM from Scratch: RMSNorm, RoPE, GQA and SwiGLUWhat changed inside the transformer since 2017, why every open model made the same four changes, and a 250-line model you can train on Shakespeare tonight.43 min read·maheshmoholkar.hashnode.dev
ZZyVOP·Oct 3Build a Small LLM From Scratch: A Tested GPT in PyTorchBuild a compact GPT-style transformer in PyTorch, train it on Tiny Shakespeare, test the critical pieces, and see exactly how an 813K-parameter language model learns.26 min read·blog.zyvop.com
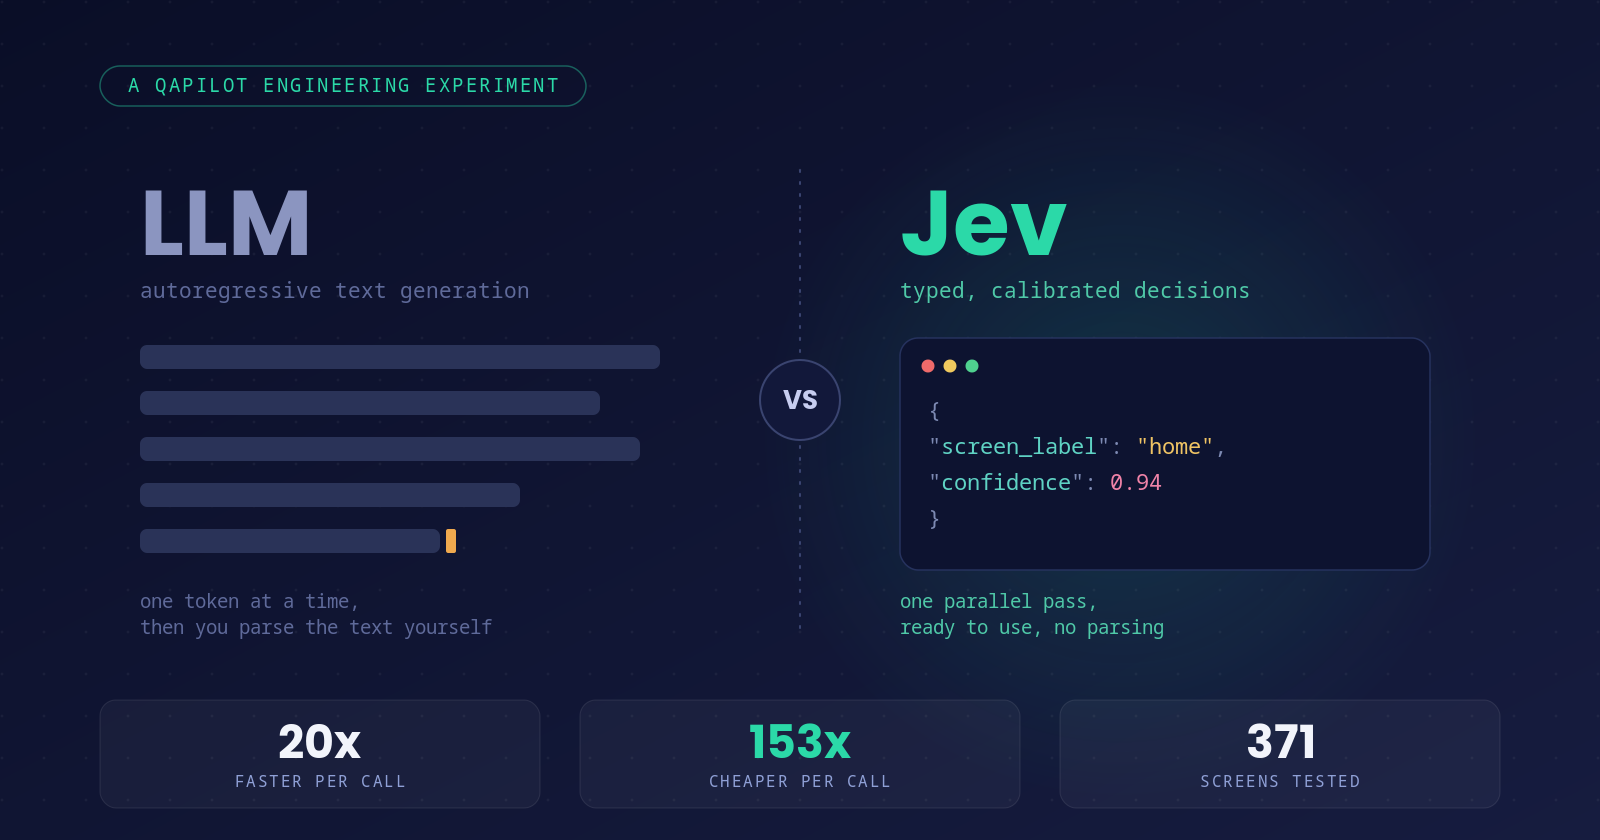
SSurendranath Reddy Jillella·Sep 24We Tested TypeSafe AI's Jev on Screen Classification: 20x Faster, 153x Cheaper, and Noticeably Less AccurateJev promises faster, cheaper alternative to LLMs for structured decisions, so we tested on a task at QApilot: classify screens for mobile app agents.9 min read·qapilot-ai.hashnode.dev12B
EEkansh Nangia·Sep 17Introduction To Mechanistic InterpretabilityHow do LLMs actually work? Explore mechanistic interpretability, AI epistemology, and why probing neural networks cannot crack the AI black box.18 min read·ekanshn.hashnode.dev