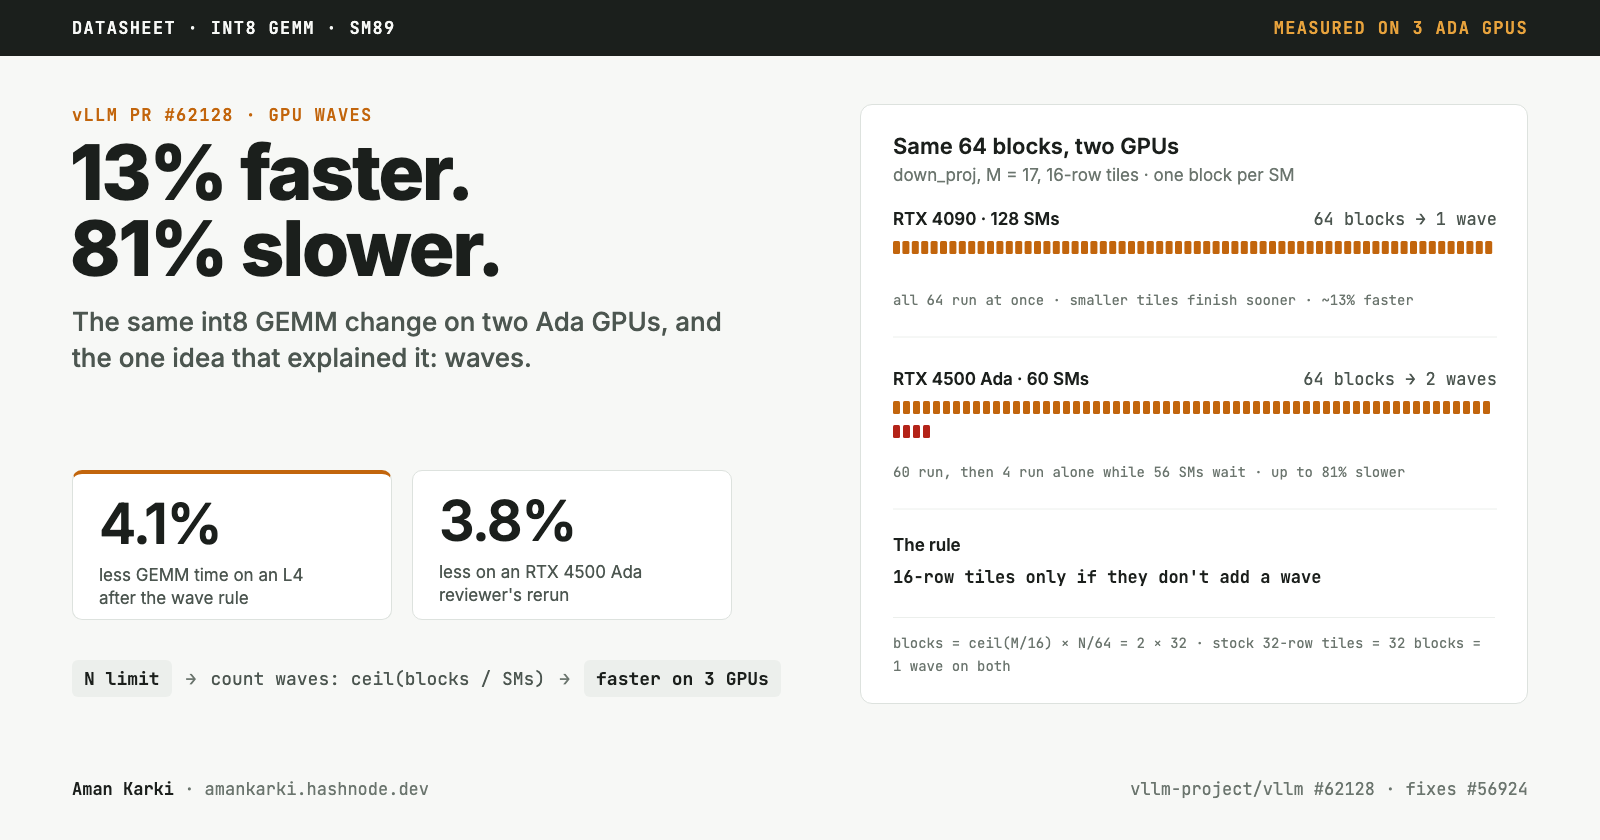
My GPU fix was 13% faster on one card and 81% slower on another
A vLLM int8 GEMM change, a reviewer with a smaller Ada GPU, and the one idea that explained it: waves
Written by
C++/CUDA Engineer · LLM Inference & Systems
C++/CUDA engineer building LLM inference and GPU code from scratch: verbum.cpp, Lattice, RAAG. 2 CUDA PRs merged into llama.cpp. I write about inference, GPU performance, and measuring things honestly.
Responses
Markdown supported · ⌘↵ to post
No responses yet.