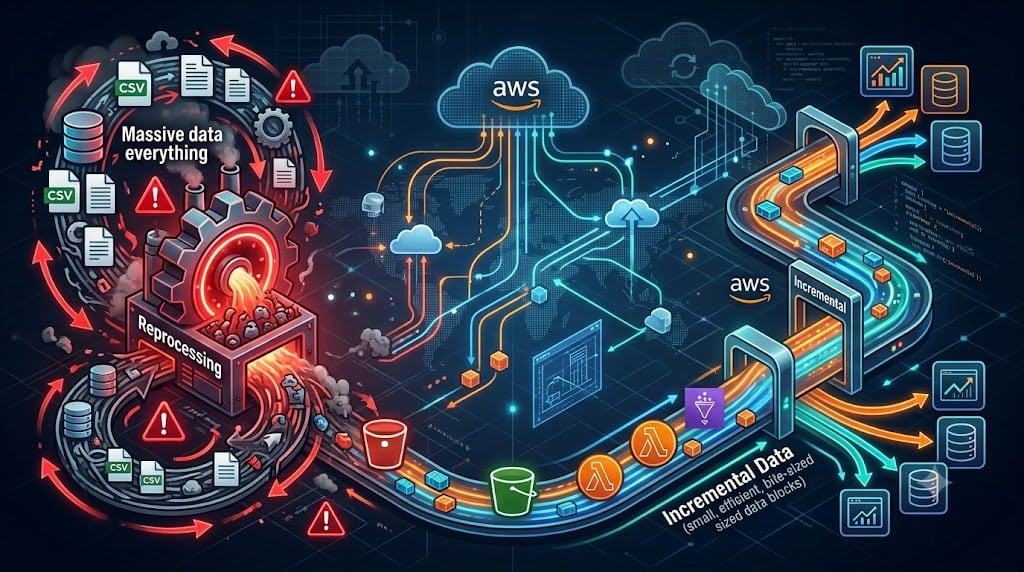
Stop Reprocessing Everything: Build Incremental Data Pipelines on AWS
How to use AWS Glue, Amazon S3, and PySpark to process only new and changed data without making your pipeline fragile.
Imagine you have a data pipeline that processes 100 GB of data every morning.
The
rahul-dataeng.hashnode.dev12 min read