RRahul R·13h agoHow Delta Lake Is Built on Top of Amazon S3: Understanding the Architecture Behind ItUnderstanding How Parquet Files and Transaction Logs Turn an S3 Data Lake into a Reliable Lakehouse.8 min read·rahul-dataeng.hashnode.dev
RRahul R·Oct 16Stop Reprocessing Everything: Build Incremental Data Pipelines on AWSA Practical Guide to AWS Glue, PySpark, and S3 for Processing Only What Has Changed12 min read·rahul-dataeng.hashnode.dev
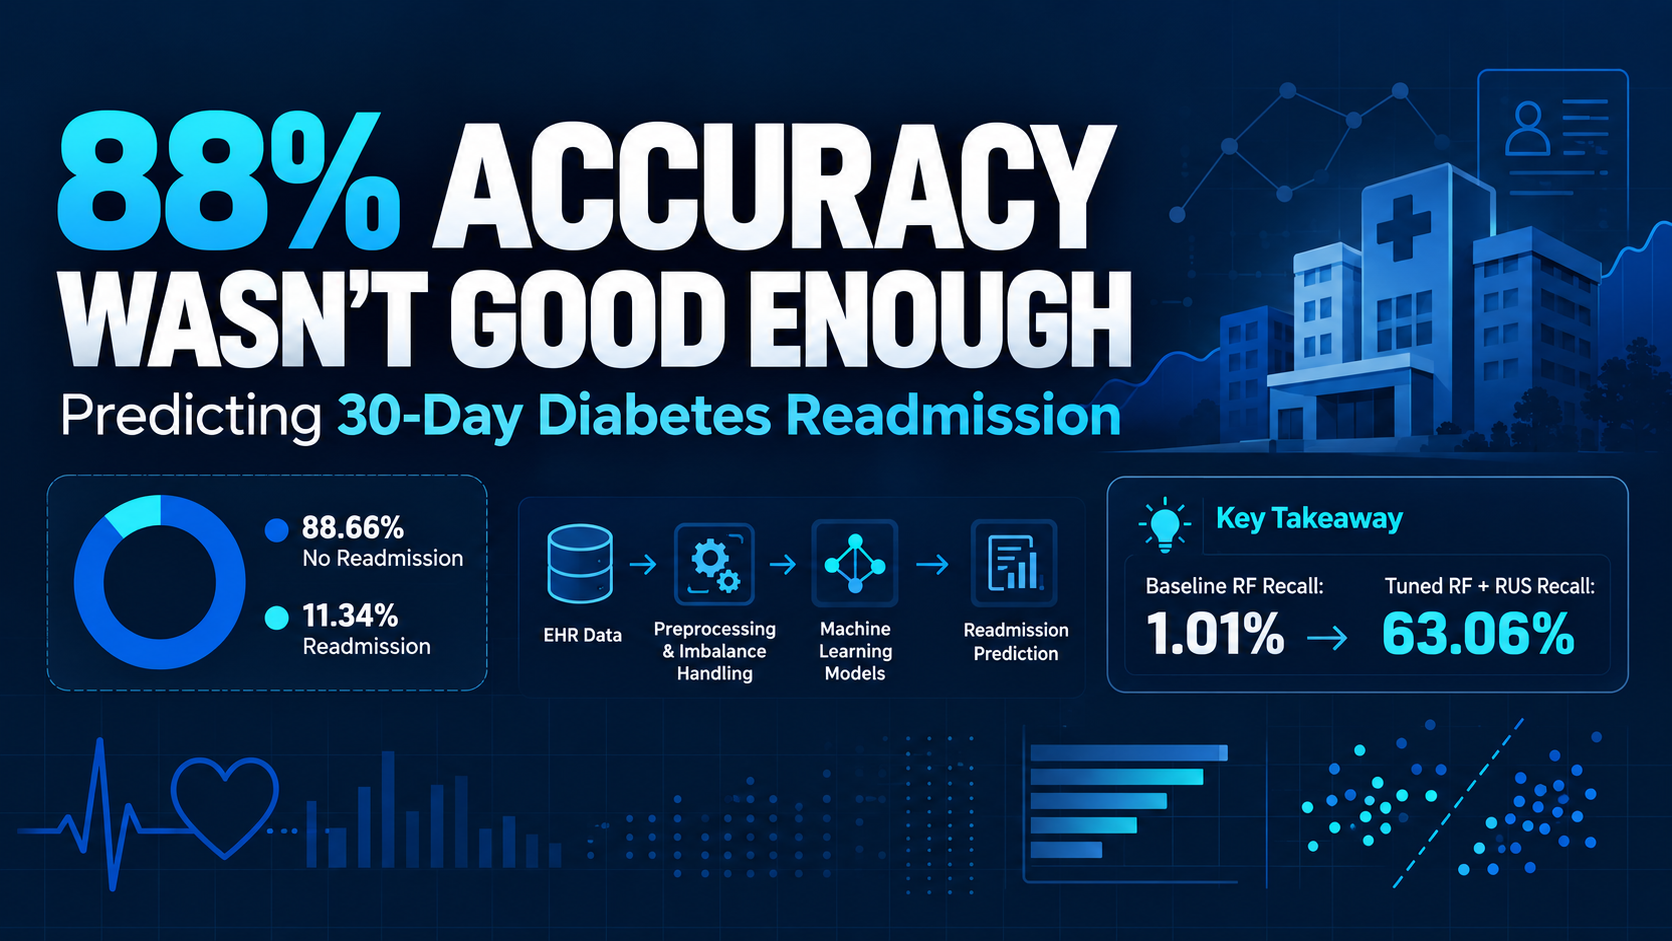
SSayan Khan·Oct 6Why 88% Accuracy Wasn’t Good Enough: Building an End-to-End Machine Learning Pipeline for 30-Day Diabetes Readmission PredictionFrom class imbalance and model tuning to PySpark distributed learning, K-Means subgroup discovery, and global-vs-local classification.21 min read·sayankhan.hashnode.dev14KI
NNalaka Wanniarachchi·Sep 2Machine Learning on Databricks for Data EngineersA data engineer's walkthrough of two end-to-end ML pipelines on Databricks : load, clean, train, save and score using Spark, tables and a little Python.17 min read·bidiaries.com3
KKarthik Darbha·Aug 16Root Cause Analysis Without the War RoomAI-Augmented Data Engineering — Article 4 of 710 min read·tech4nirvana.com1
PPranjal Verma·Aug 12Spark Performance Tuning Interview Prep GuideMaster Spark tuning for interviews: shuffle, partitioning, caching, joins, AQE, memory, Spark UI, and production scenarios for data engineering roles.13 min read·blog.pvcodes.in
KKarthik Darbha·Jun 20AI-Driven Data Quality: From Rules to ReasoningAI-Augmented Data Engineering | Article 2 of 7 | tech4nirvana.com11 min read·tech4nirvana.com
VVishnu D·May 29Spark Architecture Simply ExplainedDriver, executors, stages, tasks -- the full picture9 min read·thedatatrench.hashnode.dev
VVarchasv Hoon·May 26Day 1 : Apache Spark InternalsUnderstanding how spark works5 min read·varchasvh.hashnode.dev
TTrung Thành·May 6I spent 6 hours studying PySpark join strategies. Here's what I learnedFrom broadcast to shuffle-hash: understanding how Spark executes joins under the hood6 min read·thanh-de.hashnode.dev