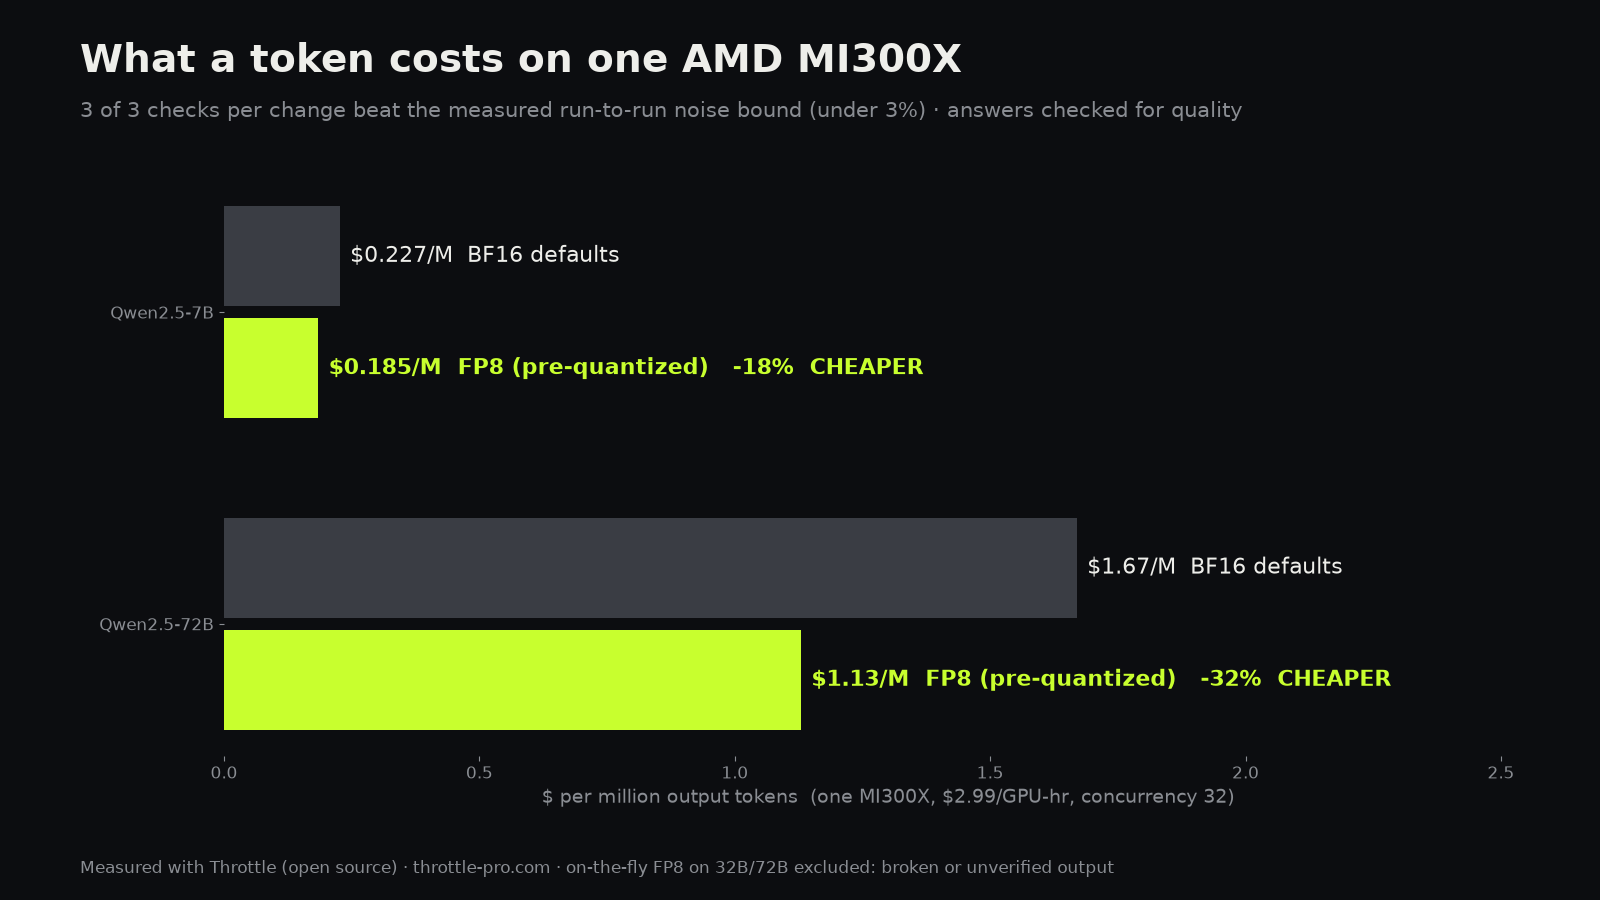
The FP8 trap: my GPU bill dropped 47% because the model was printing "!!!!!!"
I had one hour on an AMD MI300X and one question: what does a token actually cost on it?
One GPU, vLLM's ROCm build, Qwen2.5 at 7B, 32B and 72B. Thirty-two requests in flight, 256 output tokens max, p
throttle.hashnode.dev4 min read