SShraddha bhatOct 17 · 9 min readThe $8.2 Billion Bet on the Third Dimension: How AMD Just Changed the AI Race ForeverImagine walking into a room you’ve never seen before and instantly knowing where the exit is, how far the table is from the wall, and what it would feel like to pick up the coffee mug on the counter. aiinsights1909.hashnode.dev
SServers99Oct 16 · 8 min readKNOD Explained: Offloading Linux Network Traffic to AMD GPUsModern data centers are routinely pushing link speeds of 100Gbps to 400Gbps, creating a massive bottleneck for server infrastructure. While network interfaces can ingest data at blistering speeds, proservers99.hashnode.dev
GGayatri PanseOct 13 · 23 min readEpoch 1: Try It, Time It, Then Buy ItTL;DR vLLM vs llama.cpp: on a 20–24 GB card, vLLM fit 1.83 users at 32K context. llama.cpp fit ~13, because it needs 4× less KV-cache memory for Gemma 4. On AMD, four concurrent requests is the sweegradientdecent.hashnode.dev
MMIG serversOct 8 · 5 min readAMD EPYC 9006 "Venice" CPUs: Architecting the Agentic AI StackModern AI infrastructure has rapidly transitioned from static, monolithic training and inference clusters to highly dynamic Agentic AI pipelines. Unlike traditional models that rely on predictable commigservers.hashnode.dev
TThrottleOct 6 · 4 min readThe FP8 trap: my GPU bill dropped 47% because the model was printing "!!!!!!"I had one hour on an AMD MI300X and one question: what does a token actually cost on it? One GPU, vLLM's ROCm build, Qwen2.5 at 7B, 32B and 72B. Thirty-two requests in flight, 256 output tokens max, pthrottle.hashnode.dev
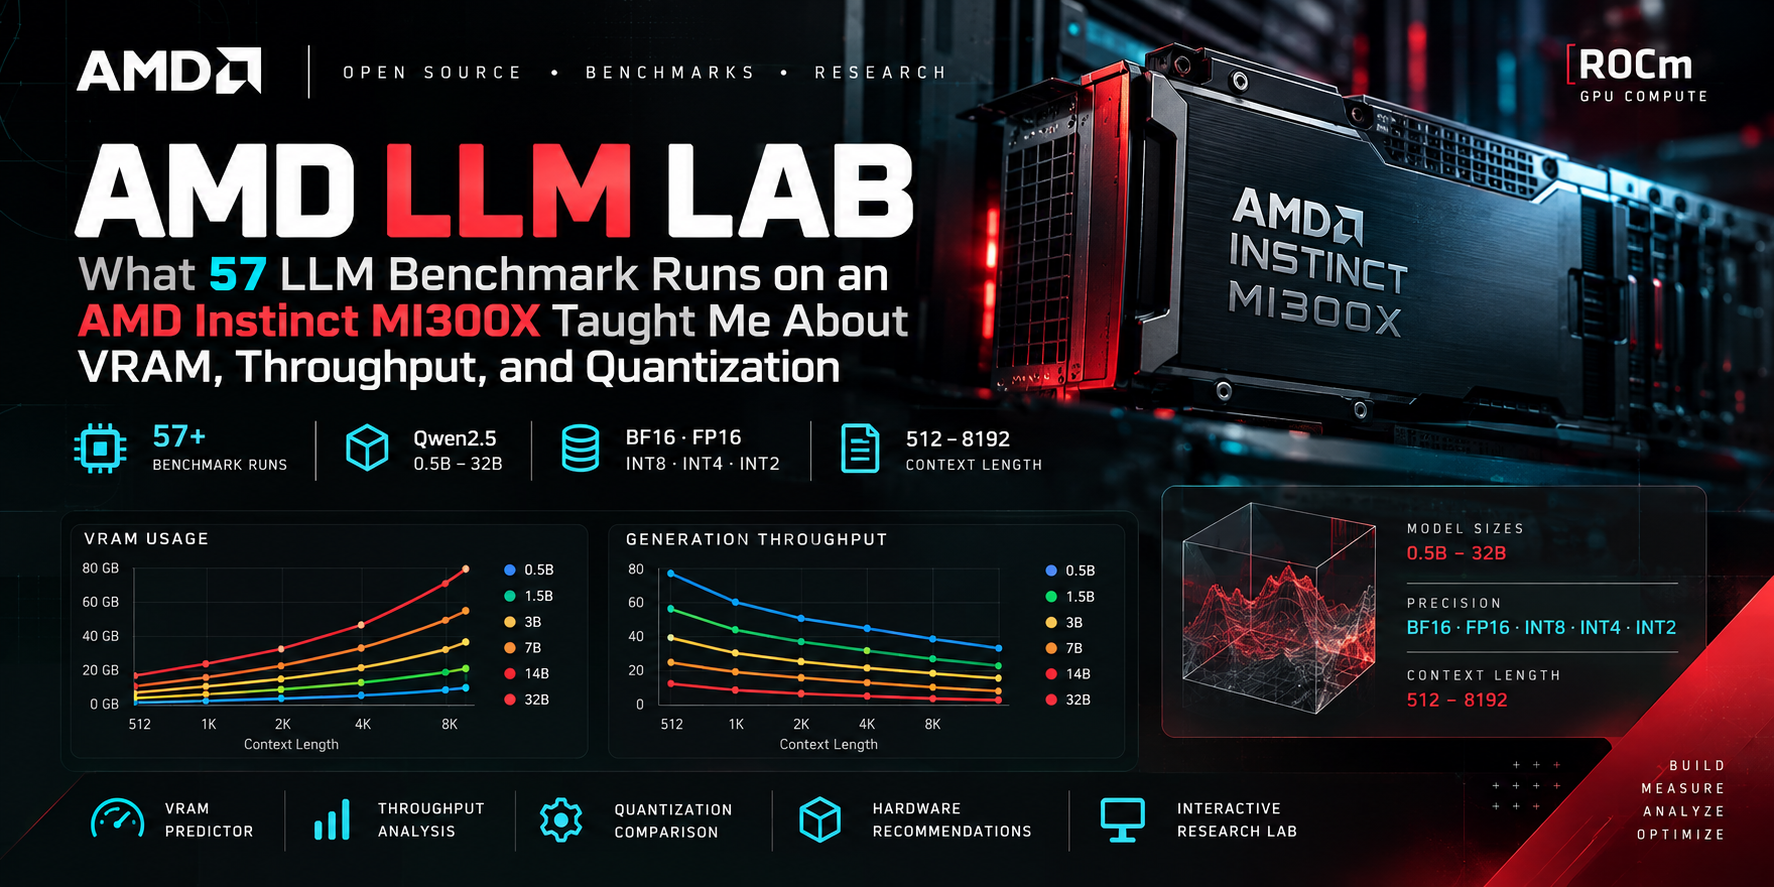
VVedant JadhavOct 3 · 7 min readWhat 57 LLM Benchmark Runs on an AMD Instinct MI300X Taught Me About VRAM, Throughput, and QuantizationHow much VRAM does a model actually need? How does model size affect generation speed? Does quantization always reduce memory? Does lower precision always make inference faster? I wanted to answer the13Avedantjadhav.hashnode.dev
JJosh GreenAug 1 · 5 min readA 30B Model Crawled on My Mini PC, and the Weights Were InnocentThere is a comfortable assumption in the local LLM world: if a model only activates a few billion parameters per token, it will run fast on modest hardware. Sparse mixture-of-experts models are sold o21Ajoshgreen.hashnode.dev
MManu ShuklaJul 28 · 14 min readROCm vs CUDA in 2026: can enterprises actually escape CUDA lock-in?ROCm vs CUDA in 2026: can enterprises actually escape CUDA lock-in? Summary. CUDA has been NVIDIA's real moat for 18 years, and 2026 is the first year that moat has visible cracks. AMD's ROCm 7, releaecorpit.hashnode.dev
DDustinVKJul 12 · 19 min readI Gave My Coding Agent a Free tierThere is a TL;DR section near the bottom if you just want the summary of setting it all up minus the story. Why host a model? The world of AI coding is moving at lightspeed in 2026. Every week I learnundefinedbehavior.hashnode.dev
BBrian KingJul 9 · 9 min readInstalling ROCm & Llama.cpp for CPUs & APUs.Abstract. I document my complete workflow for installing AMD ROCm drivers on Ubuntu Desktop 24.04 LTS and building the llama.cpp library with HIP (GPU) backend support for my AMD Strix Halo APU with isolodev.app