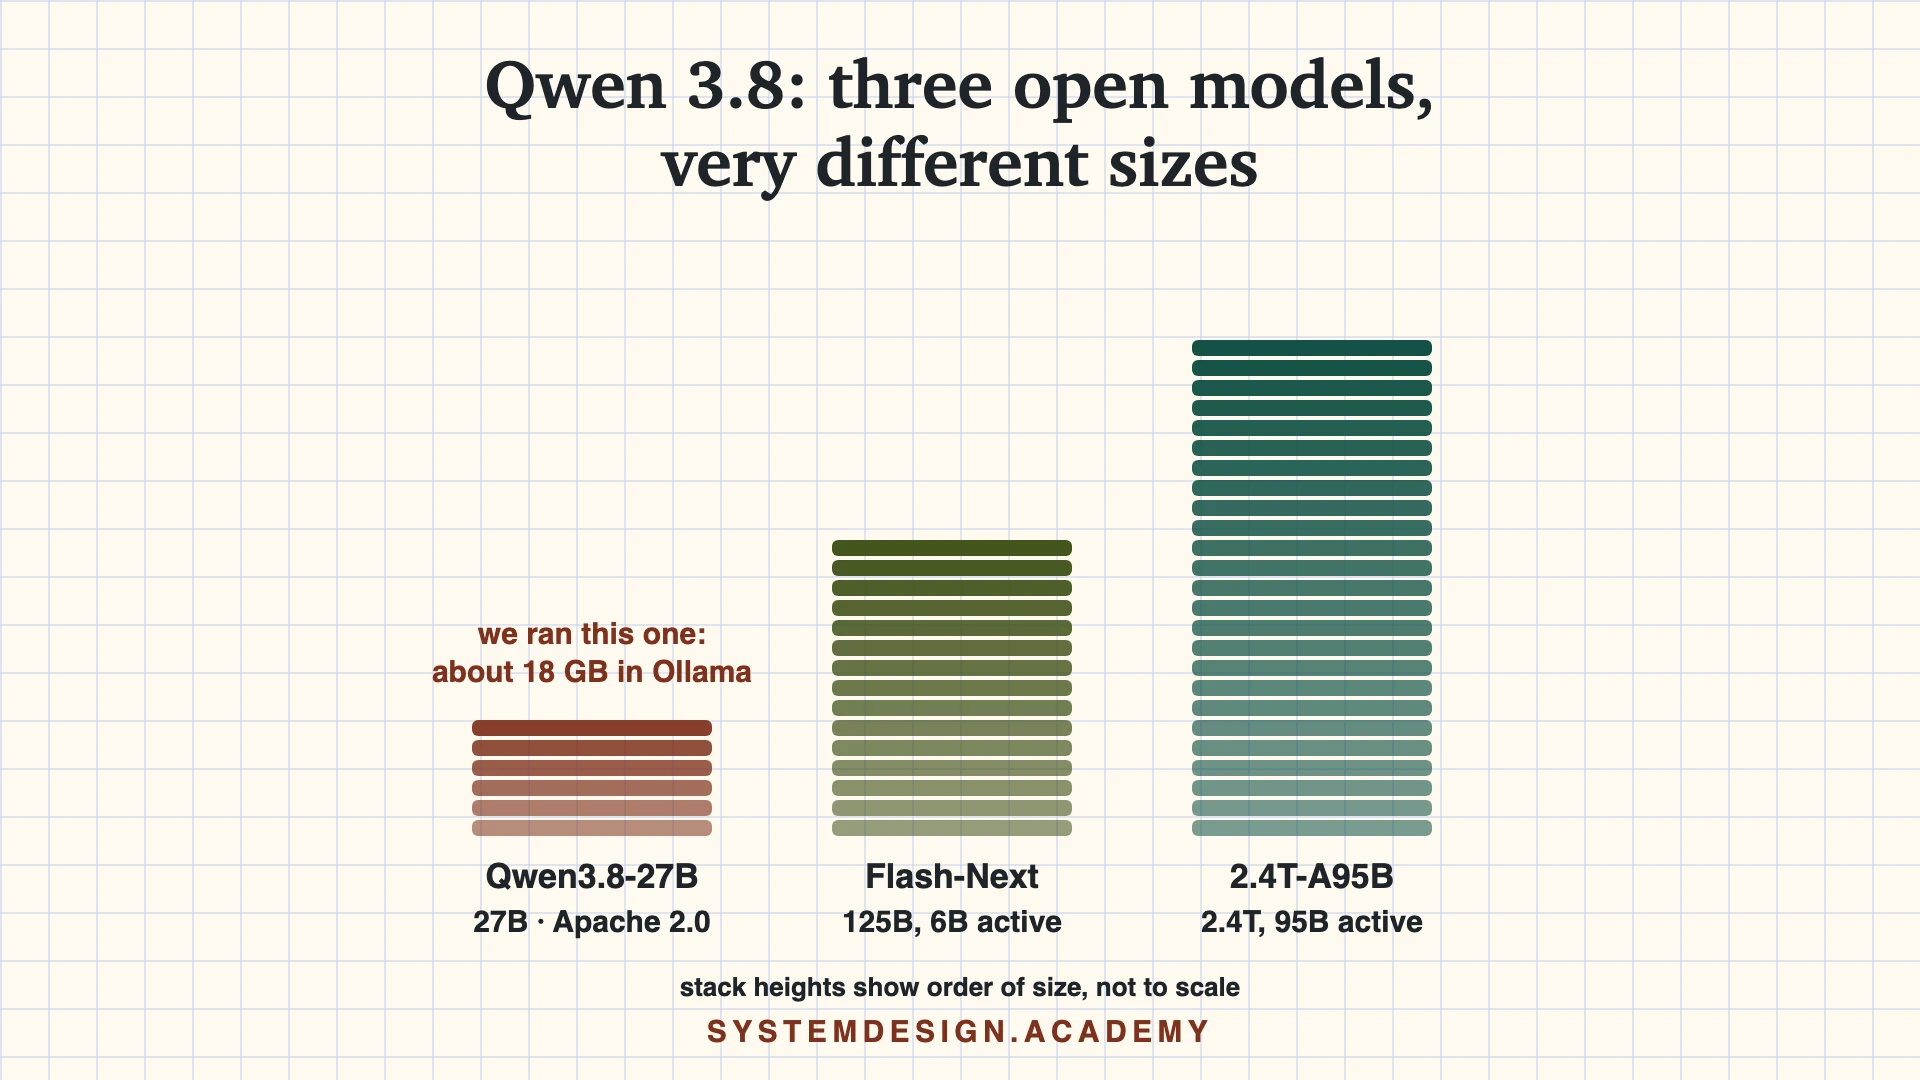
There is no 4B Qwen 3.8. The smallest open model is 27B, and here is what it took to run it on one rented GPU.
Qwen 3.8 has no 2B, 3B or 4B model. I pulled qwen3.8:27b into Ollama on a rented NVIDIA L4: 17.7 GB on disk, 18,004 MiB of GPU memory in use, 18 to 35 tokens a second once loaded.