AAbdulwaheed A A·2d agoWhy evals are the new A/B testsFor a long time, A/B test was one of the methods by which product teams answered questions around what good looks like. You shipped two versions, waited for traffic, and read the result. It worked wel5 min read·leveragepoints.io1
ZZyVOP·5d agoWhy LLM Apps Fail in Production: Six Failure Modes and How to Prevent ThemRate limits, broken JSON, runaway costs, silent regressions, blind spots and prompt injection: what goes wrong after the demo works, and the fixes that hold up.13 min read·blog.zyvop.com12J
AAgentOps Lab·6d agoWrite an Eval Case Brief Before You Score the Agent RunDon't dump a failure into a blank chat and ask for a score. Write an eval case brief first: one behavior, sanitized inputs, and pass/fail signals.7 min read·moneyprinterops.hashnode.dev
GGary Stafford·Nov 9Recursive Self-Improvement Meets a Strong Baseline AgentExperiments with OpenAI agents examine correctness headroom, efficiency gains, and whether autonomous revision earns its added complexity.16 min read·blog.latentthoughts.com
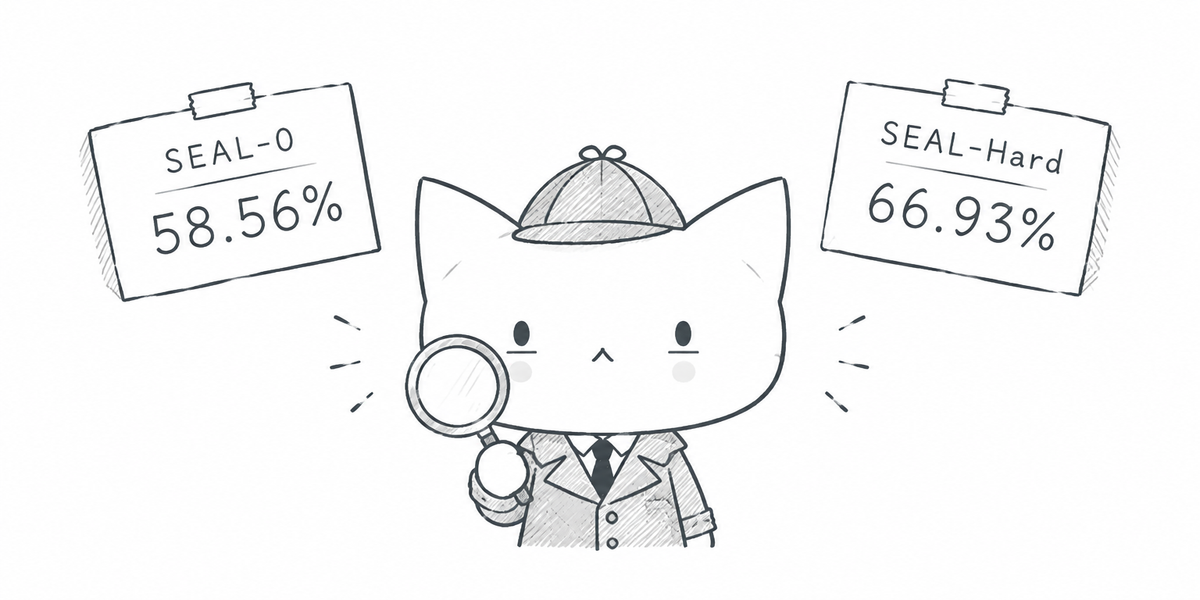
AAdarsh Divakaran·Nov 9SerpApi Achieves 58.56% Accuracy on SEAL-0 and 66.93% on SEAL-HardSerpApi achieved 58.56% accuracy on SEAL-0 and 66.93% on SEAL-Hard, pairing web search with page extraction to help an AI agent tackle tough factual questions.4 min read·serpapi.hashnode.dev
DDan Holloran·Nov 1LLM Evals Start as Thirty Test Cases, Not a PlatformYou tweak a system prompt to fix one bad answer a user reported. You try it on that example, it looks great, you ship. Two days later someone notices the feature now ignores the output format half the5 min read·grimicorn.hashnode.dev21K
GGil Neto·Oct 29My second brain scored 88% and still told me something falseOn 21 October a group of researchers published a benchmark for how personal agents remember what their users want (arXiv 2610.30485). They tested several memory systems against simulated users and mea5 min read·blog.gil-neto.com
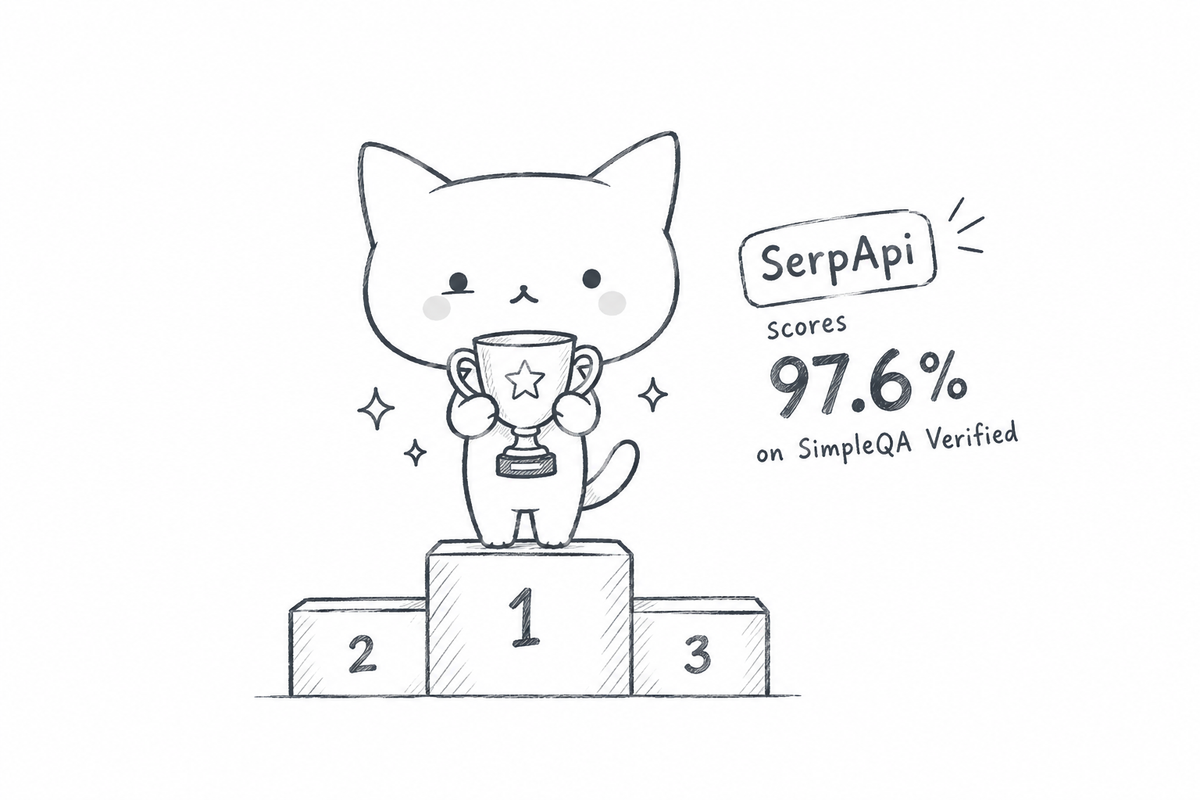
AAdarsh Divakaran·Oct 19SerpApi Achieves 97.6% Accuracy on SimpleQA VerifiedSerpApi scored 97.6% on SimpleQA Verified. We tested Google search data and the Extract API to see how well they help AI agents answer factual questions.4 min read·serpapi.hashnode.dev
AAyesha Khan·Oct 9Believable Is Not CorrectWhy I asked what problem an AI agent should solve first, and how metrics, monitoring and guardrails turn believable output into correct output.7 min read·ayeshakoder.hashnode.dev
OOliver Zehentleitner·Oct 5The Model Changed. My Skill Didn't. The Score Still Dropped.What agent evals taught me about moving model floors, noisy LLM judges, and treating the evaluator as part of the instrument9 min read·blog.technopathy.club