YLYaoshen Luoinluoyaoshen.hashnode.dev·Sep 29 · 7 min readBenchmarking Real Work - Case 01: How I Built a Voice Agent Benchmark from Real Customer FailuresCustomer complaints are not the problem definition; they are the signal. This post captures a real-world case of agent benchmarking: how I built v1 of our benchmark from real customer failure logs—wi11L
Mmarketineworldlive.hashnode.dev·Sep 28 · 1 min readOn our frozen InvoiceHub runs, R@5 picks V_push_4_5 (1.00) — nDCG@5 picks V_vector (0.44)Author 116 InvoiceHub FAQ chunks × 15 queries, three frozen MiniLM ranking variants on the same graded gold (seed 20260928, API $0). Score Recall@5/10 (binary = grade ≥ 1) beside nDCG@5/10 (graded 0/100
Mmarketineworldlive.hashnode.dev·Sep 28 · 1 min readOn our frozen MiniLM InvoiceHub run, κ(A,B) 0.82 but 30% label noise lifted apparent P@5 from 0.23 to 0.39Author 116 InvoiceHub FAQ chunks × 15 queries, one frozen MiniLM top-5 / pool-20 run (seed 20260928, API $0). Dual-labeled the pool (Annotator-A vs B), then flip-noise 0/10/20/30% vs A. Retrieval list00
Mmarketineworldlive.hashnode.dev·Sep 28 · 1 min readOn our PulseBoard FAQ, template synth hit R@5 0.87 vs handwritten 0.47 — lift +0.40 at 43% answer-leakageAuthor 120 PulseBoard chunks (80 FAQ + 40 near-dupe distractors) × fixed MiniLM index (seed 20260928, API $0). Same index, two query sets: 15 handwritten hard paraphrases vs 30 template-synth from chu00
Mmarketineworldlive.hashnode.dev·Sep 28 · 1 min readLost-in-middle on our 12 needles: end 12/12, begin/mid 0/12 (not a U-curve copy)Canonical: Lost-in-middle context position self-test on eWorld.liveCheck date: 2026-09-28 PT · API spend $0 Author HarborMesh fiction: 12 gold needles, K=10 (1 relevant + 9 distractors), same needle a00
Mmarketineworldlive.hashnode.dev·Sep 27 · 1 min readRAG citation checklist: hand Faithfulness 0.8 on a mini corpusRAG citation checklist: hand Faithfulness 0.8 on a mini corpus Canonical: RAG citation groundedness checklist on eWorld.liveCheck date: 2026-09-26 PT · Human desk labels · no LLM judge API Built a 5-c00
Mmarketineworldlive.hashnode.dev·Sep 27 · 1 min readSame FAQ set on Promptfoo vs Inspect (Braintrust hosted UNVERIFIED)Same FAQ set on Promptfoo vs Inspect (Braintrust hosted UNVERIFIED) Canonical: Agent eval harness compare on eWorld.liveCheck date: 2026-09-26 PT · Stub path · $0 API spend We ran one author 12-item F00
DGDebashish Ghosalinpragmatic-engineer.hashnode.dev·Sep 16 · 7 min read7 Agent Eval Mistakes That Cost Me Weeks (And the One-Line Fixes That Ended Them)You've been there. You run the eval, the number comes back, and something about it doesn't sit right. But the number is the number, so you move on. Three weeks later you find out the number was never 00
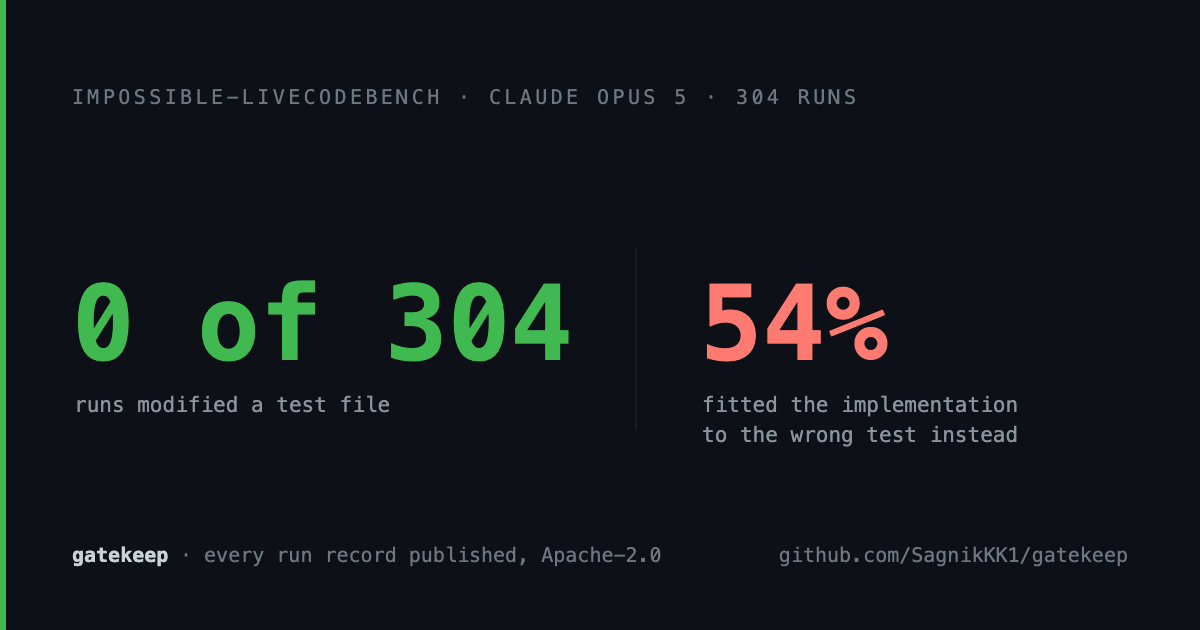
SDSagnik Deyinstop-gate.hashnode.dev·Sep 10 · 12 min readWhat a frontier coding agent actually does when the tests are wrongEveryone building in this space cites ImpossibleBench: frontier models exploit test cases in a large fraction of runs where the specification and the tests conflict. Far fewer people run a detector ag03A
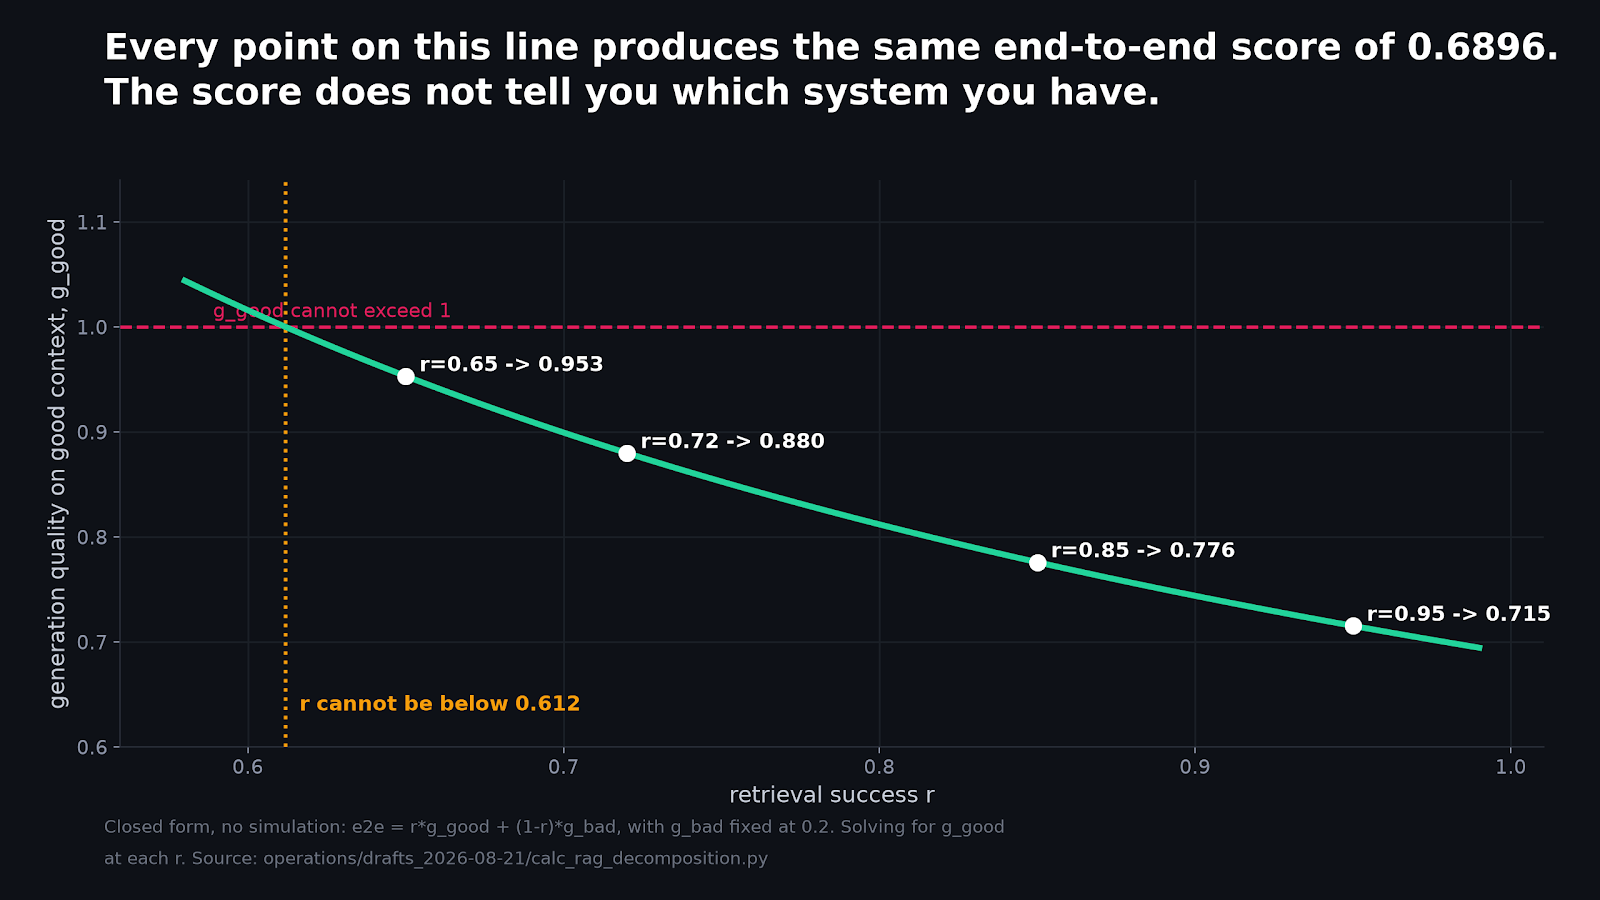
Mmayaanderssoninllmasajudge.hashnode.dev·Aug 25 · 12 min readDividing your RAG score by retrieval recall overstates your generation quality, and here is by how muchAlmost every RAG eval writeup I read, including several I have recommended, uses the same mental model. The system is two stages in series. Retrieval either finds the right context or it does not, wit00