KGKunal Guptainkunalforked.hashnode.dev·Aug 20 · 3 min readWhy “Just Retry the Request” Isn’t Always Safe This is pretty simple, but I thought it was interesting enough to share. Recently I was reading about idempotency and retries, and it made me realize how something as innocent as “just retry the reque10
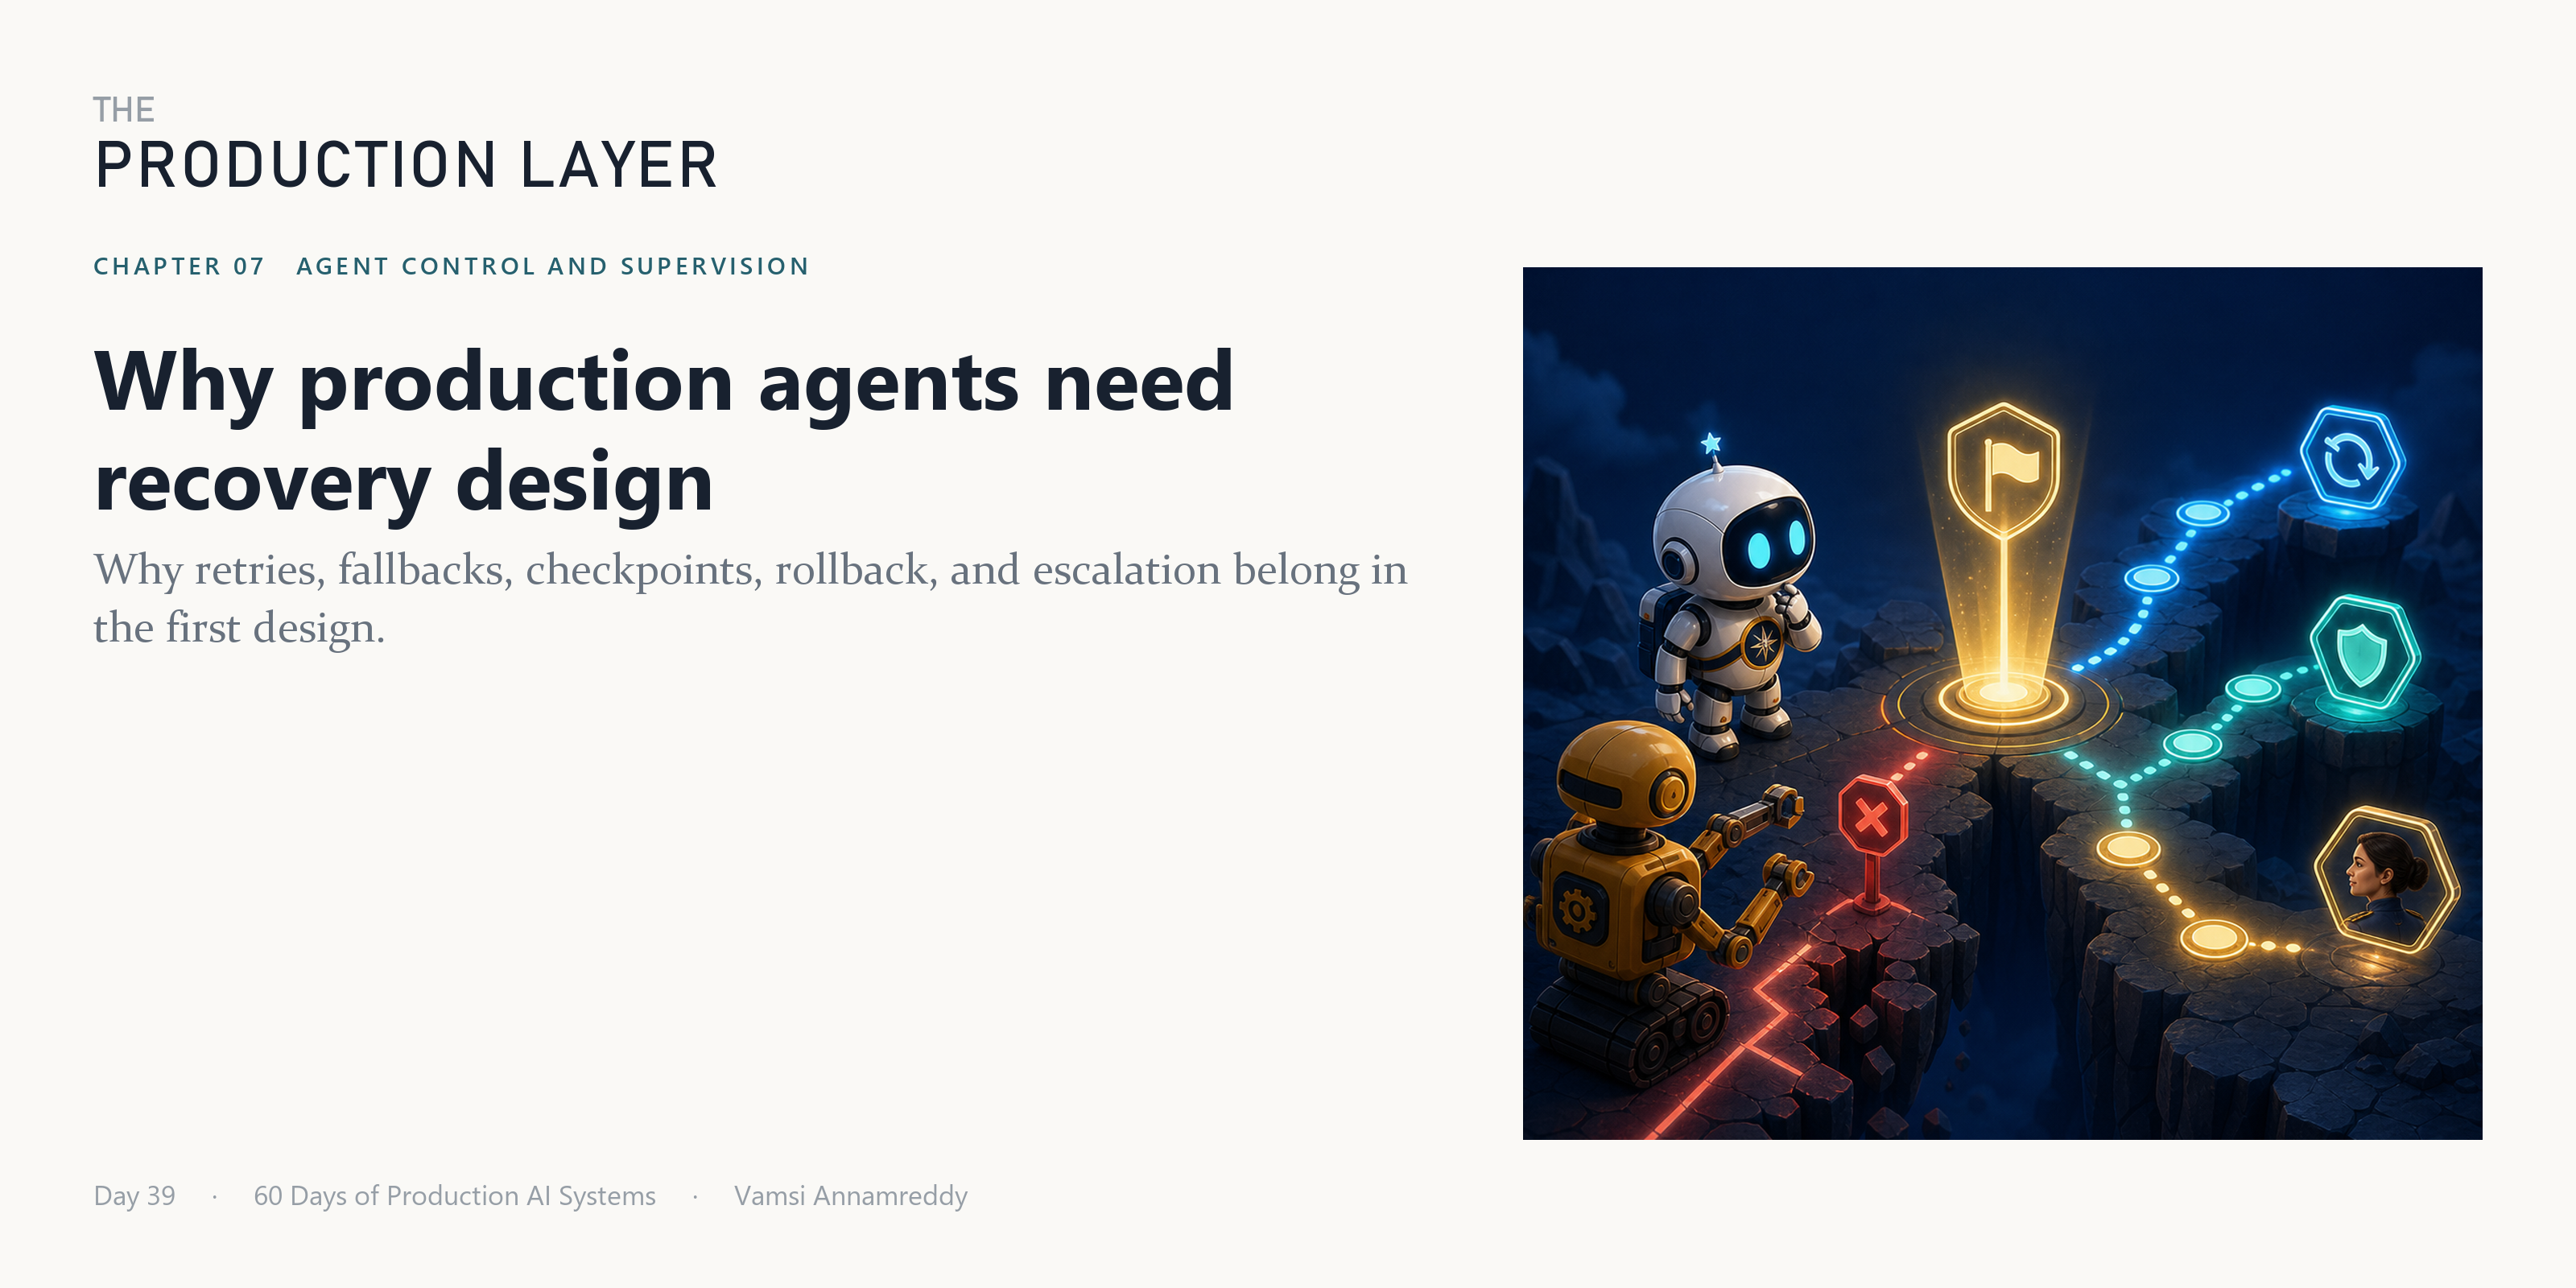
VKVamsi Krishnainblog.vamsiannamreddy.com·Jun 29 · 3 min readDay 39: Why production agents need recovery designThe most dangerous agent state is not "failed." It is failed halfway. Three of seven records updated. The notification sent but the database write lost. A workflow abandoned mid-transaction with no re00
NVNguyễn Việt Tùngindevpath-traveler.nguyenviettung.id.vn·Apr 19 · 19 min readBFF Resilience Patterns: Circuit Breakers, Retries & Timeouts with PollyA BFF that aggregates four upstream services inherits four independent failure modes. Any one of them can be unavailable, slow, or intermittently returning errors at any time. The question is not whet00
SSSurya Sathiinsystems-notes.hashnode.dev·Jan 19 · 10 min readWhy Distributed Systems Can't Know What's HappeningBackground When we write programs, we have a quiet assumption that goes unnoticed until it gets explicitly questioned — when you send a request, it either succeeds or fails; even when you query a data00