RRavi Sanchala20h ago · 5 min readHow I cut incident response time by 40% without buying new toolsIt's 2am. Your phone buzzes. It's not an alert, it's a customer: "Is the app down?" You open your laptop, SSH into a server and start scrolling through logs, hoping something jumps out. Forty minutes ravisanchala.hashnode.dev
Jjaberadam20011d ago · 11 min readPostmortem Root Cause Analysis: Why One Root Cause Means the Incident Comes BackHere's a quick exercise. On the morning of August 1, 2012, all five of these were true at a US trading firm called Knight Capital. By the end of roughly 45 minutes, the firm had lost more than $460 misimplyexplained.hashnode.dev
PParsa Mohammadi2d ago · 2 min readChange Risk Management in Software EngineeringChange risk management is the process of understanding and controlling the potential production impact of software changes. It is not one tool or one review step.A useful lifecycle is:Change → Review tomosu.hashnode.dev
TThankGod Chibugwum Obobo2d ago · 10 min readRemote DevOps Jobs in Nigeria: How to Build a Global Engineering Career from LagosLagos is one of the most demanding places in the world to be an infrastructure engineer. It is also one of the most underrated places to build a global DevOps career from. You are expected to keep sysactocodes.hashnode.dev
BBiswadip Majumdar3d ago · 8 min readFrom SRE to AI Infrastructure Engineer: A Practical Learning RoadmapWhy experienced SREs don't need to become ML researchers to work on AI, and what to learn instead. I have spent more than 17 years in site reliability and platform engineering, and when I look at how warrator.hashnode.dev
Uupordown.online3d ago · 5 min readWhat "three nines" really buys you: turning uptime percentages into minutesUptime percentages are easy to promise and hard to feel. "99.9%" sounds almost perfect. "We may be down for 43 minutes every month" sounds like something you'd want to discuss first. They are the sameupordownonline.hashnode.dev
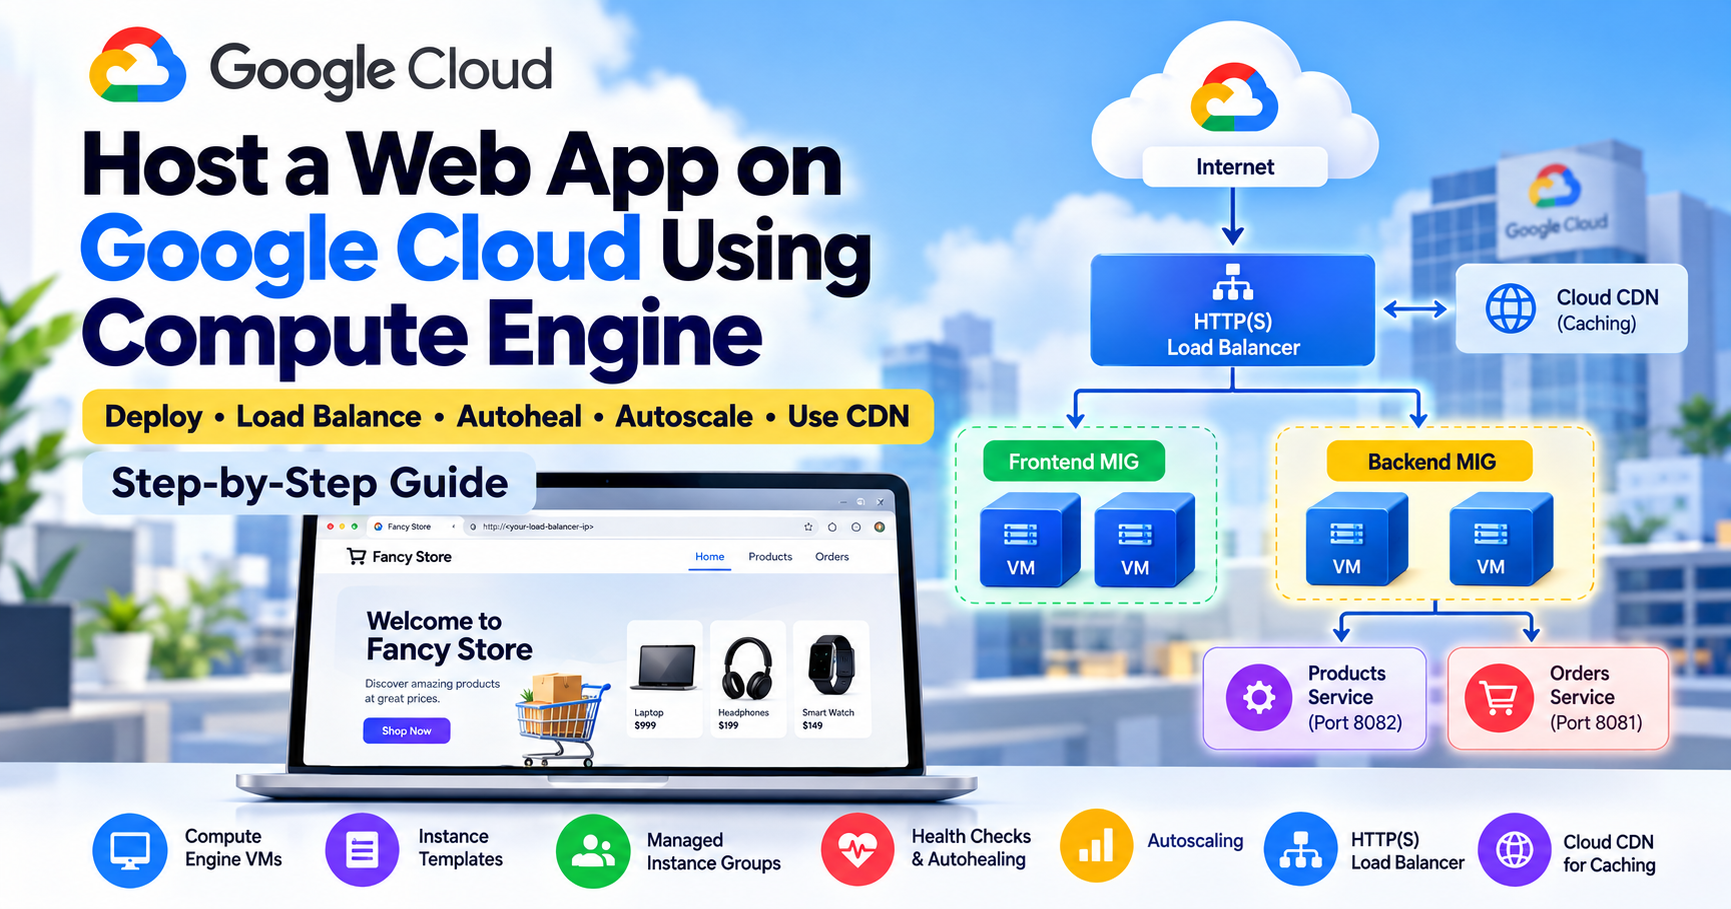
YYashvi Kothari3d ago · 31 min readHow to Host a Web App on Google Cloud Compute Engine (and Scale It)From a single virtual machine to a load-balanced, self-healing web application: a hands-on Google Cloud deployment guide. A website that works is not necessarily a website that's ready to scale. Imagiyashvikothari.hashnode.dev
FFerhat Yildiz5d ago · 16 min readSite Reliability Engineering: A Practical Introduction for EngineersIn 2003, Benjamin Treynor Sloss joined Google to lead a production team of seven engineers. He approached the job as a software engineer: instead of relying on people to repeat operational tasks, buil21Ablog.turingts.com
GGonzalo Gjuka5d ago · 5 min readAnatomy of a multi-cloud deploy that failsFriday, 6:10pm. The terraform plan says "12 to add, 3 to change, 1 to destroy". You read it, nothing looks odd. Apply. Green bar. You get up for a coffee and when you come back the alerts channel has controlcloud.hashnode.dev
GGonzalo Gjuka5d ago · 4 min readOperating windows in non-prod: governance with an audit log vs scattered cron scriptsThe arithmetic is easy: a QA environment that runs 24/7 but is only used from 9 to 7, Monday to Friday, is powered on three times longer than it needs to be. Shutting it down outside those hours can ccontrolcloud.hashnode.dev