PPrasad Kukkala·4d agoGoogle TPUs Are Coming to Oracle Cloud. Does That Change the AI Lock-In Problem?Google TPUs are coming to Oracle Cloud in 2027. Learn what this changes for AI infrastructure, cloud lock-in, portability, and enterprise decisions.15 min read·techies-journal.hashnode.dev
JJakson Tate·Nov 13NVIDIA Dynamo Guide: Scaling Distributed LLM Inference on Bare MetalA complete SRE blueprint covering NIXL transports, KV cache tiering, Kubernetes v1beta1 orchestration, and observability for bare-metal GPU clusters.13 min read·servermo.hashnode.dev
JJakson Tate·Nov 13How to Install and Scale NVIDIA NeMo on Bare MetalA step-by-step SRE blueprint to deploy NeMo via Docker, scale with Megatron-Core 3D parallelism, tune RLHF memory, and fix OOM errors.8 min read·servermo.hashnode.dev
NNathanael FETUE·Oct 30Attaching XDP without leaving a trace: bpf_link, kill -9 and a signal mask nobody testsBuilding AgentXDP, part 9. Previous: part 8, a lock-free queue broken on purpose. Next: part 10, a metrics endpoint a slow client cannot stall. An observability agent must do no harm. If it crashes, o4 min read·pegasus-nathanael-tech.hashnode.dev
WWeiwei Zhang·Oct 9NVIDIA B200 vs. B300 vs. GB200 vs. GB300: What Changes in AI Cluster Networking?Compare NVIDIA B200, B300, GB200, and GB300 cluster architectures, including InfiniBand vs. Ethernet, 400G/800G networking, optical transceivers.10 min read·aicplight.hashnode.dev
ZZyVOP·Sep 28Brick: The LLM Router That Skips the Cascade and Still Cuts Your BillHow Regolo.ai's open-source router picks a model per query, and a benchmark metric worth understanding before you cite the headline number.11 min read·blog.zyvop.com
ZZyVOP·Sep 25Can a $2,000 Mini PC Replace Your AI Cloud Bill?AMD's Strix Halo chips can run 120B-class models locally. Here's what the benchmarks, power costs, and real-world agent workflows actually look like.11 min read·blog.zyvop.com
JJoselo Martinez·Sep 16Agentic AI Beyond the Hype: Why the Boundaries Are Key in Deterministic and Non-Deterministic Behavior for Agents90% of LLM systems fail in production due to rigid controls. Discover how to architect deterministic boundaries and handle uncertainty in your agents.4 min read·designednotmagic.hashnode.dev2JB
IIvan Porta·Aug 27From Ingress to Inference Gateway: Gateway API and the Inference ExtensionHow Kubernetes networking became model-aware: the Gateway API resource model, the Inference Extension's InferencePool, and the endpoint picker that routes on KV-cache and queue metrics instead of round-robin.19 min read·todea.hashnode.dev
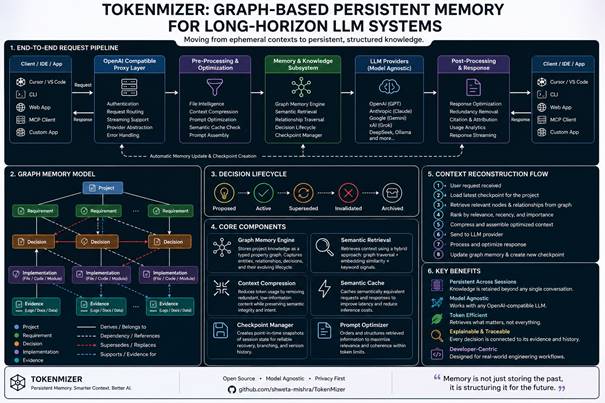
NNeural CoreTech·Jul 29Are million-token context windows taking us in the wrong direction? How TokenMizer Introduces a Graph-Based Architecture for Long-Horizon AI Reasoning1 min read·neuralcoretech.hashnode.dev