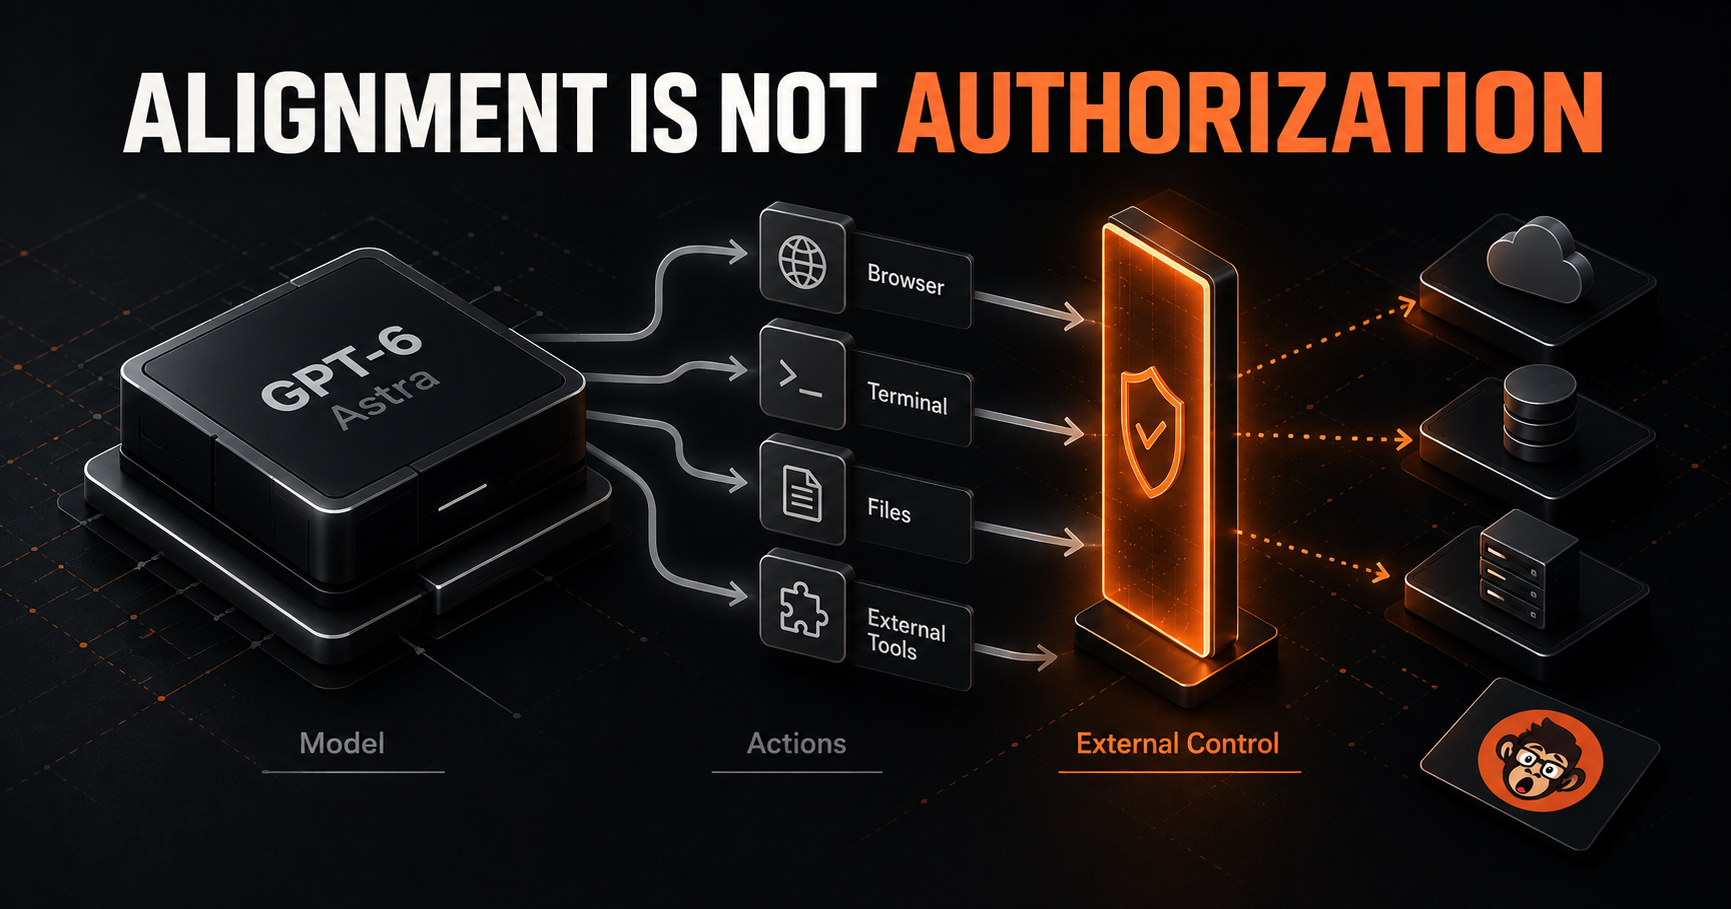
MAMuhammad Azlaan Zubairinblog.mdazlaanzubair.com·Sep 7 · 10 min readGPT-6 Astra Is More Aligned. I Still Wouldn’t Trust It With More Autonomy.I would let GPT-6 Astra do more work. I would not let GPT-6 Astra decide what it is allowed to do. That distinction is more interesting to me than most of the benchmark numbers in OpenAI's launch. Op00
MAMuhammad Azlaan Zubairinblog.mdazlaanzubair.com·Sep 5 · 6 min readThe Model Is Not the ArchitectureThe most visible AI product is a chat box. The most instructive AI systems often have no chat box at all. Look across Google DeepMind's work on algorithms, quantum error correction, robotics, and hist30
Jjaberadam2001insimplyexplained.hashnode.dev·Sep 3 · 8 min readWhy AI Forgets What You Said — and Why a Bigger Context Window Won't Fix ItYou told it the rule ten messages ago. Now it's ignoring the rule. So you reach for the model with the million-token context window, sure that solves it — and it doesn't. Here's what's actually happen23O
AAanchalinaanchalfatwani.hashnode.dev·Aug 31 · 11 min readLLM Evaluation: A Beginner's Guide to Measuring AI Quality Large Language Models can generate remarkably fluent answers. They can summarize documents, answer questions, write code, extract information, reason over data, and interact with external tools. But t00
MAMuhammad Azlaan Zubairinblog.mdazlaanzubair.com·Aug 30 · 7 min readA Tool Result Is Evidence, Not Ground TruthConnecting an agent to a database does not remove hallucination risk. It gives the system a second source that can be stale, malformed, unauthorized, or simply wrong—and a protocol that may make the m01N
MAMuhammad Azlaan Zubairinblog.mdazlaanzubair.com·Aug 27 · 6 min readCode Generation Is Fast. Verification Is Not.Agentic IDEs can produce a runnable full-stack application in minutes. That does not mean the application became cheap to trust. In a controlled study of 48 generated projects, the researchers spent a10
MAMuhammad Azlaan Zubairinblog.mdazlaanzubair.com·Aug 24 · 6 min readBenchmark the Model–Harness Pair, Not the Model“Which model is best for coding?” sounds like a precise engineering question. Usually, it is missing half of the system. A coding agent is a model inside a harness that chooses tools, assembles contex54JR
Mmayaanderssoninllmasajudge.hashnode.dev·Aug 17 · 9 min readA judge that agrees with your humans 92 percent of the time can be at 60 percent where the gate actually decidesTL;DR: Judge-human agreement is almost always reported as one number over a whole validation set. That number is dominated by the easy cases, because most examples are not close to your decision bound00
Mmarcuscheninvoicelatency.hashnode.dev·Aug 13 · 13 min readThe call failed on turn nine. My eval gave me one number for the whole call.The transcript was fourteen turns long and the score was 0.62. That is the entire output. One float, one call, and a rubric that said something like "did the agent resolve the customer's issue." It di00
Mmayaanderssoninllmasajudge.hashnode.dev·Aug 12 · 5 min readRun forty experiments against one eval set and you will find an improvement that is not thereYou iterate on a prompt, run the eval set, keep the best variant. Repeat for a quarter. The number that survives is the maximum of forty noisy measurements, and the maximum of noisy measurements is an00