TTaha hussein·Oct 20Fine-Tuning vs LoRA vs QLoRA: Understanding Efficient LLM AdaptationLearn how Fine-Tuning, LoRA, QLoRA, and KD-LoRA help customize AI models. Explore key differences, benefits, and LLM adaptation techniques.5 min read·tahahussein.hashnode.dev
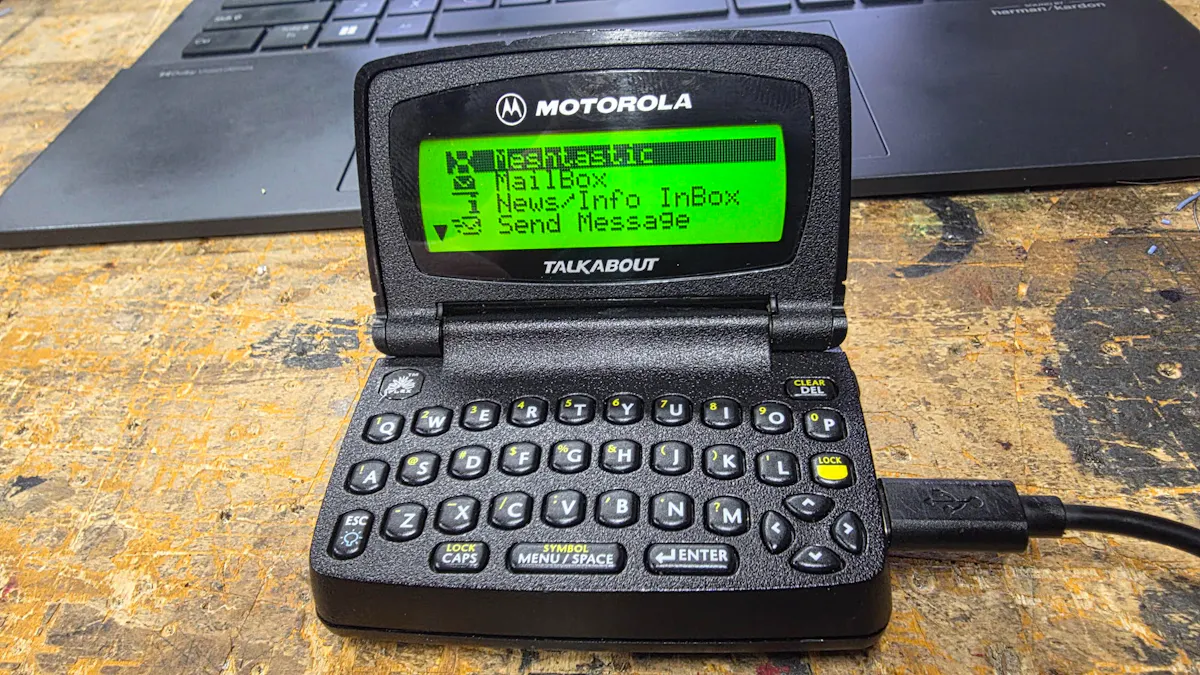
Ccircuitrocks·Oct 20Motorola T900 Pager Mod: Meshtastic Messaging on ESP32-S3Motorola T900 Pager Mod: A Motorola T900 pager gets a Heltec V4 brain and LoRa mesh messaging while keeping its keyboard and LCD.2 min read·circuitrocks.hashnode.dev
Ccircuitrocks·Sep 27IronEar's ESP32-S3 Sensor Hears 500 Sounds, Skips the CameraIronEar's ESP32-S3 Sensor Hears: An open-source ESP32-S3 sensor node classifies 500+ household sounds on-device and reports to Home Assistant over MQTT or…3 min read·circuitrocks.hashnode.dev
Ccircuitrocks·Sep 24Off-Grid LoRa Message Board Pairs ESP32-S3 with E-Ink DisplayOff-Grid LoRa Message Board: A battery-powered desk display that receives text messages over a LoRa mesh network with no WiFi needed, plus a built-in CO2…2 min read·circuitrocks.hashnode.dev
TTaha hussein·Sep 18Fine-Tuning an LLM: What Actually Happens Under the Hood?Learn how LLM fine-tuning works under the hood, including training, parameters, LoRA, PEFT, and the differences between fine-tuning, RAG7 min read·tahahussein.hashnode.dev
RRahul Sai Indeevar V·Sep 16Parameter-Efficient Fine-Tuning: From LoRA to QLoRAFine-tuning Large Language Models (LLMs) used to be an option only for organizations with massive compute budgets. Full fine-tuning requires updating and storing every parameter, gradient, and optimiz10 min read·rahul-ai.hashnode.dev2
PPartha·Sep 15LoRA, QLoRA, or Distillation? A No-Nonsense Guide to ChoosingIf you've ever tried to fine-tune a large language model on normal hardware, you know the wall you hit fast. A 7-billion-parameter model trained the old-fashioned way can eat 100+ GB of GPU memory. Mo12 min read·rpsarathy.hashnode.dev
IInternals Decoded·Sep 2Fine-Tuning, Explained: Teaching an Old Model New TricksWhen it helps, when RAG beats it, and why most teams never need it.15 min read·internals-decoded.hashnode.dev
RRahul Sai Indeevar V·Aug 28Understanding LoRA: Parameter-Efficient Fine-Tuning for Modern LLMsLarge Language Models (LLMs) and foundation models like LLaMA, GPT, and ViTs have billions of parameters. As these models scale, traditional full fine-tuning—updating every weight in the network—becom9 min read·rahul-ai.hashnode.dev1
RRahul Sai Indeevar V·Aug 26A Field Guide to Modern AI TerminologyA clear, developer-focused guide breaking down modern AI terminology—from LLMs and Agentic AI to RAG and LoRA.8 min read·rahul-ai.hashnode.dev1