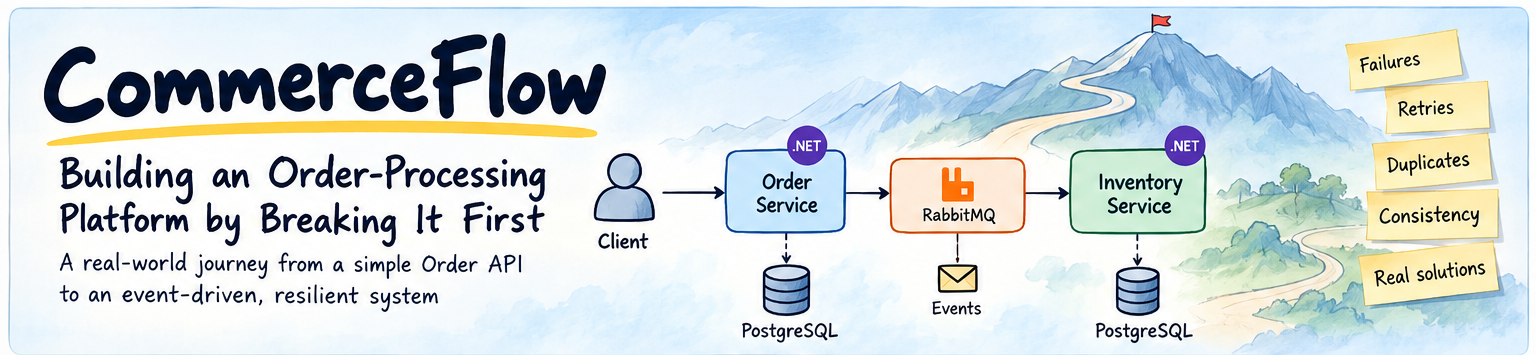
RRakesh BhandarkarSep 24 · 11 min readCommerceFlow: What I’m building, how an order moves through the system, and the engineering problems shaping the architecture CommerceFlow is an order-processing platform I’m building from the ground up. The starti2Brakesh-code-lab.hashnode.dev
KKashif RezaSep 8 · 7 min readHandling Duplicate Events Safely with IdempotencyIn the previous article, we looked at retries and DLQ. Retries help you recover from temporary failures. But they also create a new risk: The same event may be delivered, retried, or processed more tarchitecture-in-practice.hashnode.dev
KKashif RezaSep 7 · 7 min readRetry Strategy in Event-Driven Systems: Resilience or Retry Storm? Retries usually start with good intent. Typical transient failures in distributed systems A network call times out.A database becomes slow.A downstream API is unavailable. These are not edge cases. T1architecture-in-practice.hashnode.dev
KKashif RezaSep 3 · 10 min readClosing the Gap Between DB Commit and Event Publishing with the Outbox PatternHow the Outbox Pattern makes event publishing durable after a business transaction succeeds In the previous article, we saw a dangerous failure window: Save business data Commit DB transaction Publisharchitecture-in-practice.hashnode.dev
AAwais AhmadJun 19 · 6 min readHow Software Systems Evolve: From MVP to Modern ArchitecturesMost system design discussions jump straight into complex architecture patterns—monoliths, microservices, event-driven systems, and distributed databases. But in real engineering, systems don’t begin blog.itsahmadawais.com
HHarrison GuoMay 14 · 18 min readChannels Aren't Message Passing — How Parked Goroutines OOM-Killed a PodIt's 3am. The Kafka consumer pod that's been running cleanly for six weeks gets OOM-killed. Kubernetes restarts it. Five minutes later: OOM-killed again. Restart. OOM-killed a third time. By the fourtharrisonsec.hashnode.dev
AAkshat JainMay 9 · 3 min readScaling Myths That Mislead DevelopersWhy common assumptions about scaling lead to fragile systems Scaling is often seen as a technical problem. More users arrive, and the system needs to handle increased load. However, many scaling failures are not caused by lack of resources.They are c...akshatjme.hashnode.dev
AAditya TrivediMay 7 · 7 min readLeetcode System DesignThe first thing people usually do while designing systems is jump directly into databases, microservices, Kubernetes, Redis, queues, and scaling. That is the wrong approach. When designing systems likadityatrivedi.hashnode.dev
AAkshat JainMay 7 · 3 min readWhy Your APIs Feel Slow (Even When They Aren’t)Understanding the gap between actual performance and perceived latency In previous parts, we explored how backend systems behave under load and how design decisions impact performance. However, not all performance issues come from slow systems. In ma...akshatjme.hashnode.dev
AAkshat JainMay 3 · 3 min readObservability: You Can’t Fix What You Can’t SeeUnderstanding system behavior beyond logs and dashboards In previous parts, we explored how systems fail under load and how design decisions influence performance. But identifying failures is a different challenge. A system may be slow, unstable, or ...akshatjme.hashnode.dev