© 2026 Hashnode
Speculative decoding became the standard inference speedup technique through 2024 and 2025. The idea: a small draft model generates a sequence of candidate tokens, and a larger target model verifies them in parallel — accepting the longest valid pref...
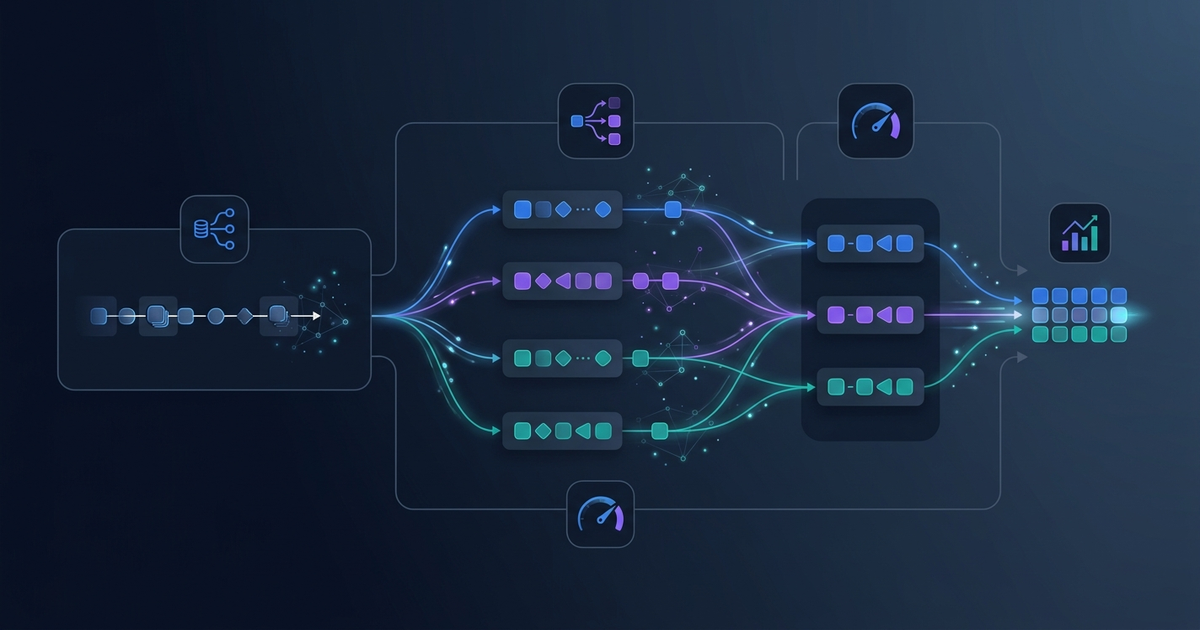
On May 5, 2026, Google released Multi-Token Prediction (MTP) drafters for the Gemma 4 family. The headline claim — up to 3x inference speedup — is technically accurate on specific hardware. The more realistic number for most developer setups is 1.7x ...
Every production LLM deployment using speculative decoding is likely running a fixed speculation length of γ=4. That number comes from early benchmarks, it has been copy-pasted across blog posts and framework defaults, and almost nobody questions it....